This is the multi-page printable view of this section. .
Concepts
- 1: Architecture
- 1.1: Nodes
- 1.2: Infrastructure
- 1.3: PGSQL Arch
- 2: ER Model
- 3: Infra as Code
- 3.1: Inventory
- 3.2: Configure
- 3.3: Parameters
- 3.4: Conf Templates
- 3.5: Use CMDB as Config Inventory
- 4: High Availability
- 4.1: RPO Trade-offs
- 4.2: Failure Model
- 4.2.1: Model of Patroni Passive Failure
- 4.2.2: Model of Patroni Active Failure
- 4.2.3: Network Partition
- 4.3: RTO Trade-offs
- 4.4: Service Access
- 5: Point-in-Time Recovery — A Time Machine for PostgreSQL
- 5.1: How PITR Works
- 5.2: PITR Architecture
- 5.3: PITR Tradeoffs
- 5.4: Declarative Recovery
- 5.5: PITR Scenarios
- 6: Monitoring System
- 7: Security and Compliance
- 7.1: Security Model
- 7.2: Authentication
- 7.3: Access Control
- 7.4: Encrypted Communication
- 7.5: Data Security
- 7.6: Compliance
Pigsty is a portable, extensible, open-source PostgreSQL distribution. It uses declarative configuration and automation to build production database services in local environments. Its tools, scripts, and operating practices support PostgreSQL services at enterprise RDS levels.
Pigsty means PostgreSQL In Great STYle. It also means Postgres, Infras, Graphics, Service, Toolbox, it’s all Yours. It provides self-hosted PostgreSQL with graphical monitoring. Find source code on GitHub and information in the official documentation. Try the Web UI in the online demo.
Why Pigsty? What Can It Do?
PostgreSQL provides the database engine. Production service also requires high availability, backup and recovery, monitoring and alerts, access control, tuning, extensions, connection pools, and load balancing.
Pigsty automates this operational work.
Pigsty provides:
Ready-to-Use PostgreSQL Distribution
Pigsty integrates 600 extensions for distributed, time-series, geographic, spatial, graph, vector, search, and other multi-modal workloads. It provides production database services for PostgreSQL 14–18 on EL, Debian, and Ubuntu.
Self-Healing High Availability Architecture
The high availability architecture uses Patroni, Etcd, and HAProxy for automatic hardware failover and traffic routing. Primary failure recovery has RTO < 45s and RPO ≈ 0. Cluster maintenance and upgrades can proceed in sequence without application coordination.
Complete Point-in-Time Recovery Capability
pgBackRest and an optional Silo object-storage cluster provide point-in-time recovery (PITR). Recover quickly to a selected time after software defects or accidental data deletion.
Flexible Service Access and Traffic Management
HAProxy, Pgbouncer, and VIP provide service access with read/write separation, connection pools, and automatic routing. These components provide stable, high-performance database access with transaction pooling.
Monitoring and Diagnostics
VictoriaMetrics and Grafana provide monitoring practices with more than three thousand metric types. Views range from global dashboards to CRUD operations on individual objects.
Declarative Configuration Management
Pigsty follows Infrastructure as Code. Describe the required environment in declarative configuration. The system applies the changes needed to reach that state.
Modular Architecture Design
The modular architecture supports different deployments. Combine the core PostgreSQL module with optional Redis, MINIO (Silo), and Etcd modules. Pigsty also supports PG-compatible kernels and operating modes.
Security features include a self-signed CA, encrypted communication, AES-encrypted backups, and SCRAM-SHA-256 password hashes. Pigsty also supplies an ACL model and HBA rules that use least privilege.
Simple and Easy Deployment
Prepackaged dependencies support one-step installation without Internet access. Local sandboxes can run on VMs with 1 core and 2GB RAM, with the same functions as production environments. Use Vagrant for local sandboxes or Terraform for cloud deployments.
What Pigsty Is Not
Pigsty is not a complete PaaS (Platform as a Service) system.
Supply your own hardware resources. Pigsty runs on physical servers, VMs, or cloud instances that you provide. It does not create or manage them. Terraform templates help prepare cloud resources.
Pigsty runs on the operating system. It does not require Kubernetes or Docker, but can coexist with them. Its Docker module runs stateless applications.
Pigsty focuses on PostgreSQL. It also supports components such as Redis, Etcd, and Silo, but PostgreSQL remains its core.
Pigsty avoids vendor lock-in. It uses open-source components, preserves the PostgreSQL kernel, and adds no proprietary protocols. You can continue to use managed PostgreSQL clusters after removing Pigsty.
You can choose how to build and operate your database services:
- Override any default parameter or configuration template.
- Use the declarative API or manage components directly with Ansible, Patroni, pgBackRest, and other tools.
- Manage the full database lifecycle, or use monitoring alone for existing instances and RDS.
Pigsty operates at the database service layer. It combines existing tools to deliver PostgreSQL services on your hardware.
Evolution of PostgreSQL Deployment
The following comparison explains the PostgreSQL deployment approaches that Pigsty addresses.
Manual Deployment Era
Traditional deployment requires DBAs to install PostgreSQL, configure replication and monitoring, and handle failures manually. This has several costs:
- Repeated work: Each instance needs manual operations, which can introduce errors.
- Inconsistent configuration: Different DBA practices make maintenance harder.
- Longer recovery: Manual failure handling takes time and can introduce human errors.
- Limited monitoring: Separate monitoring systems make detection and diagnosis harder.
Managed Database Era
Cloud providers offer managed databases (RDS) to reduce this work. These services also have constraints:
- Cost: Service fees typically range from several times to dozens of times the hardware cost.
- Vendor lock-in: Dependence on one cloud platform complicates migration.
- Feature limits: Advanced features, extensions, and parameter changes can be restricted.
- Data control: Cloud storage reduces direct control over data.
Local RDS Era
Pigsty provides a third option: local database services with capabilities comparable to or greater than cloud RDS.
This approach combines:
- Automation: One-step deployment, automatic configuration, and automatic failure recovery provide convenience comparable to cloud RDS.
- Control: Run on your infrastructure and retain control of your data.
- Cost: Operate enterprise database services at costs close to the hardware cost.
- Features: Use PostgreSQL capabilities and ecosystem extensions without imposed restrictions.
- Portability: Open-source components allow migration without vendor lock-in.
This approach is particularly suitable for:
- Private and hybrid clouds: Enterprises needing to run databases in local environments.
- Cost-sensitive users: Organizations looking to reduce database TCO.
- High-security scenarios: Critical data requiring complete autonomy and control.
- PostgreSQL power users: Scenarios requiring advanced features and rich extensions.
- Development and testing: Quickly setting up databases locally that match production environments.
What’s Next
Continue with these topics:
- Read System Architecture for the modular design.
- Read Cluster Model for database cluster organization.
- Read High Availability for automatic failure recovery.
- Read Point-in-Time Recovery for recovery after data deletion.
- Read Service Access for stable database connections.
- Read Infrastructure as Code for declarative configuration.
- Follow Quick Start to deploy your first environment in minutes.
1 - Architecture
Pigsty uses a modular architecture and declarative interface. Combine modules to meet your requirements.
- Use one or more modules from the modular design.
- Describe the environment with a configuration inventory and parameters. Apply it with Ansible playbooks.
- Run Pigsty on physical or virtual nodes with a compatible OS.
Modules
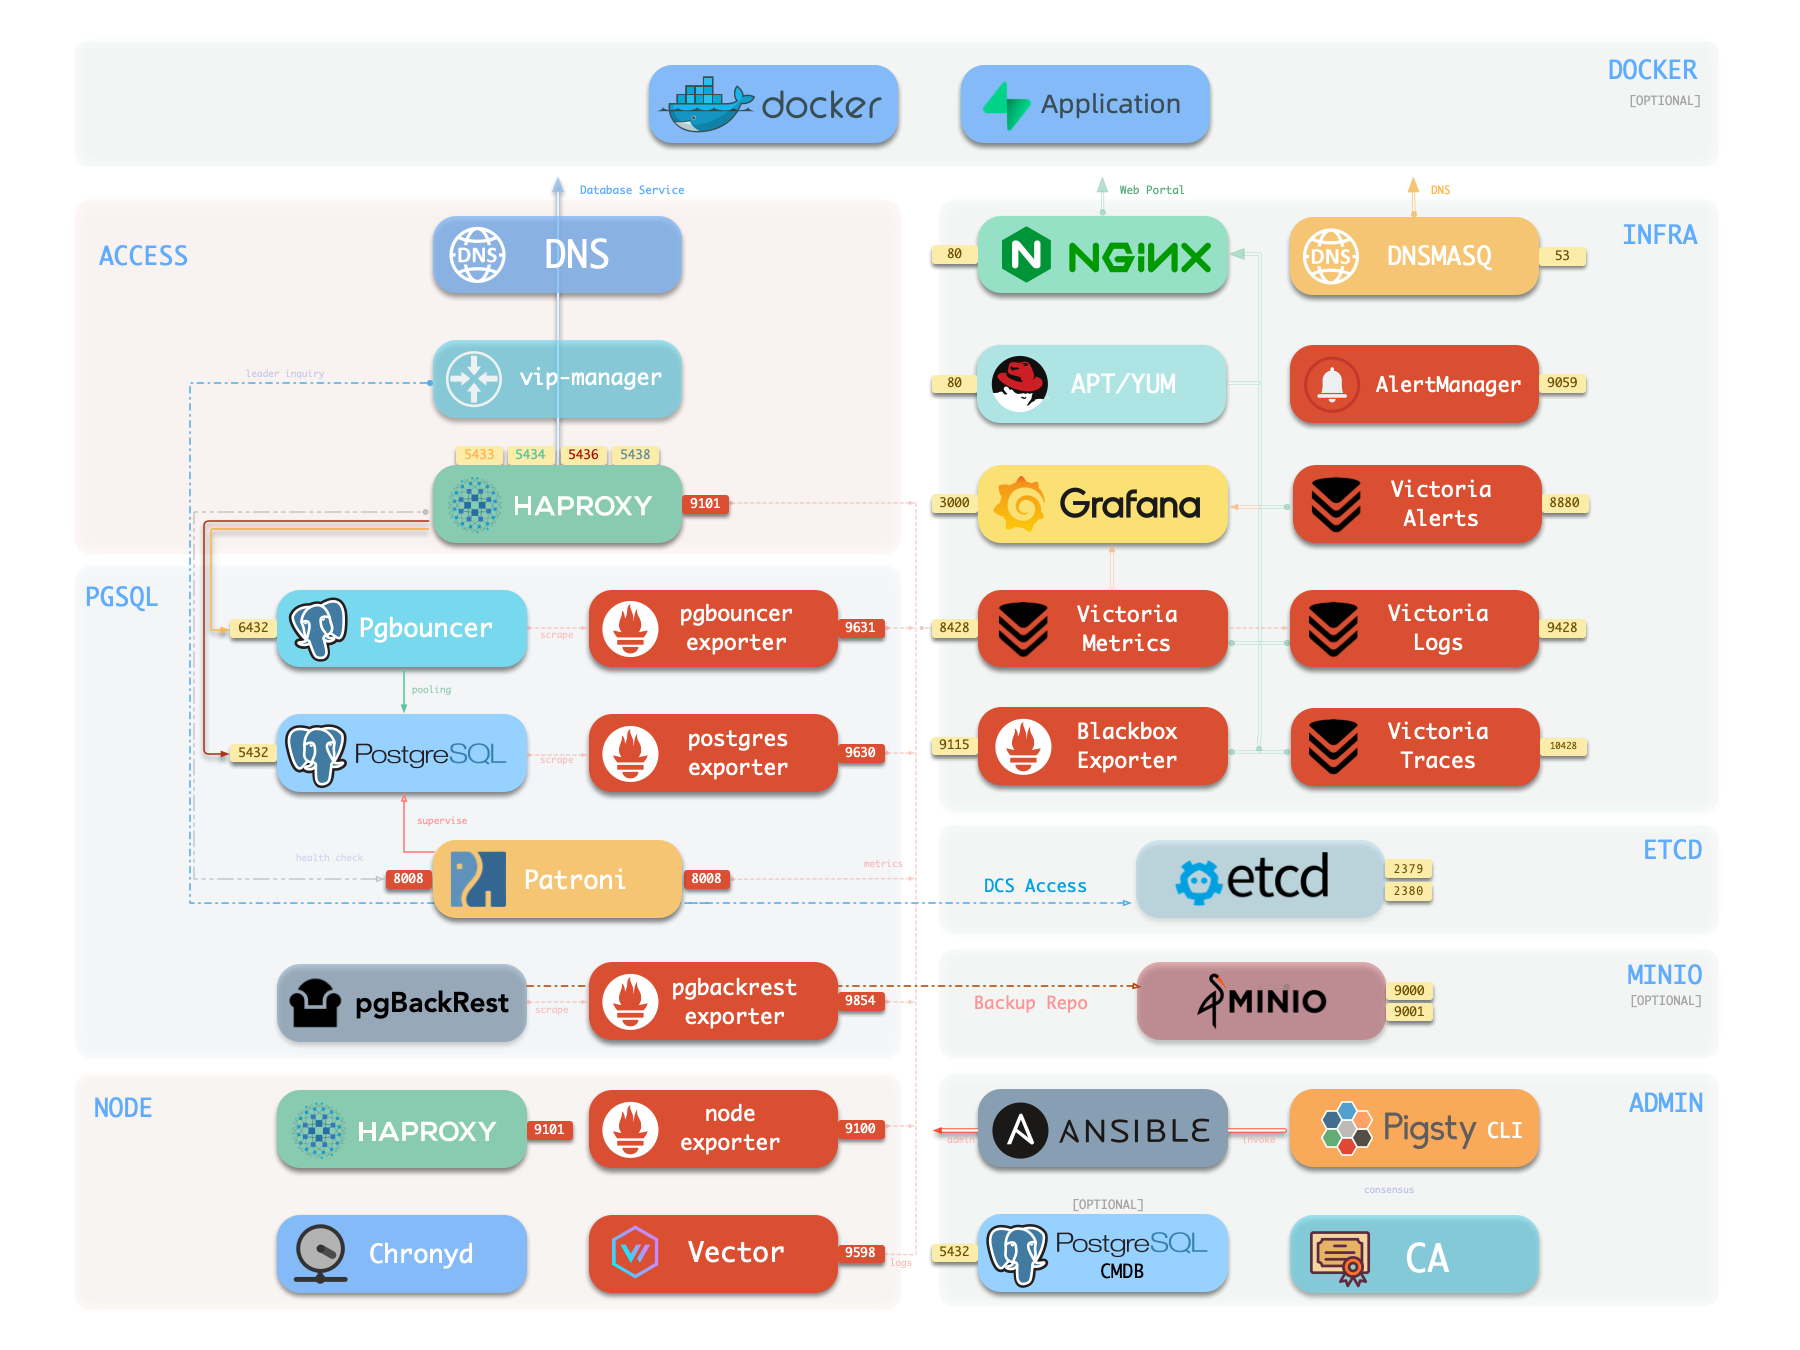
Pigsty uses a modular design with six main default modules: PGSQL, INFRA, NODE, ETCD, REDIS, and MINIO.
PGSQL: Self-healing HA Postgres clusters powered by Patroni, Pgbouncer, HAproxy, PgBackrest, and more.INFRA: Local software repo, Nginx, Grafana, Victoria, AlertManager, Blackbox Exporter—the complete observability stack.NODE: Tune nodes to desired state—hostname, timezone, NTP, ssh, sudo, haproxy, docker, vector, keepalived.ETCD: Distributed key-value store as DCS for HA Postgres clusters: consensus leader election/config management/service discovery.REDIS: Redis servers supporting standalone primary-replica, sentinel, and cluster modes with full monitoring.MINIO: S3-compatible simple object storage that can serve as an optional backup destination for PG databases.
Combine modules through declarative configuration. For host monitoring, install INFRA on infrastructure nodes and NODE on managed nodes. Install ETCD and PGSQL across multiple nodes to form an HA PostgreSQL cluster automatically. You can reuse Pigsty infrastructure for custom modules; see REDIS and MINIO as examples. Compatibility modes, such as PostgreSQL Mongo mode, combine standard PGSQL and Docker APP workflows.
Every module requires NODE. Install it first on managed nodes. By default, NODE uses the local software repository and thus has a weak dependency on INFRA. The deploy.yml playbook bootstraps administration/infrastructure nodes with INFRA to resolve this circular dependency.
Standalone Installation
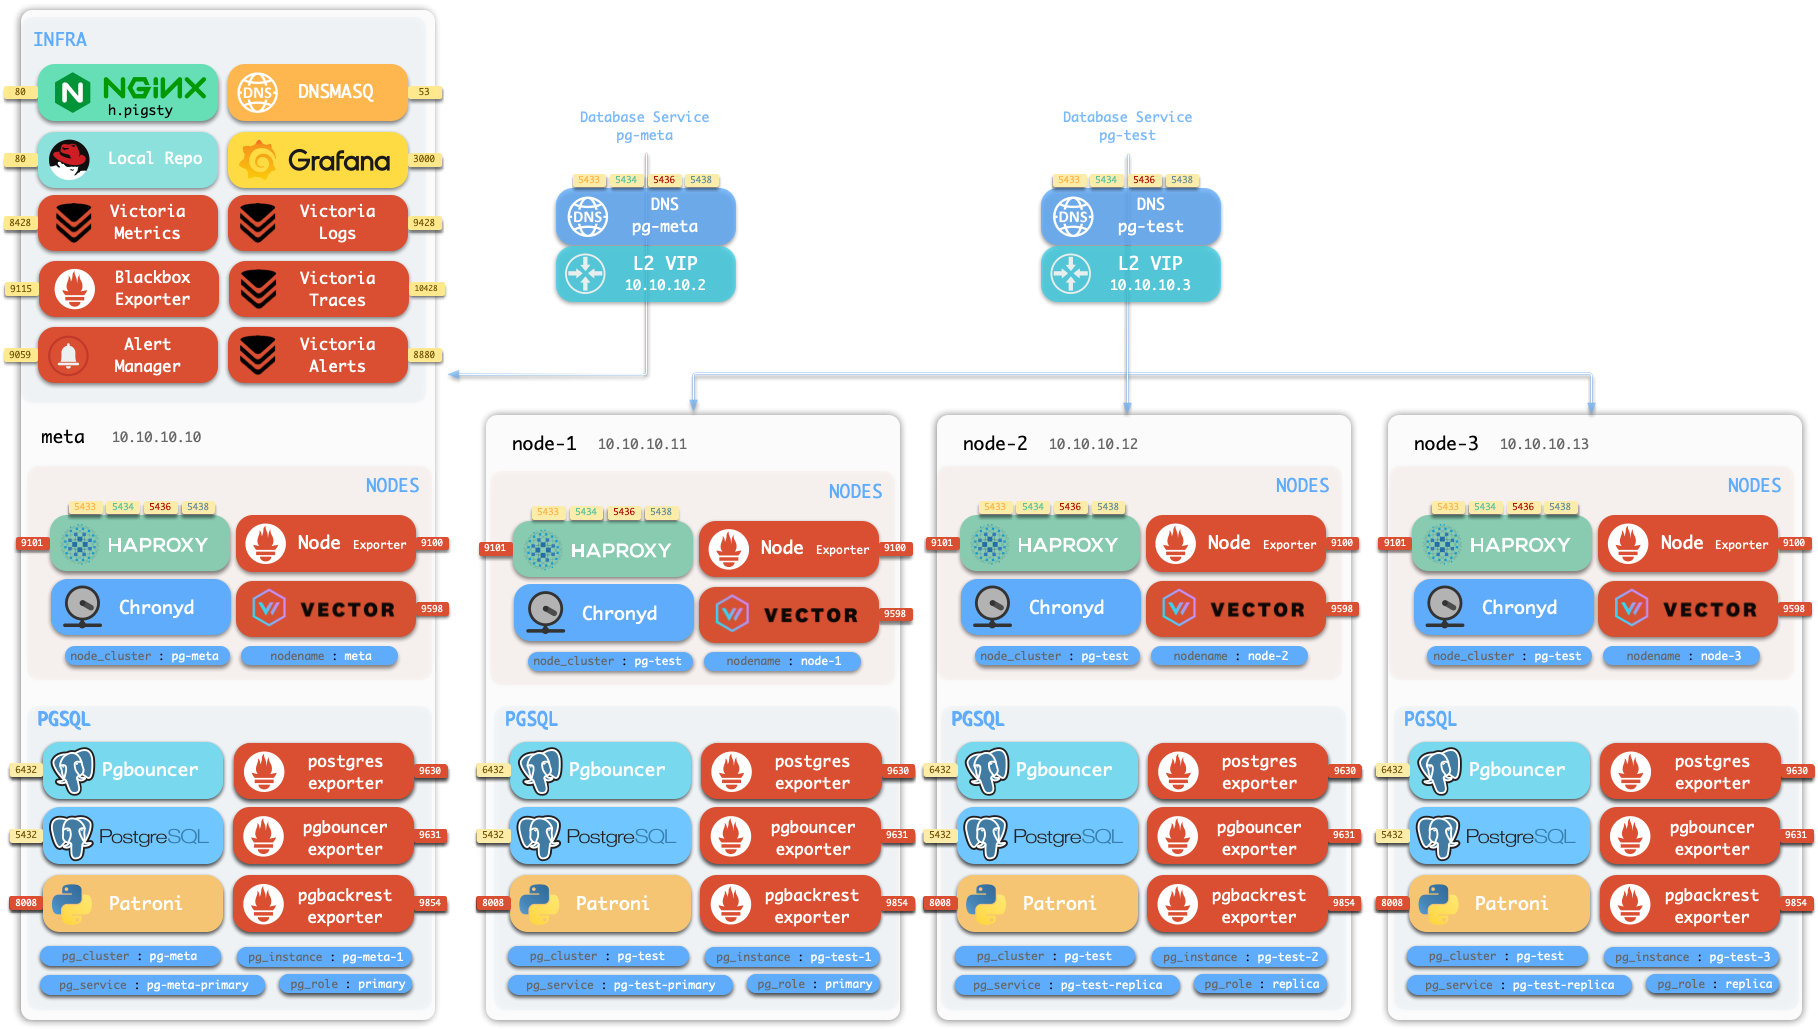
By default, Pigsty installs on one physical or virtual node. deploy.yml installs INFRA, ETCD, PGSQL, and optional MINIO on the current node. Monitoring includes VictoriaMetrics, VictoriaLogs, VictoriaTraces, Grafana, Alertmanager, and Blackbox Exporter. A standalone PostgreSQL instance serves as the CMDB: cluster pg-meta, database meta.
This node has monitoring, visualization, and PostgreSQL with automatic PITR configuration. One node cannot provide HA. Use it for development, tests, demonstrations, and data visualization or analysis. It can also serve as an administration node for additional nodes.
Monitoring
Use the standalone meta node as an administration node and monitoring center for additional nodes and database servers.
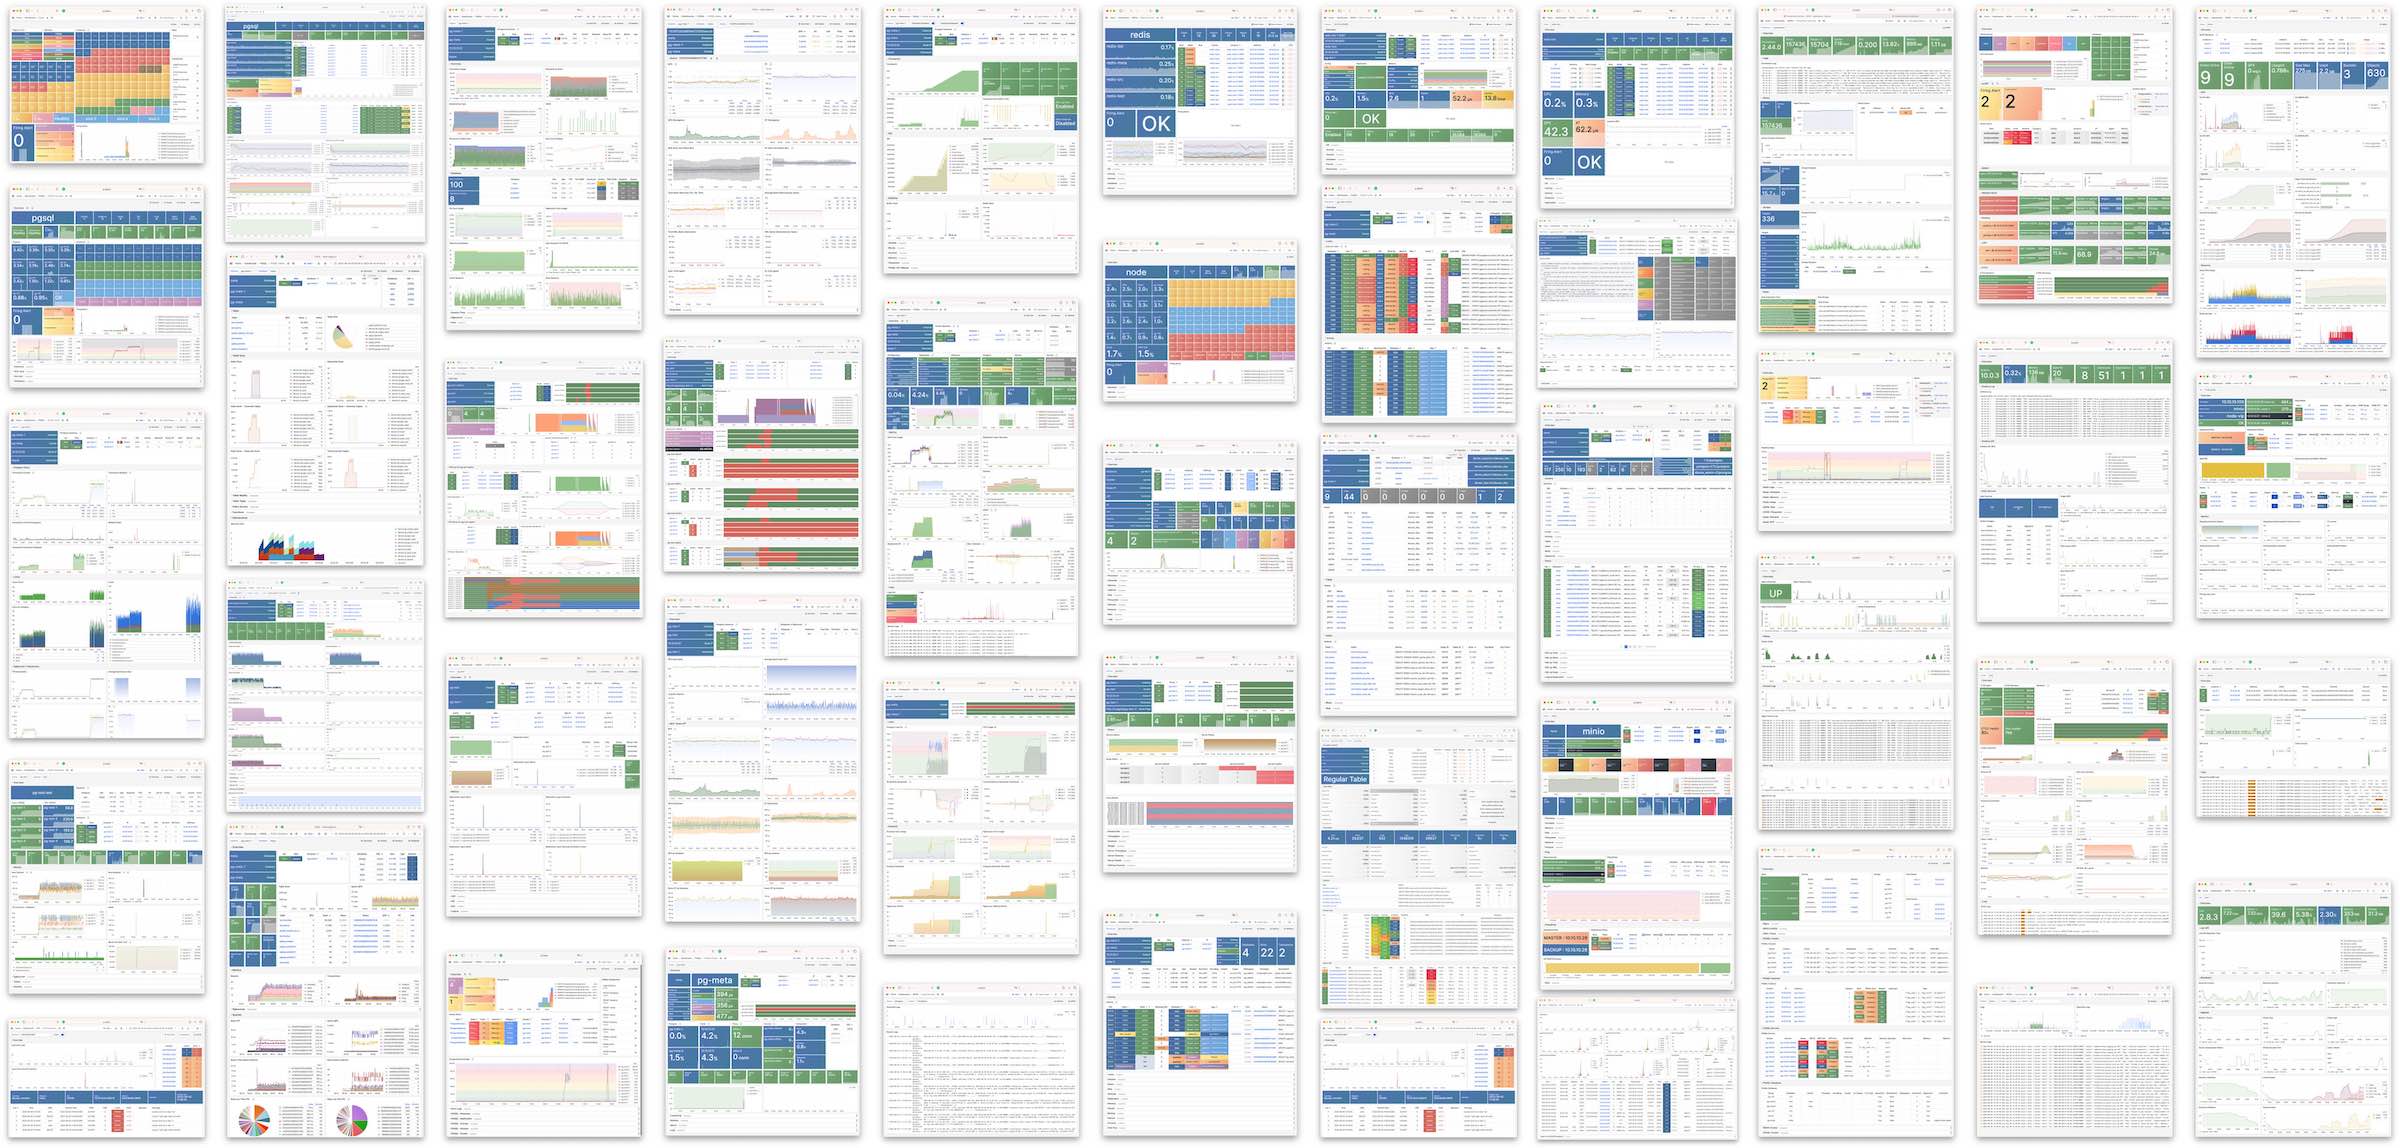
You can use Pigsty monitoring independently. It configures VictoriaMetrics/Grafana with dashboards for host nodes and PostgreSQL databases. A small configuration enables production monitoring and alerts for existing hosts and databases, including those managed outside Pigsty.
HA PostgreSQL Clusters
Pigsty lets you operate your own production HA PostgreSQL RDS service in your chosen environment.
To create an HA cluster, describe it in configuration and run the playbook:
In less than 10 minutes, the cluster has service access, monitoring, backup PITR, and HA configured.
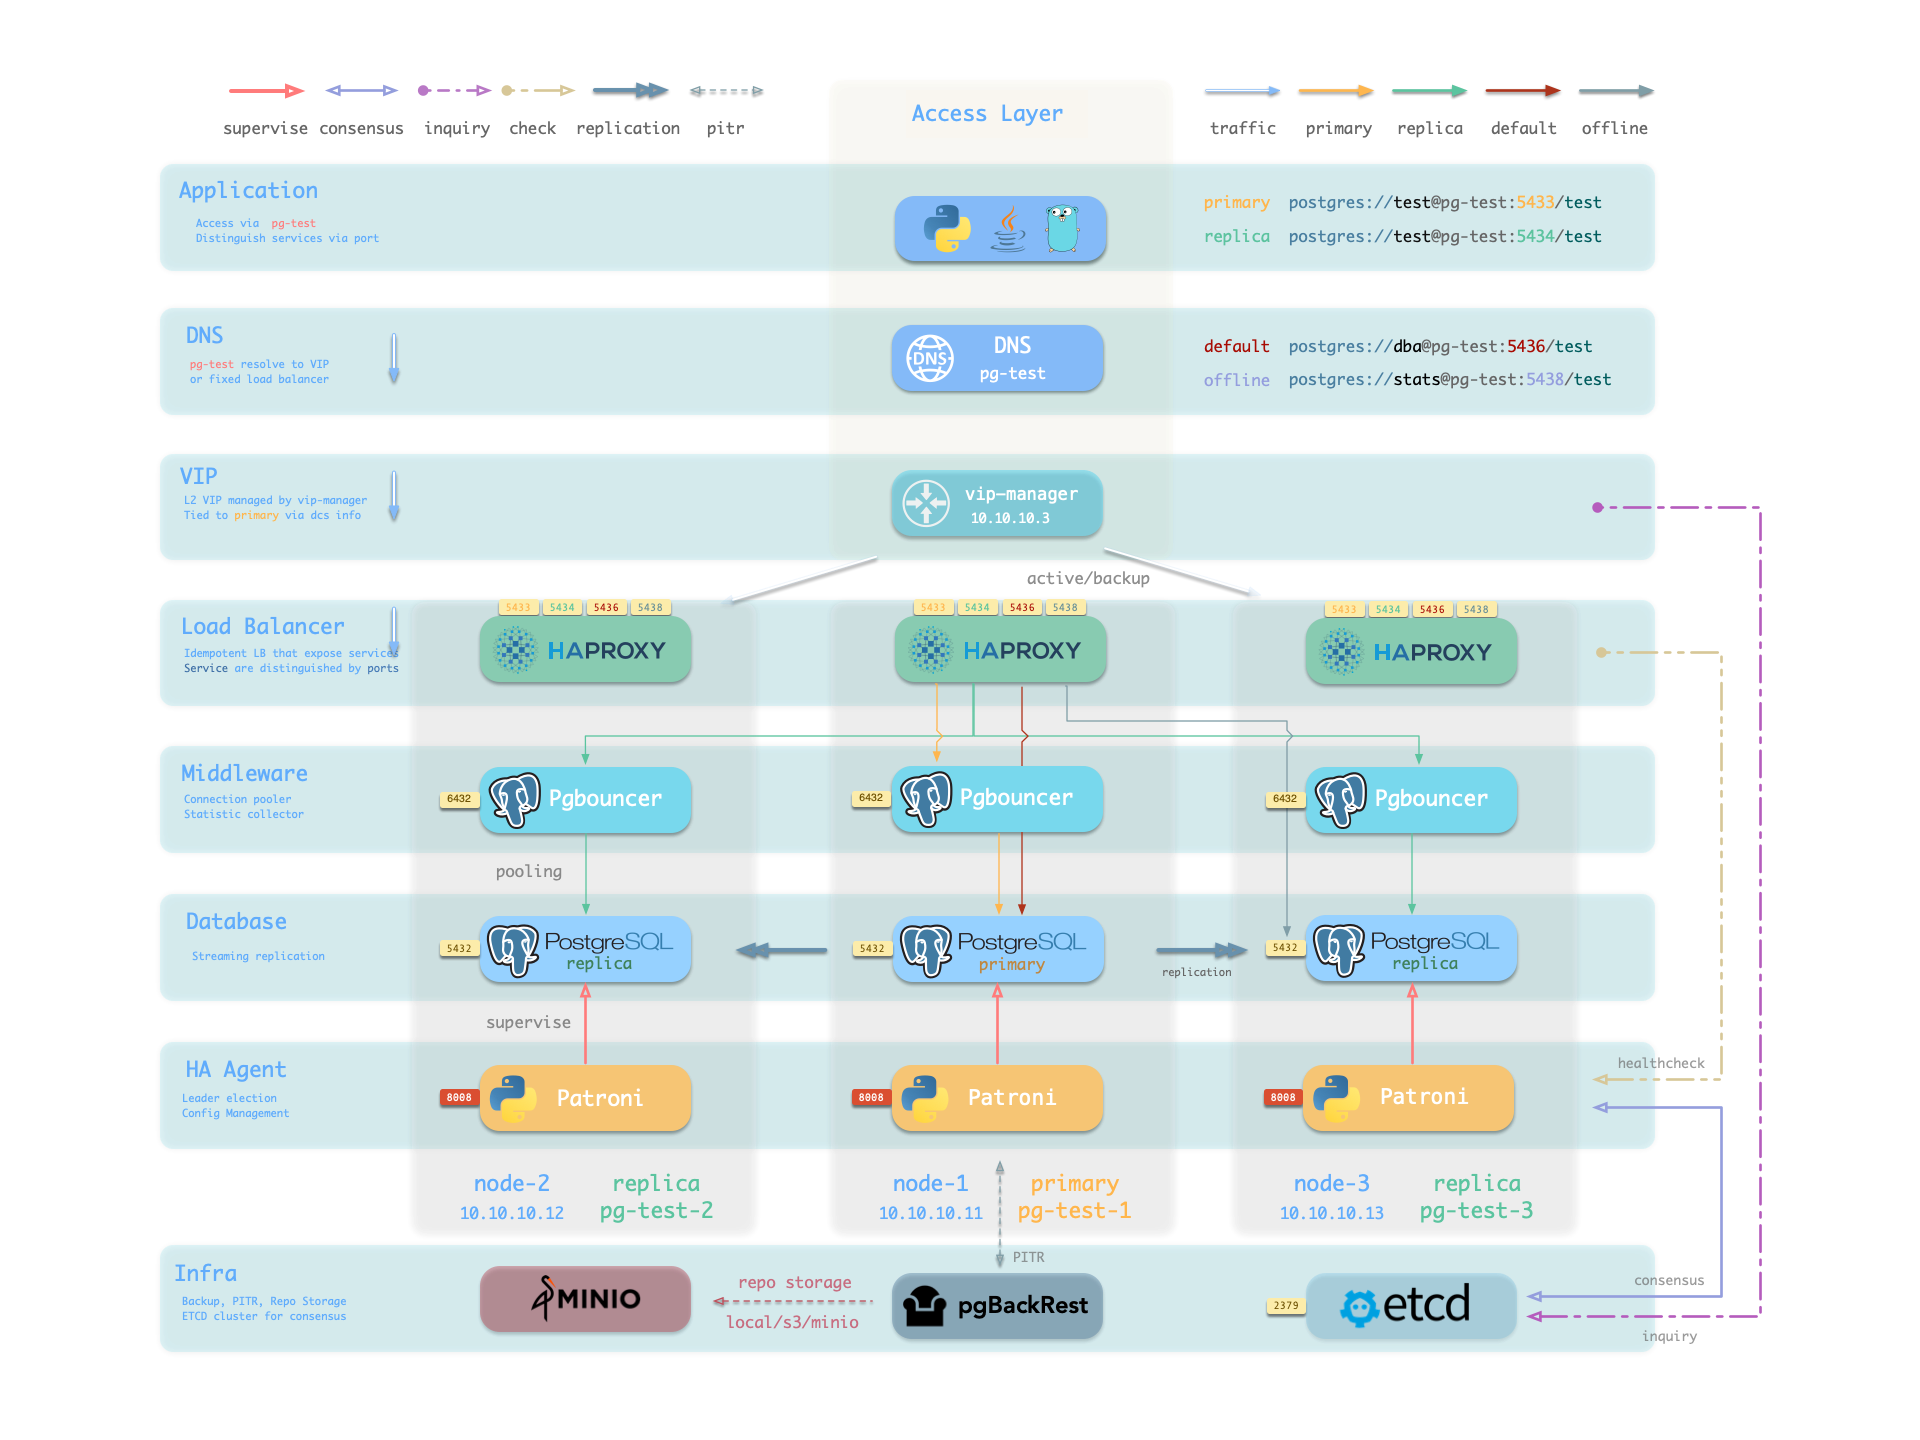
Patroni, etcd, and HAProxy provide automatic recovery from hardware failure. By default, primary failover completes within 45 seconds. HAProxy uses Patroni health checks to route read/write traffic to the new primary and avoid split brain. Clients need no configuration change or application restart. Replica failures and planned switchovers cause only a brief interruption to the current query.
pgBackRest and optional Silo provide local and cloud PITR for software failures, human errors, and datacenter disasters. They also support cross-region replication and disaster recovery after datacenter failure.
1.1 - Nodes
A node represents hardware resources and an operating system. It can be a physical server, virtual machine, container, or pod.
A node needs a Linux OS, systemd, and standard CPU, memory, disk, and network resources.
Install modules on nodes. The installed modules determine the node type:
| Type | Description |
|---|---|
| Regular Node | A node managed by Pigsty |
| ADMIN Node | The node that runs Ansible to issue management commands |
| INFRA Node | Nodes with the INFRA module installed |
| ETCD Node | Nodes with the ETCD module for DCS |
| MINIO Node | Nodes with the MINIO module for object storage |
| PGSQL Node | Nodes with the PGSQL module installed |
| … | Nodes with other modules… |
In a single-node deployment, one node has all roles: regular, administration, infrastructure, ETCD, and database.
Regular Node
Use node.yml to configure managed nodes to the target state. A regular node can run these services:
| Component | Port | Description | Status |
|---|---|---|---|
node_exporter | 9100 | Host metrics exporter | Enabled |
haproxy | 9101 | HAProxy load balancer (admin port) | Enabled |
vector | 9598 | Log collection agent | Enabled |
docker | 9323 | Container runtime support | Optional |
keepalived | n/a | L2 VIP for node cluster | Optional |
keepalived_exporter | 9650 | Keepalived status monitor | Optional |
node_exporter, vector, and haproxy are enabled by default. They export host metrics, collect logs, and balance traffic. Docker, keepalived, and keepalived_exporter are optional.
ADMIN Node
A deployment has exactly one administration node that runs Ansible playbooks and issues deployment or management commands.
This node has ssh/sudo access to every other node. Restrict access carefully. See Security Model: Trust Boundaries for its trusted access and critical assets.
During single-node installation and configuration, the current node becomes the administration node. A laptop with Ansible and SSH access to all managed nodes can also serve this role. This is not recommended for production.
For example, a laptop managing a cloud Pigsty VM is the administration node.
Production installations usually reserve 1–2 DBA machines for administration. With limited resources, INFRA nodes can also perform administration. All infrastructure nodes have Ansible by default.
INFRA Node
A Pigsty deployment may have 1 or more INFRA nodes; large production environments typically have 2-3.
The infra group in the inventory defines which nodes are INFRA nodes. These nodes run the INFRA module with these components:
| Component | Port | Description |
|---|---|---|
nginx | 80/443 | Web UI, local software repository |
grafana | 3000 | Visualization platform |
victoriaMetrics | 8428 | Time-series database (metrics) |
victoriaLogs | 9428 | Log collection server |
victoriaTraces | 10428 | Trace collection server |
vmalert | 8880 | Alerting and derived metrics |
alertmanager | 9059 | Alert aggregation and routing |
blackbox_exporter | 9115 | Blackbox probing (ping nodes/VIPs) |
dnsmasq | 53 | Internal DNS resolution |
chronyd | 123 | NTP time server |
ansible | - | Playbook execution |
Nginx provides the module Web UI and software repository. Services on multiple infrastructure nodes are independent. Each Grafana can access all monitoring data sources.
Pigsty is licensed under Apache-2.0, though embedded Grafana component uses AGPLv3.
ETCD Node
The ETCD module provides Distributed Consensus Service (DCS) for PostgreSQL high availability.
The etcd group in the inventory defines ETCD nodes. These nodes run etcd servers on two ports:
| Component | Port | Description |
|---|---|---|
etcd | 2379 | ETCD key-value store (client port) |
etcd | 2380 | ETCD cluster peer communication |
MINIO Node
The MINIO module provides optional backup storage for PostgreSQL.
The minio inventory group defines MINIO module nodes. In v4.5.0, these nodes run Silo servers on:
| Component | Port | Description |
|---|---|---|
silo | 9000 | S3 API endpoint |
silo | 9001 | Silo admin console |
PGSQL Node
A PGSQL node has the PGSQL module. Each node runs one PostgreSQL instance, giving a 1:1 mapping.
node_id_from_pg lets a PGSQL node use its PostgreSQL instance name. The default is true.
PGSQL nodes run these additional components beyond regular node services:
| Component | Port | Description | Status |
|---|---|---|---|
postgres | 5432 | PostgreSQL database server | Enabled |
pgbouncer | 6432 | PgBouncer connection pool | Enabled |
patroni | 8008 | Patroni HA management | Enabled |
pg_exporter | 9630 | PostgreSQL metrics exporter | Enabled |
pgbouncer_exporter | 9631 | PgBouncer metrics exporter | Enabled |
pgbackrest_exporter | 9854 | pgBackRest metrics exporter | Enabled |
vip-manager | n/a | Binds L2 VIP to cluster primary | Optional |
{{ pg_cluster }}-primary | 5433 | HAProxy service: pooled read/write | Enabled |
{{ pg_cluster }}-replica | 5434 | HAProxy service: pooled read-only | Enabled |
{{ pg_cluster }}-default | 5436 | HAProxy service: primary direct connection | Enabled |
{{ pg_cluster }}-offline | 5438 | HAProxy service: offline read | Enabled |
{{ pg_cluster }}-<service> | 543x | HAProxy service: custom PostgreSQL services | Custom |
vip-manager runs only when a PG VIP is configured. Define custom services through pg_services. haproxy exposes them on additional ports.
Node Relationships
Regular nodes normally select an INFRA node with admin_ip. For example, global admin_ip = 10.10.10.10 directs nodes to services at that address.
Parameters that reference ${admin_ip}:
| Parameter | Module | Default Value | Description |
|---|---|---|---|
repo_endpoint | INFRA | http://${admin_ip}:80 | Software repo URL |
repo_upstream.baseurl | INFRA | http://${admin_ip}/pigsty | Local repo baseurl |
infra_portal.endpoint | INFRA | ${admin_ip}:<port> | Nginx proxy backend |
dns_records | INFRA | ["${admin_ip} i.pigsty", ...] | DNS records |
node_default_etc_hosts | NODE | ["${admin_ip} i.pigsty"] | Default static DNS |
node_etc_hosts | NODE | - | Custom static DNS |
node_dns_servers | NODE | ["${admin_ip}"] | Dynamic DNS servers |
node_ntp_servers | NODE | - | NTP servers (optional) |
The administration node usually also provides infrastructure. With multiple infrastructure nodes, the first usually administers the environment and others provide backups.
Large deployments can separate administration from infrastructure. For example, use 1–2 small DBA-managed administration hosts and 2–3 high-capacity physical monitoring servers.
Typical node counts by deployment scale:
| Scale | ADMIN | INFRA | ETCD | MINIO | PGSQL |
|---|---|---|---|---|---|
| Single-node | 1 | 1 | 1 | 0 | 1 |
| 3-node | 1 | 3 | 3 | 0 | 3 |
| Small prod | 1 | 2 | 3 | 0 | N |
| Large prod | 2 | 3 | 5 | 4+ | N |
1.2 - Infrastructure
Production HA PostgreSQL needs monitoring, alerts, logs, time synchronization, DNS, and software repositories. The INFRA module provides these services. It is optional but strongly recommended.
Overview
The following single-node deployment diagram shows INFRA components on the right:
| Component | Type | Description |
|---|---|---|
| Nginx | Web Server | Unified entry for WebUI, local repo, reverse proxy for internal services |
| Repo | Software Repo | APT/DNF repository with all RPM/DEB packages needed for deployment |
| Grafana | Visualization | Displays metrics, logs, and traces; hosts dashboards, reports, and custom data apps |
| VictoriaMetrics | Time Series DB | Scrapes all metrics, Prometheus API compatible, provides VMUI query interface |
| VictoriaLogs | Log Platform | Centralized log storage; all nodes run Vector by default, pushing logs here |
| VictoriaTraces | Tracing | Collects slow SQL, service traces, and other tracing data |
| VMAlert | Eval Rule/Alert | Evaluates alerting rules, pushes events to Alertmanager |
| AlertManager | Alert Manager | Aggregates alerts, dispatches notifications via email, Webhook, etc. |
| BlackboxExporter | Blackbox Probe | Probes reachability of IPs/VIPs/URLs |
| DNSMASQ | DNS Service | Provides DNS resolution for domains used within Pigsty [Optional] |
| Chronyd | Time Sync | Provides NTP time synchronization to ensure consistent time across nodes [Optional] |
| CA | Certificate | Issues encryption certificates within the environment |
| Ansible | Orchestration | Batch, declarative, agentless tool for managing large numbers of servers |
Nginx
Nginx provides access to Pigsty WebUI services. HTTP and HTTPS use 80 and 443 by default. See the Live Demo.
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10 | http://i.pigsty | https://i.pigsty | https://demo.pigsty.io |
Nginx exposes the Grafana, VictoriaMetrics (VMUI), AlertManager, and HAProxy web interfaces. It also serves the local software repository and other static files.
Nginx configures local web servers or reverse proxy servers based on definitions in infra_portal.
The default administration homepage is i.pigsty. Its endpoints proxy these components:
| Endpoint | Component | Native Port | Notes | Public Demo |
|---|---|---|---|---|
/ | Nginx | 80/443 | Homepage, local repo, file server | demo.pigsty.io |
/ui/ | Grafana | 3000 | Grafana dashboard entry | demo.pigsty.io/ui/ |
/vmetrics/ | VictoriaMetrics | 8428 | Time series DB Web UI | demo.pigsty.io/vmetrics/ |
/vlogs/ | VictoriaLogs | 9428 | Log DB Web UI | demo.pigsty.io/vlogs/ |
/vtraces/ | VictoriaTraces | 10428 | Tracing Web UI | demo.pigsty.io/vtraces/ |
/vmalert/ | VMAlert | 8880 | Alert rule management | demo.pigsty.io/vmalert/ |
/alertmgr/ | AlertManager | 9059 | Alert management Web UI | demo.pigsty.io/alertmgr/ |
/blackbox/ | Blackbox | 9115 | Blackbox probe |
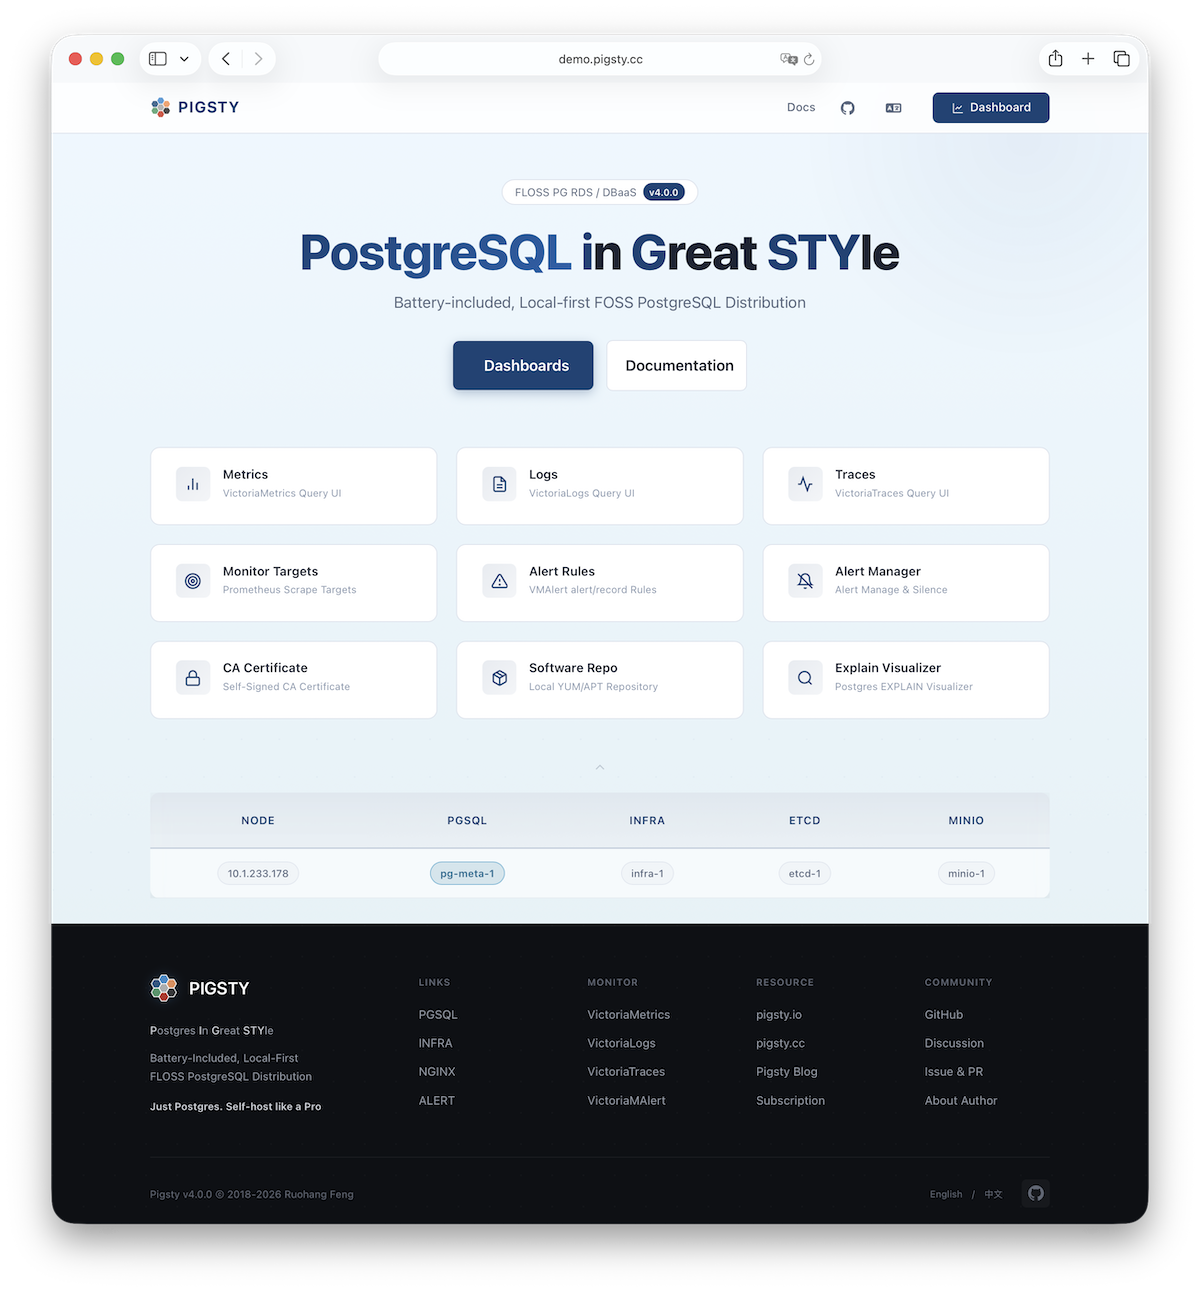
Configure Nginx as a file server or reverse proxy. HTTPS supports self-signed and publicly trusted certificates.
For more information, see: Tutorial: Nginx—Expose Web Services via Proxy and Tutorial: Certbot—Request and Renew HTTPS Certificates
Repo
During installation, Pigsty creates a local software repository on the infrastructure node to speed later installations. See the Live Demo.
The default directory is /www/pigsty. Nginx serves it at /pigsty:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/pigsty | http://i.pigsty/pigsty | https://i.pigsty/pigsty | https://demo.pigsty.io/pigsty |
For offline installation, copy a prepared local software repository into the target environment. If /www/pigsty/repo_complete exists, deployment skips upstream downloads and uses that repository. sow generates this file as a completion marker and SHA-256 manifest. To force a rebuild, run ./infra.yml -t repo_build -e repo_build=true.
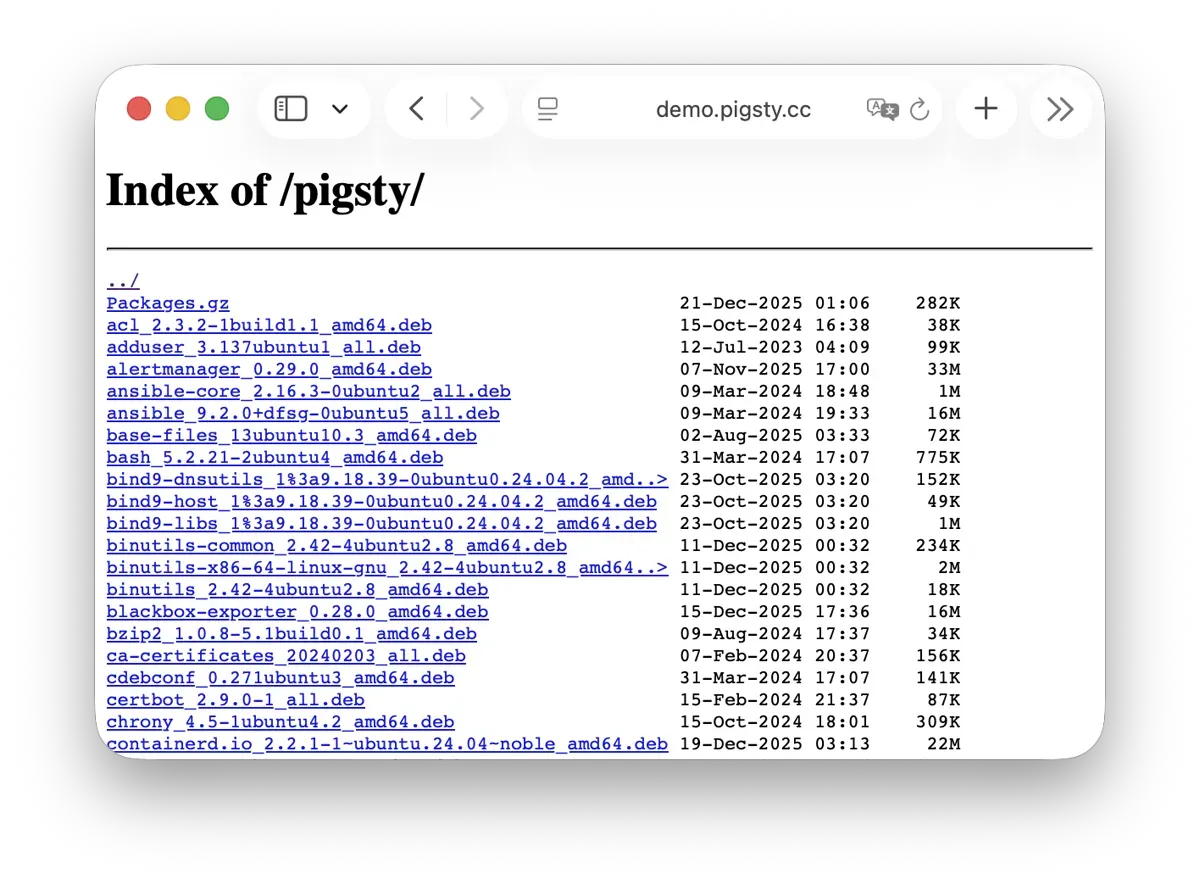
For more information, see: Config: INFRA - REPO
Grafana
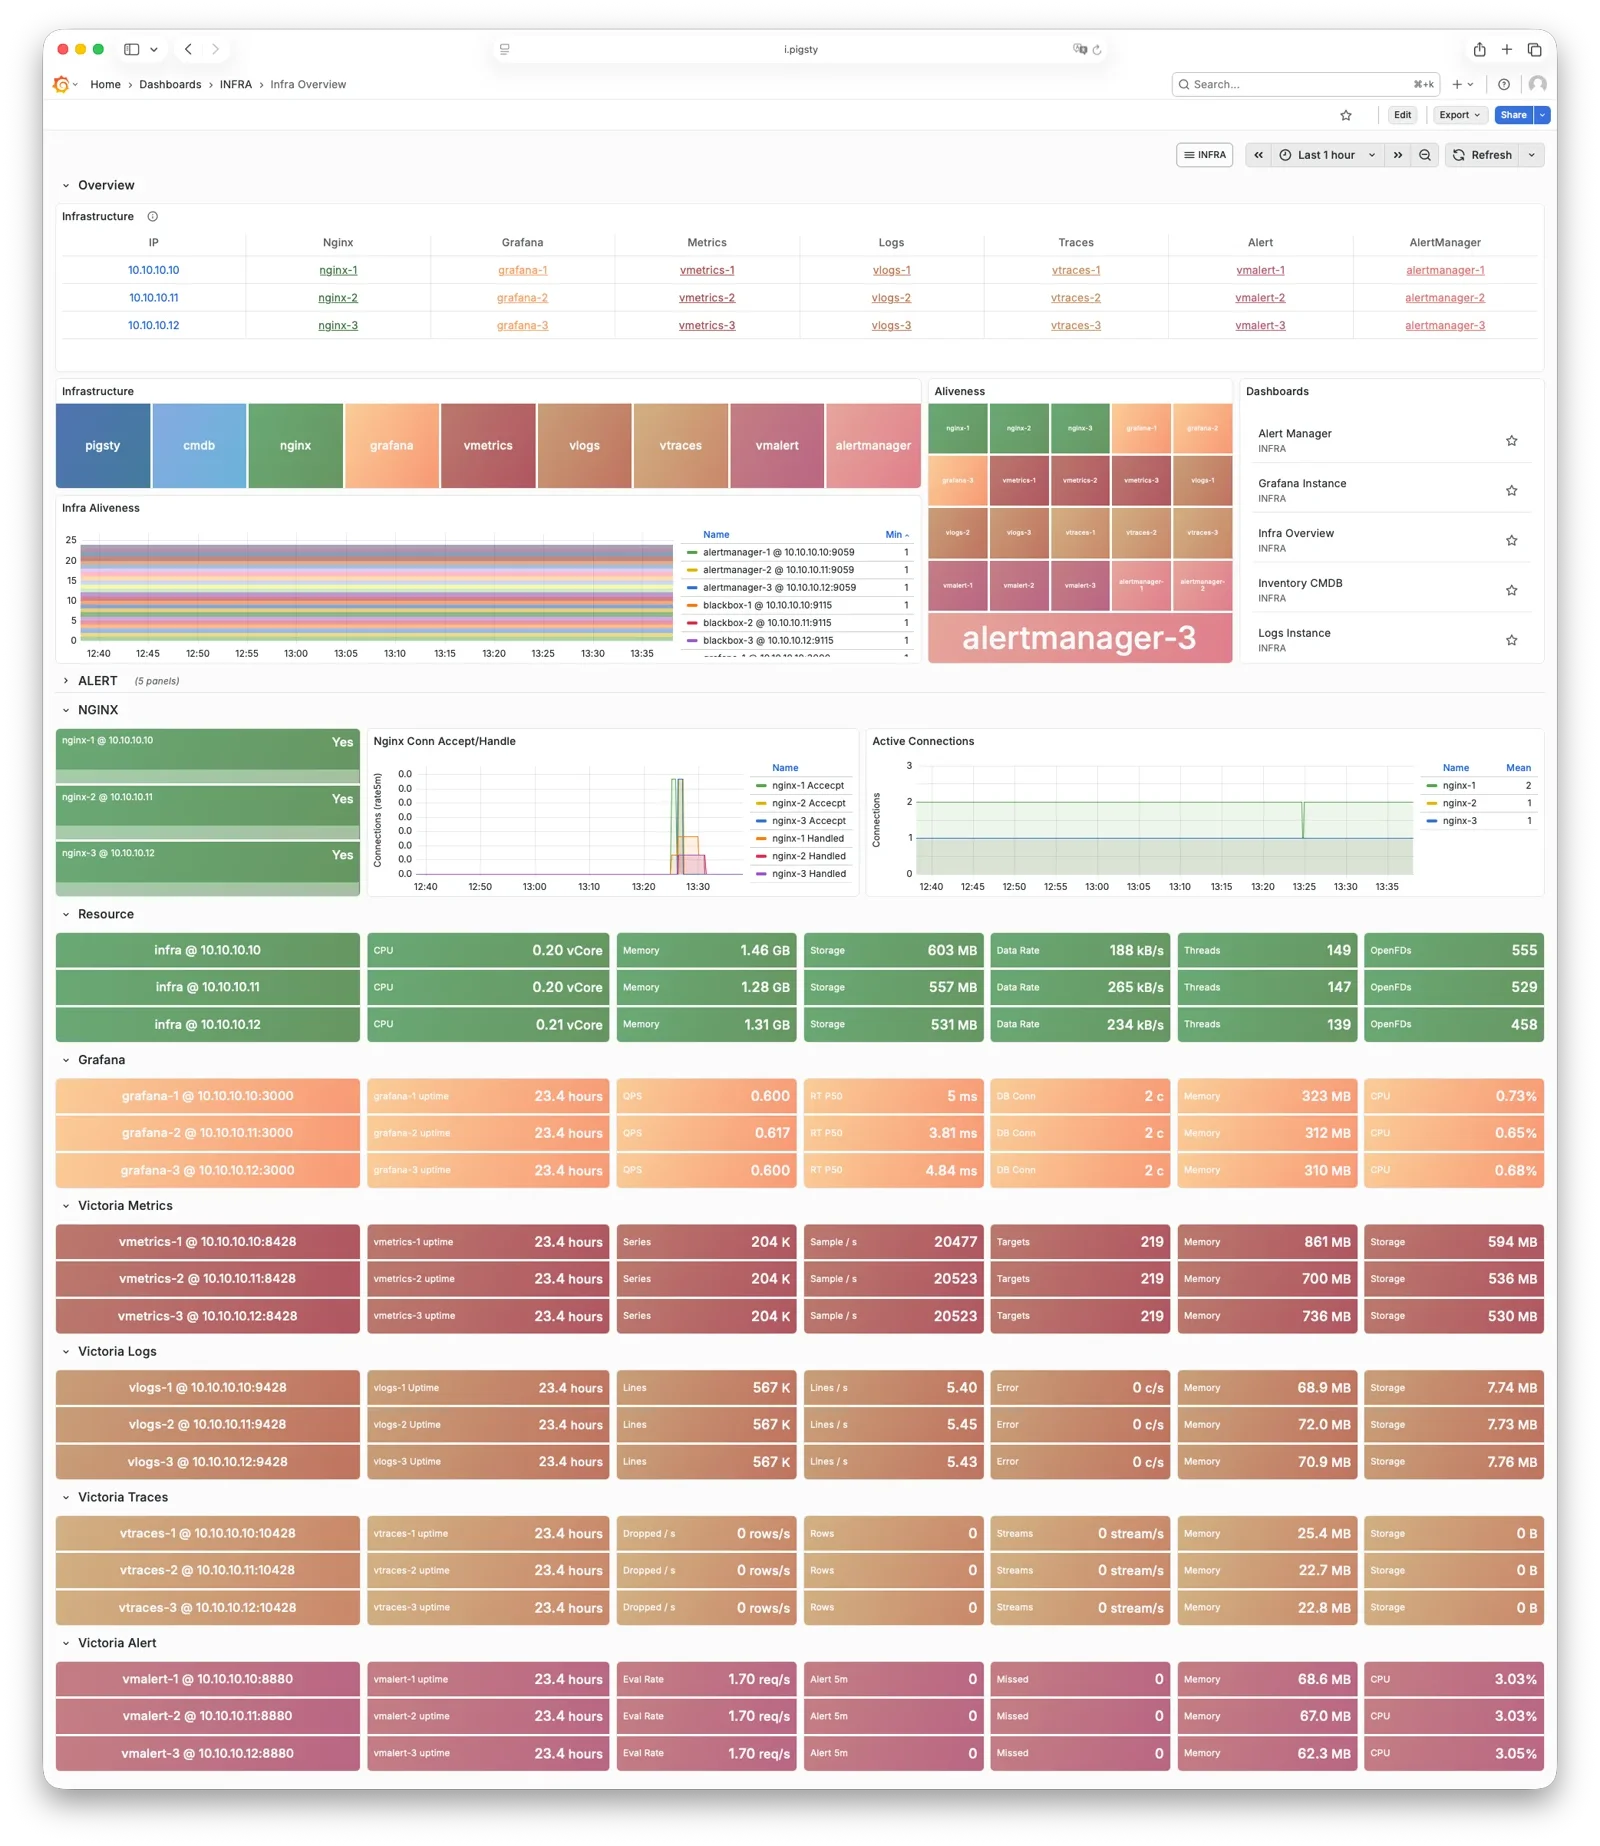
Grafana visualizes Pigsty metrics, logs, and other monitoring data. See the Live Demo.
Grafana listens on port 3000 by default and is proxied via Nginx at the /ui path:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/ui | http://i.pigsty/ui | https://i.pigsty/ui | https://demo.pigsty.io/ui |
Pigsty includes dashboards for VictoriaMetrics, Logs, and Traces. URL links let you move between summary and detail views for diagnosis.
Grafana also supports low-code visualization. Pigsty installs ECharts, victoriametrics-datasource, and victorialogs-datasource plugins by default. Vector/Victoria data sources use the names vmetrics-*, vlogs-*, and vtraces-* for custom dashboards.
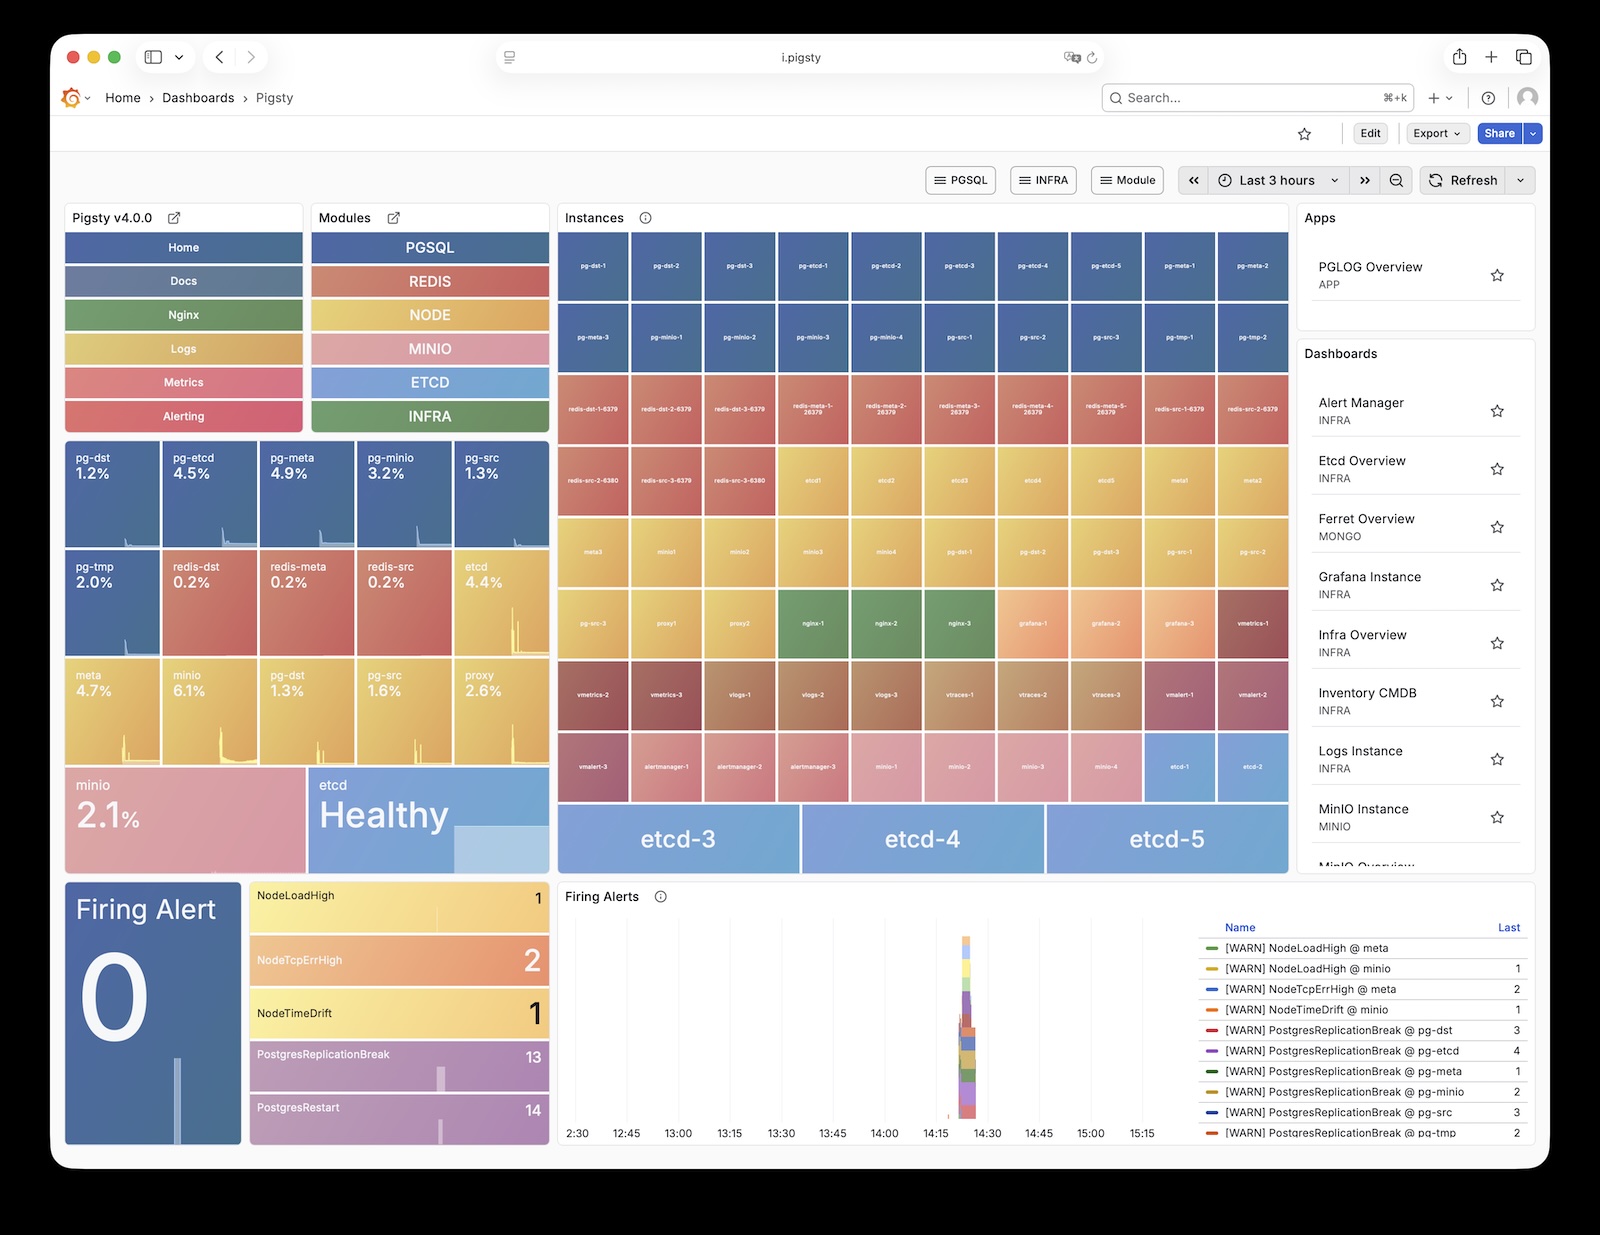
For more information, see: Config: INFRA - GRAFANA.
VictoriaMetrics
VictoriaMetrics collects and stores Pigsty monitoring metrics as time-series data. See the Live Demo.
The default port is 8428. Access it through Nginx at /vmetrics or the p.pigsty domain:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/vmetrics | http://p.pigsty | https://i.pigsty/vmetrics | https://demo.pigsty.io/vmetrics |
VictoriaMetrics supports the Prometheus API, PromQL, remote read/write protocols, and the Alertmanager API. Its VMUI supports direct queries for metric exploration. It also supplies data to Grafana.
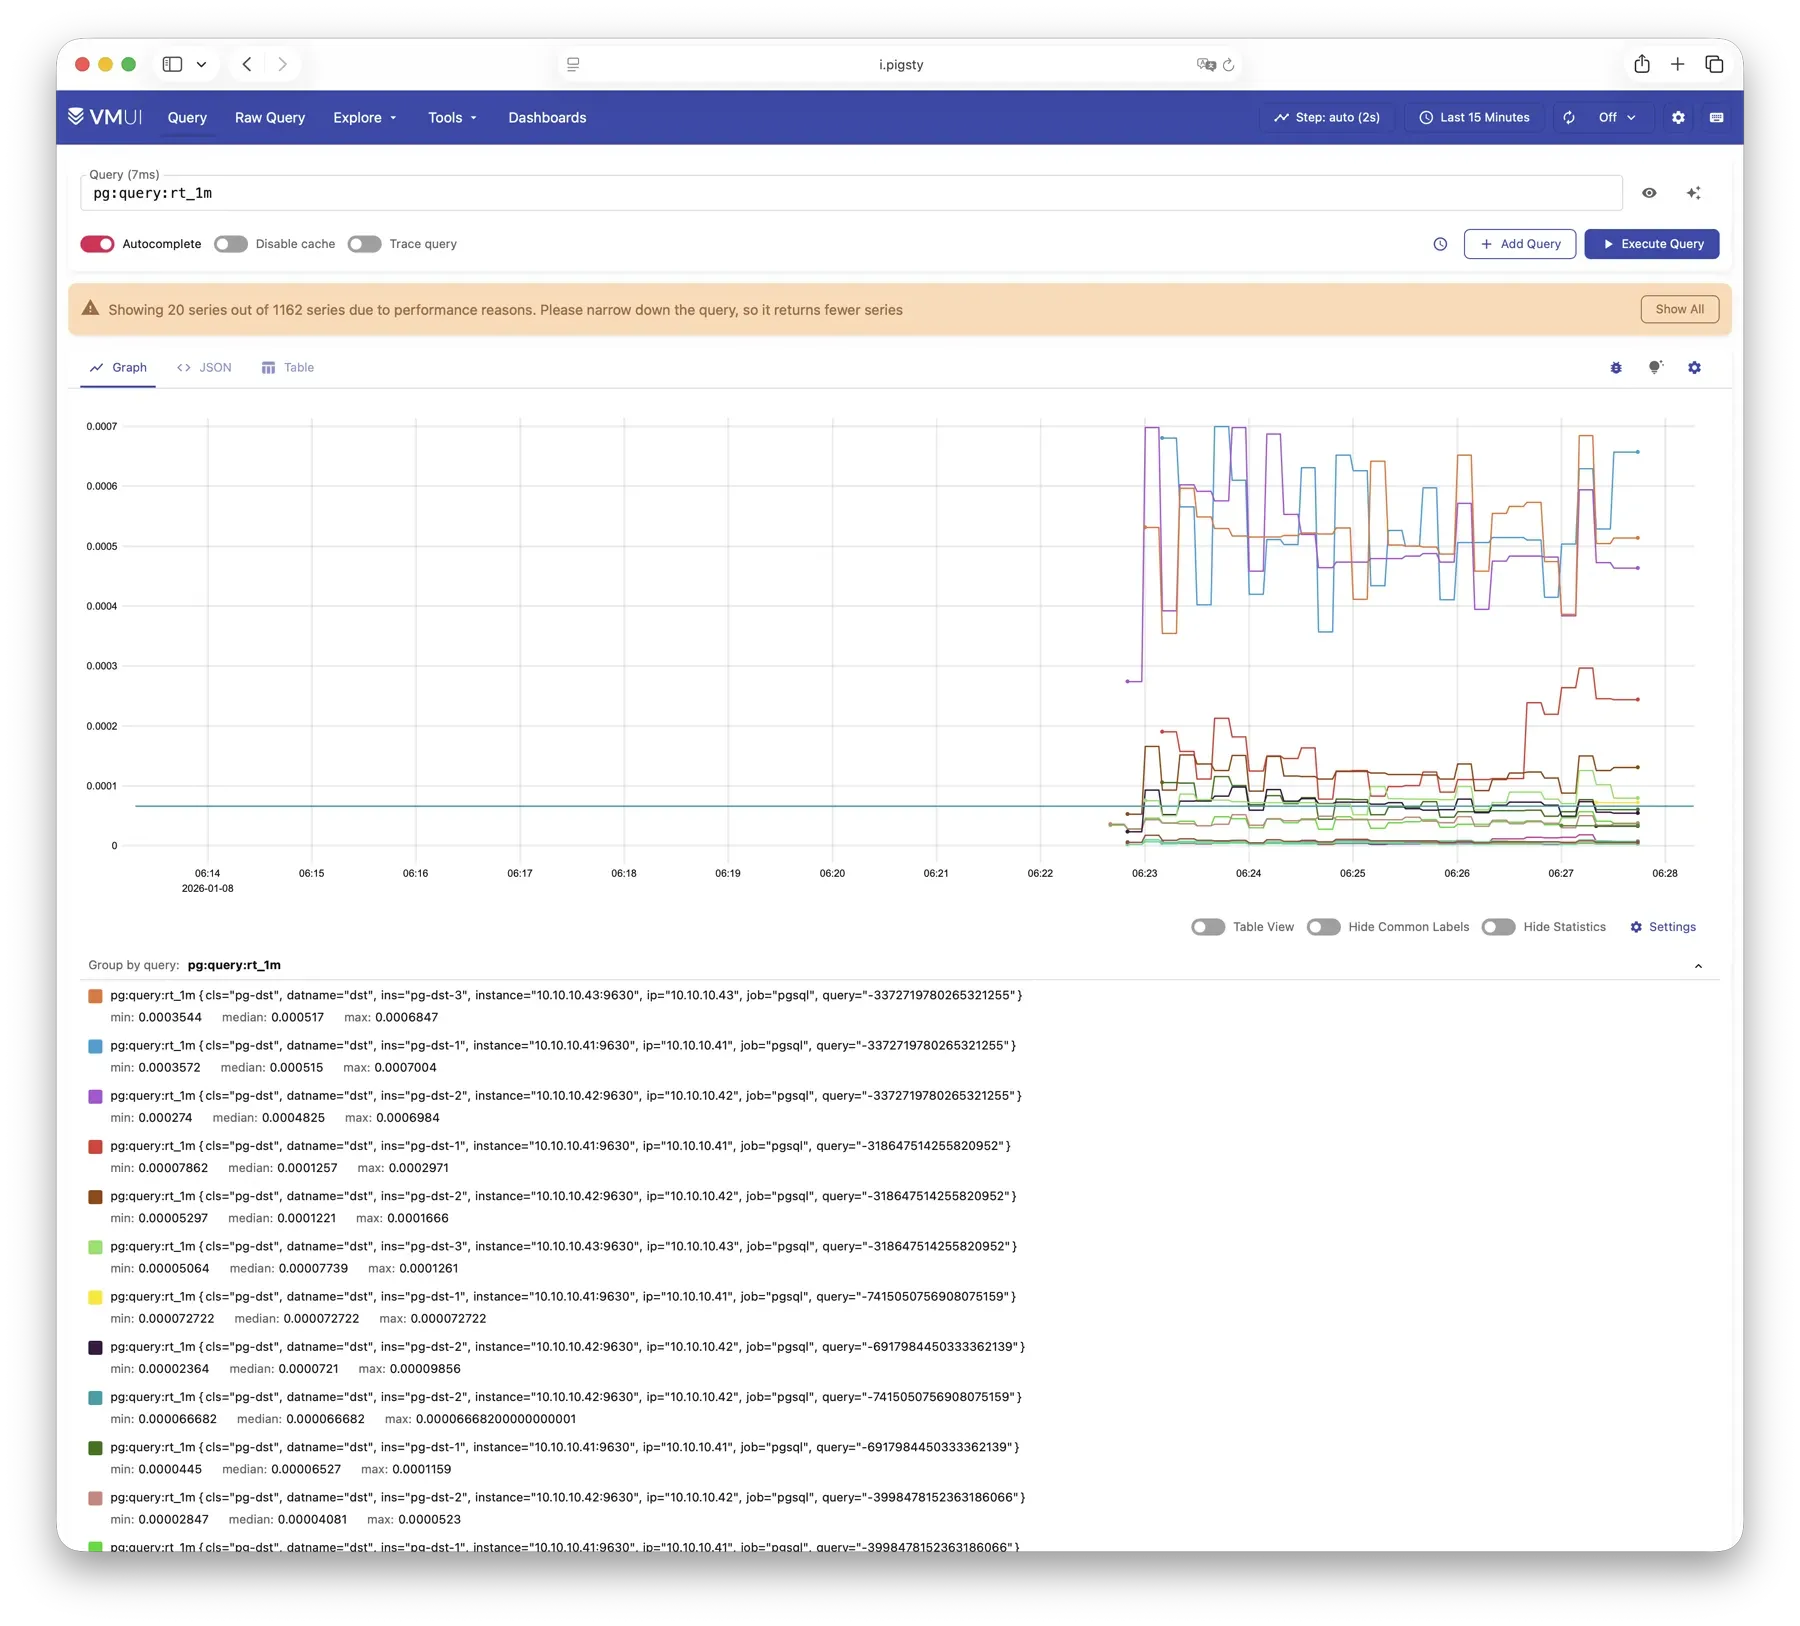
For more information, see: Config: INFRA - VMETRICS
VictoriaLogs
VictoriaLogs centrally stores structured logs from all Pigsty nodes. See the Live Demo.
It listens on port 9428 by default, mounted at Nginx /vlogs path:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/vlogs | http://i.pigsty/vlogs | https://i.pigsty/vlogs | https://demo.pigsty.io/vlogs |
Managed nodes run Vector by default. It collects system, PostgreSQL, Patroni, Pgbouncer, and other logs, structures them, and sends them to VictoriaLogs. The built-in Web UI supports search and filtering. Use the Grafana victorialogs-datasource plugin for visual analysis.
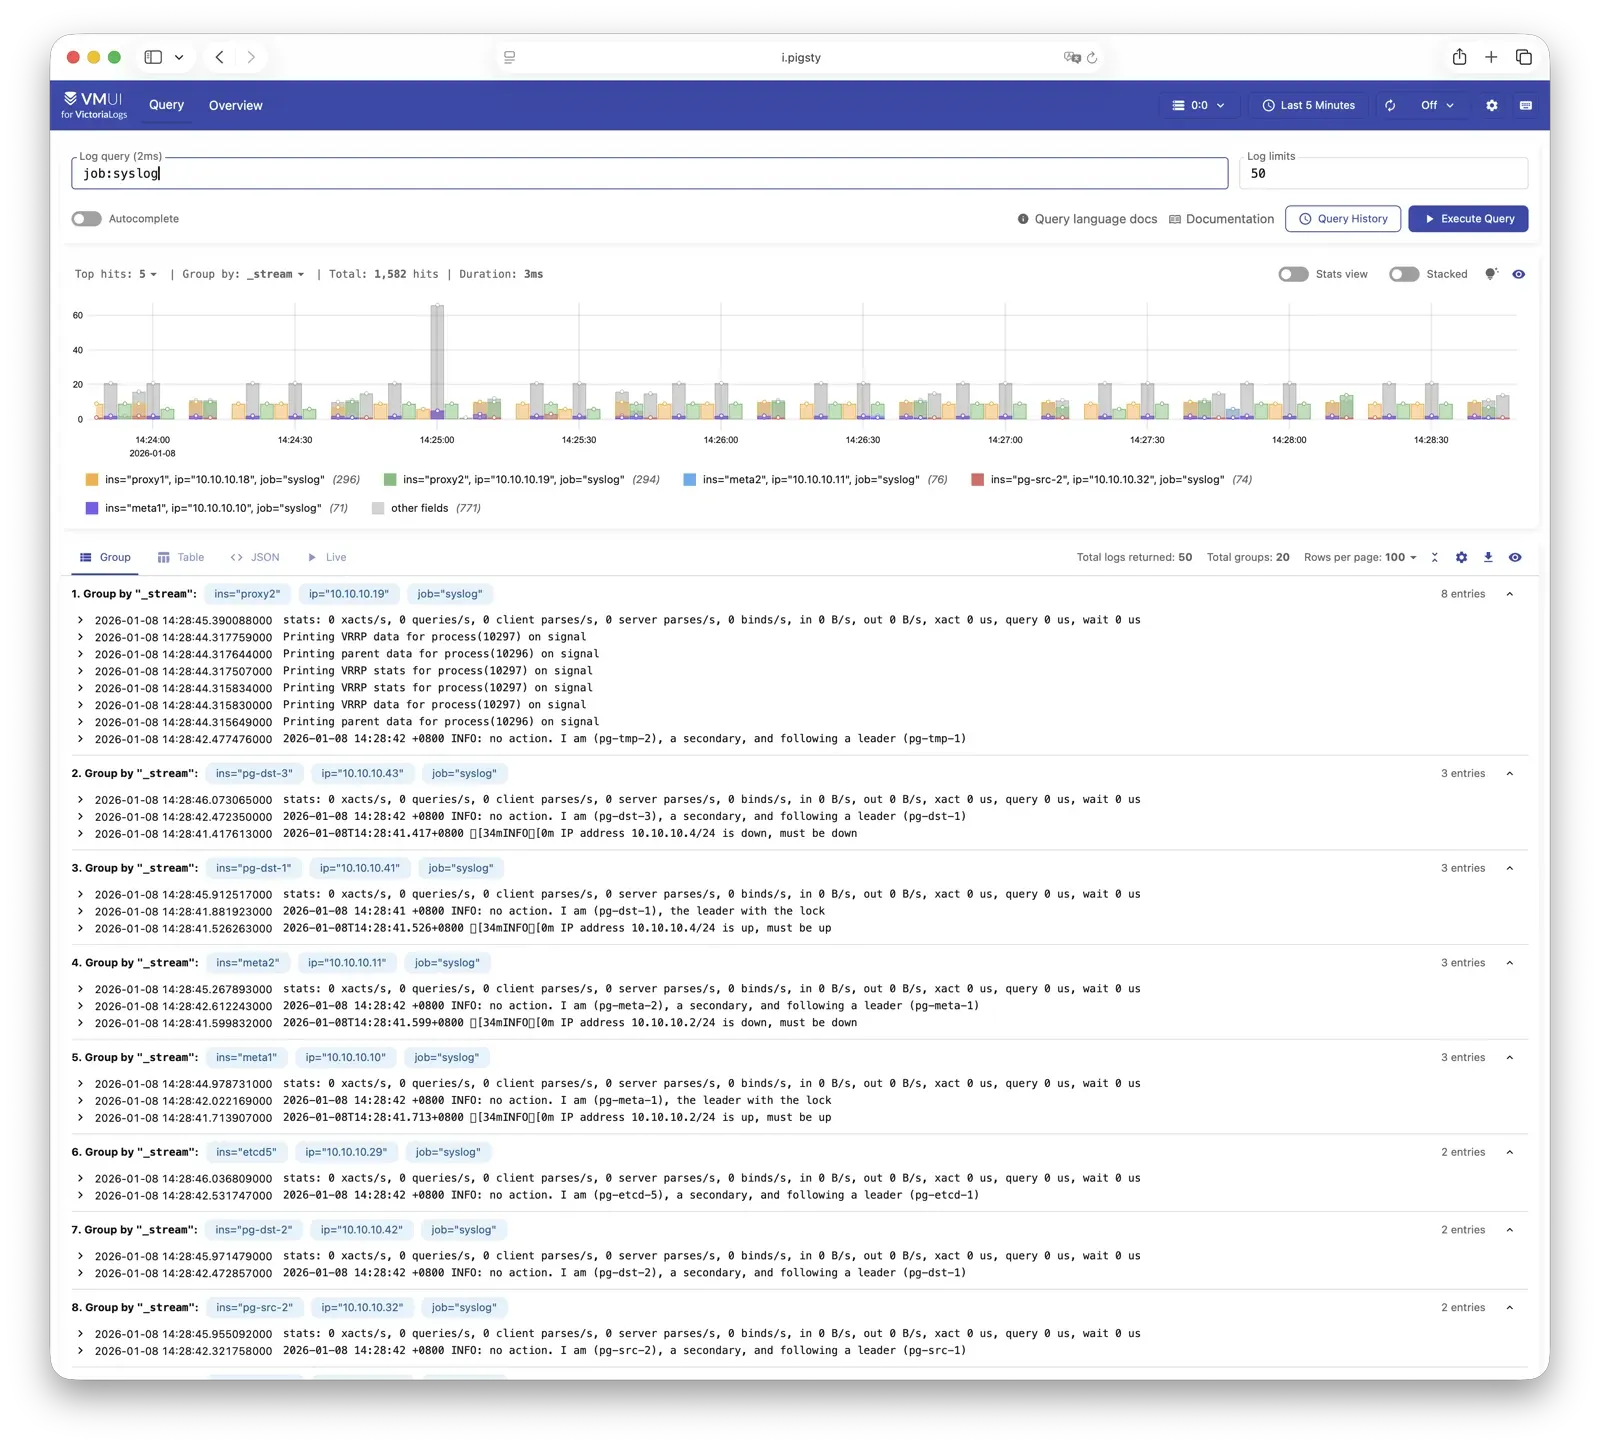
For more information, see: Config: INFRA - VLOGS
VictoriaTraces
VictoriaTraces is used for collecting trace data and slow SQL records. Live Demo
It listens on port 10428 by default, mounted at Nginx /vtraces path:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/vtraces | http://i.pigsty/vtraces | https://i.pigsty/vtraces | https://demo.pigsty.io/vtraces |
VictoriaTraces provides a Jaeger-compatible interface for service traces and slow SQL queries. Use it with Grafana to locate performance limits and trace their causes.
For more information, see: Config: INFRA - VTRACES
VMAlert
VMAlert evaluates alert rules and sends triggered events to Alertmanager. See the Live Demo.
It listens on port 8880 by default, mounted at Nginx /vmalert path:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/vmalert | http://i.pigsty/vmalert | https://i.pigsty/vmalert | https://demo.pigsty.io/vmalert |
VMAlert periodically evaluates rules against VictoriaMetrics data. Pigsty includes rules for common failures in PGSQL, NODE, REDIS, and other modules.
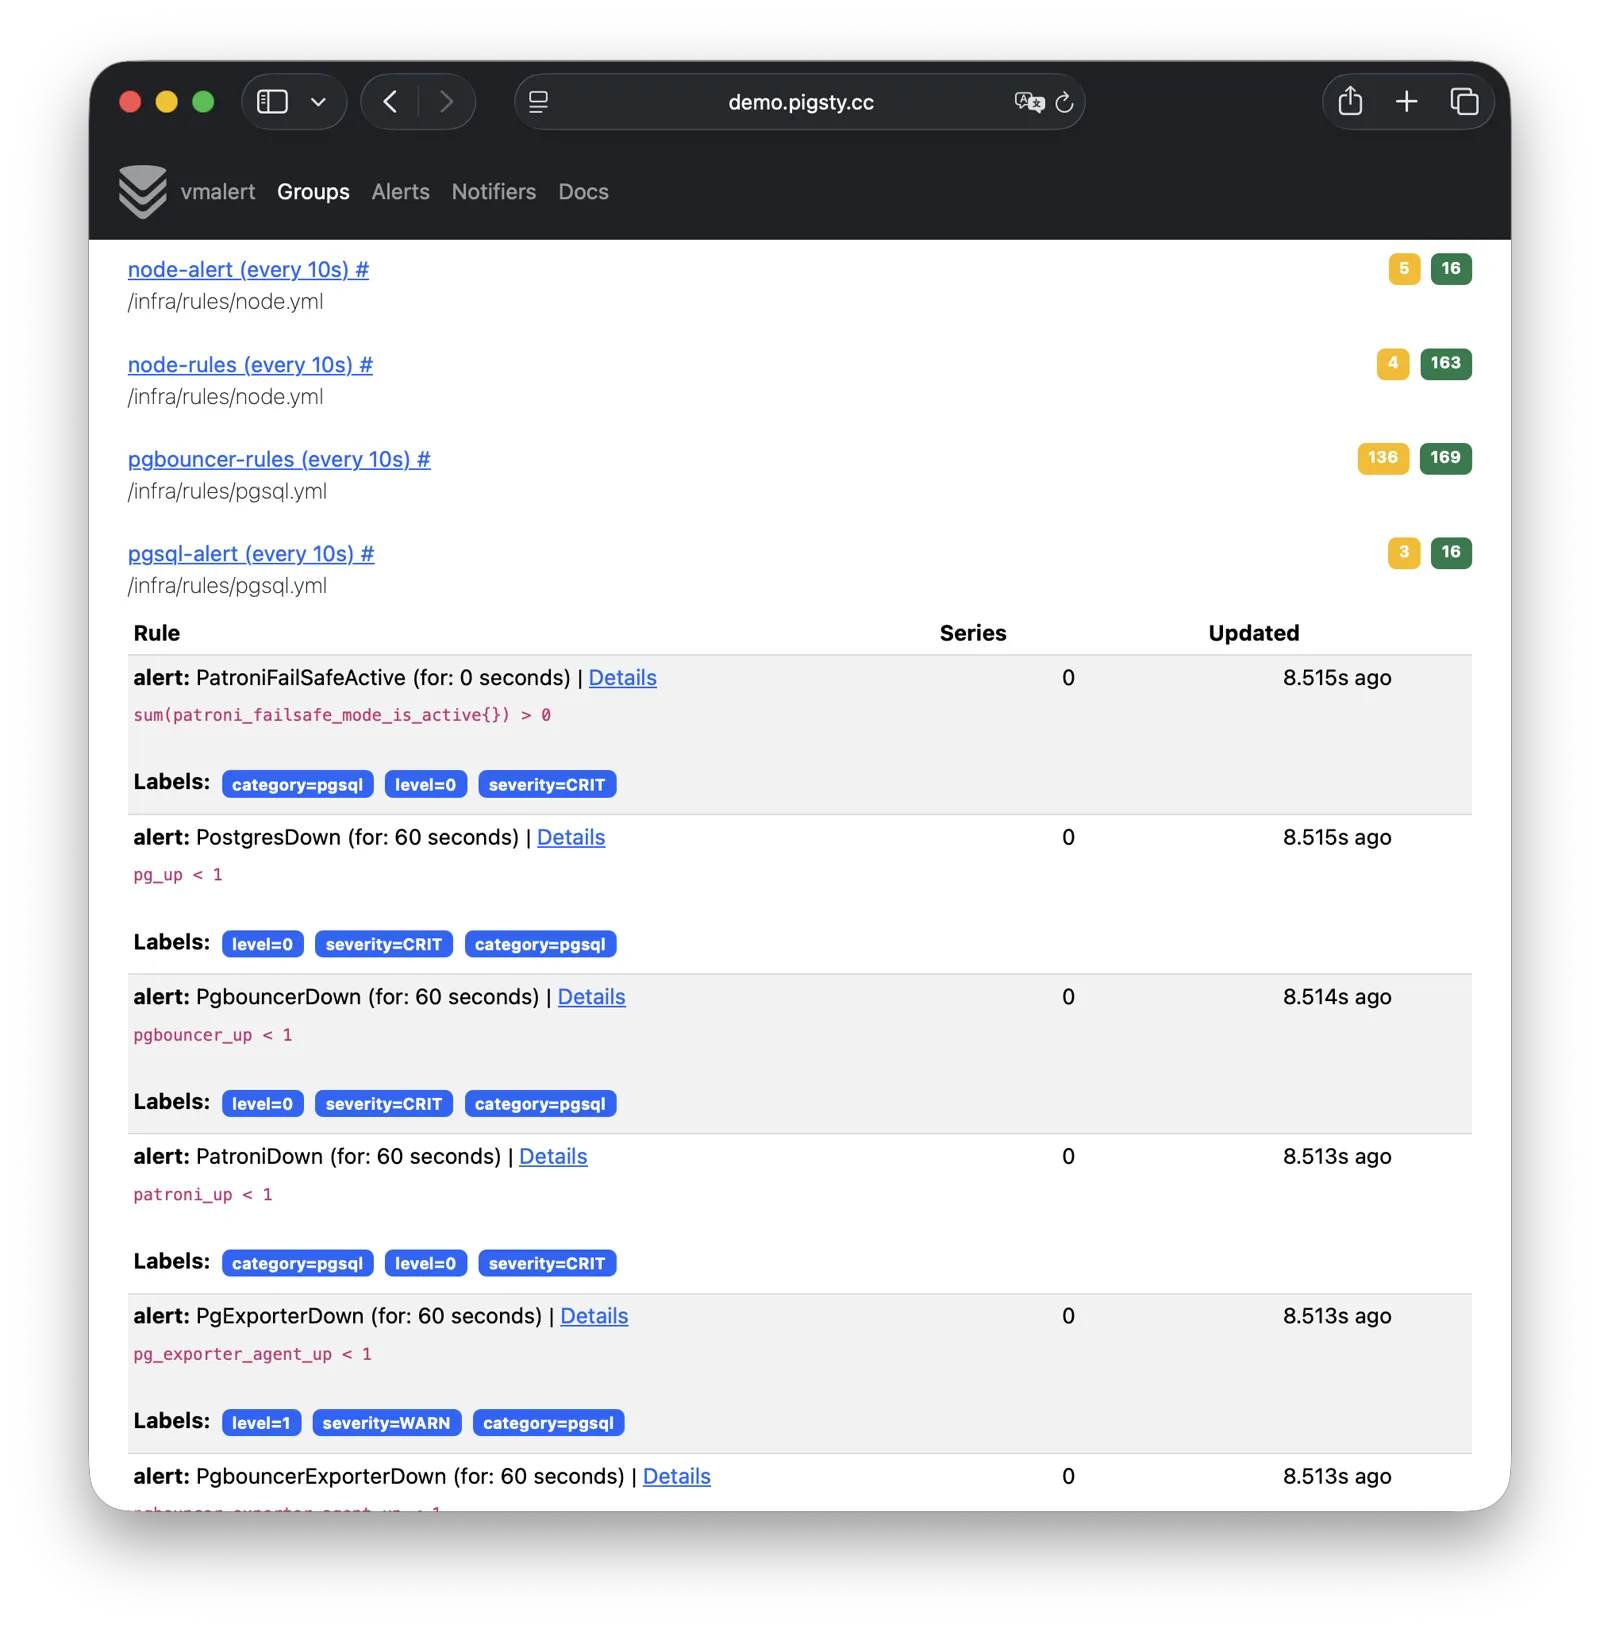
For more information, see: Config: INFRA - VMALERT
AlertManager
AlertManager handles alert event aggregation, deduplication, grouping, and dispatch. Live Demo
It listens on port 9059 by default, mounted at Nginx /alertmgr path, and also accessible via the a.pigsty domain:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/alertmgr | http://a.pigsty | https://i.pigsty/alertmgr | https://demo.pigsty.io/alertmgr |
AlertManager supports email, Webhook, Slack, PagerDuty, WeChat Work, and other notification channels. Routing rules select destinations by severity and module. Silencing and inhibition are also supported.
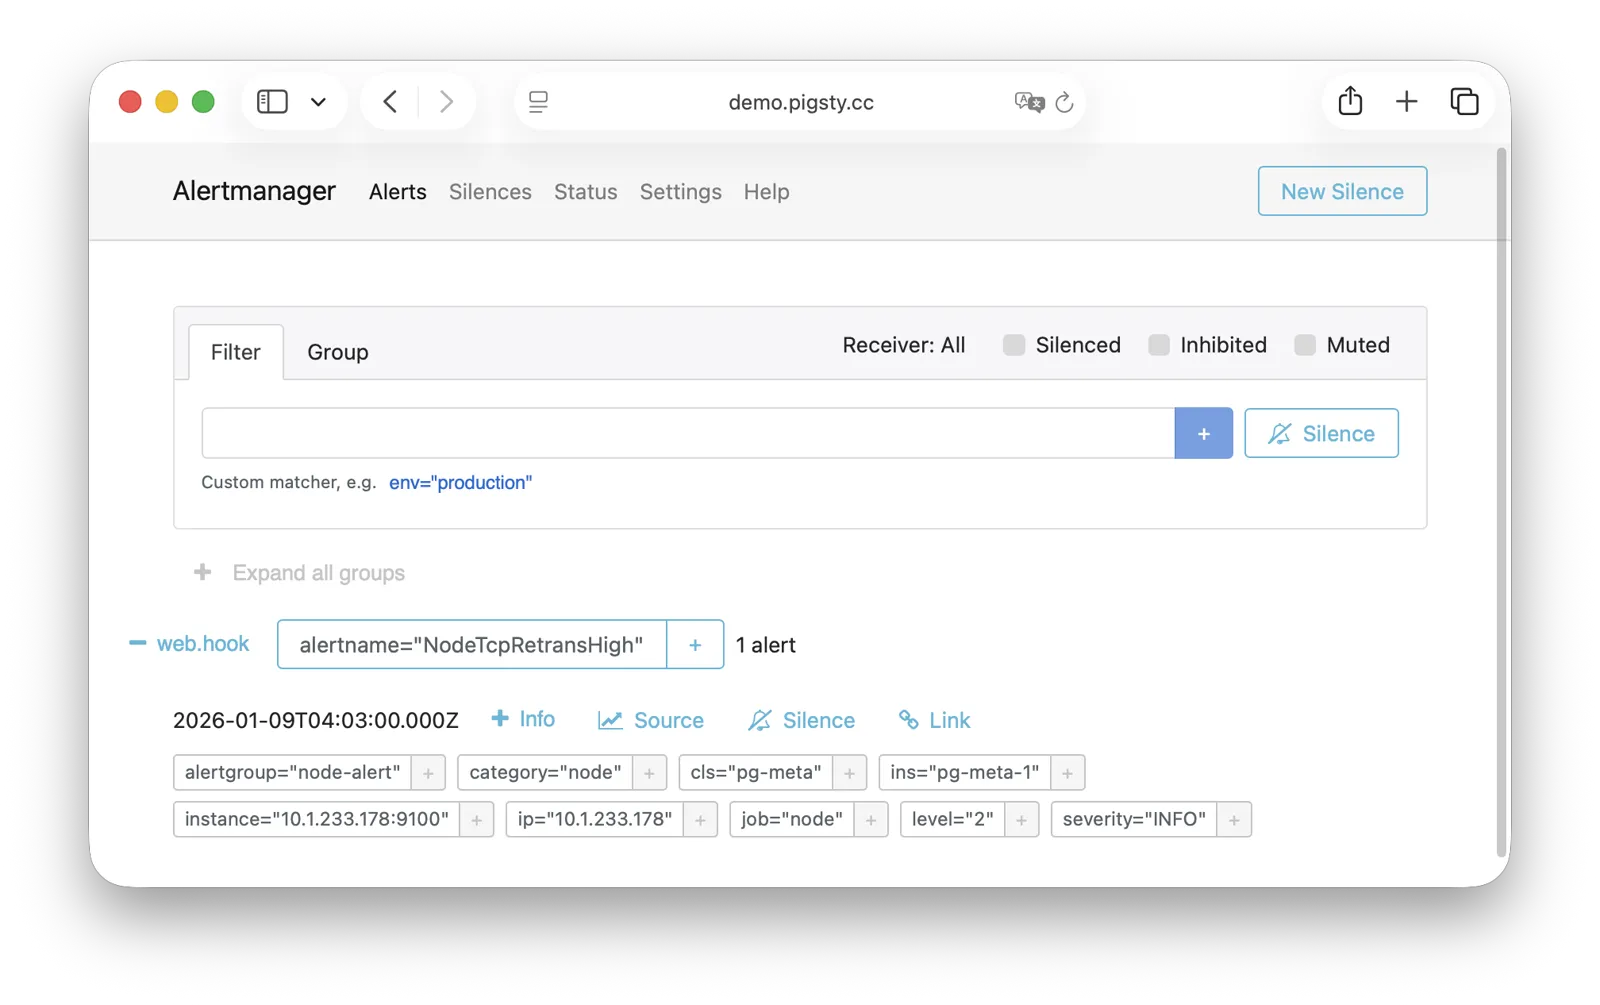
For more information, see: Config: INFRA - AlertManager
BlackboxExporter
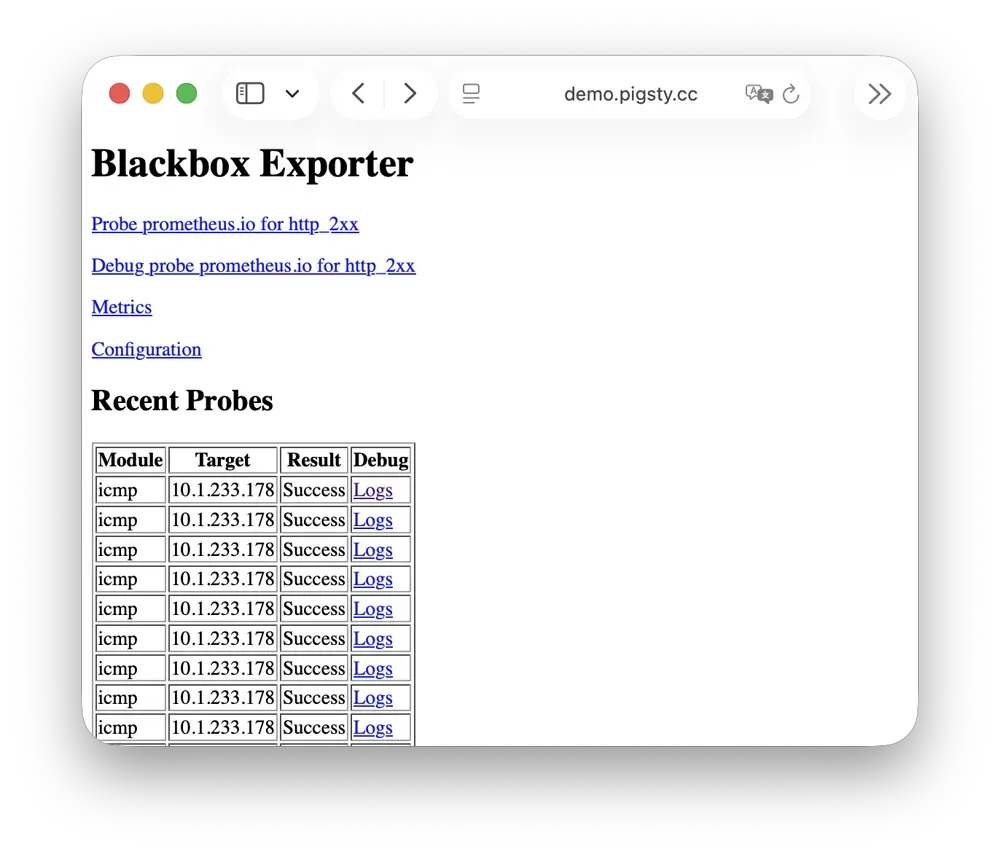
Blackbox Exporter probes targets to check reachability.
It listens on port 9115 by default, mounted at Nginx /blackbox path:
| IP Access (replace) | Domain (HTTP) | Domain (HTTPS) | Public Demo |
|---|---|---|---|
http://10.10.10.10/blackbox | http://i.pigsty/blackbox | https://i.pigsty/blackbox | https://demo.pigsty.io/blackbox |
Probe methods include ICMP Ping, TCP ports, and HTTP/HTTPS endpoints. Check VIP reachability, service ports, and external dependencies to determine the scope of a failure.
For more information, see: Config: INFRA - BLACKBOX
Ansible
Ansible runs Pigsty deployment, configuration, and management playbooks.
Installation adds Ansible to the administration/infrastructure node. Declarative configuration specifies the target state. Idempotent playbooks can run repeatedly to reach that state without additional side effects.
Ansible provides:
- Agentless execution: Connect through SSH without installing an agent on managed nodes.
- Declarative configuration: Describe the target state; configuration also documents it.
- Idempotent operations: Repeated runs produce consistent results and can retry partial failures.
For more information, see: Playbooks: Pigsty Playbook
DNSMASQ
DNSMASQ provides DNS resolution on INFRA nodes, resolving domain names to their corresponding IP addresses.
DNSMASQ listens on port 53 (UDP/TCP) by default, providing DNS resolution for all nodes. Records are stored in the /etc/dnsmasq.d/pigsty directory.
Other modules register domain names with DNSMASQ during deployment. Client nodes can use infrastructure nodes as DNS servers and access services by name. DNS is optional; Pigsty also works without it.
dns_records: Default DNS records written to INFRA nodesnode_dns_servers: Configure DNS servers for nodes, defaults to INFRA node viaadmin_ip(can also be disabled)
For more information, see: Config: INFRA - DNS and Tutorial: DNS—Configure Domain Resolution
Chronyd
Chronyd synchronizes node clocks through NTP. Its time-source service uses UDP port 123 by default.
Distributed systems need synchronized clocks. Logs need comparable timestamps, certificate checks need accurate time, and PostgreSQL streaming replication is sensitive to clock drift. In isolated networks, other nodes can synchronize to an infrastructure node acting as their NTP server.
All nodes run chronyd by default, using public pool.ntp.org servers. The Node module manages chronyd. In isolated networks, use admin_ip to select the INFRA node as the internal time source.
For more information, see: Config: NODE - TIME
INFRA Node vs Regular Node
In Pigsty, the relationship between nodes and infrastructure is a weak circular dependency: node_monitor → infra → node
NODE does not itself require INFRA. Its node_monitor functions require the infrastructure monitoring platform and services.
infra.yml and deploy resolve this dependency through these steps:
- Initialize NODE on regular nodes. Skip monitoring because the infrastructure is not ready.
- Initialize INFRA on the INFRA node to provide monitoring.
- Configure monitoring on regular nodes to connect to that platform.
Alternatively, use phased deployment: initialize infrastructure nodes before regular nodes.
How Are Nodes Coupled to Infrastructure?
Regular nodes use admin_ip to select an INFRA node for infrastructure services.
For example, global admin_ip = 10.10.10.10 normally directs all nodes to infrastructure at that address.
Change this address to switch infrastructure providers for many nodes. These parameters may reference ${admin_ip}:
| Parameter | Module | Default Value | Description |
|---|---|---|---|
repo_endpoint | INFRA | http://${admin_ip}:80 | Software repo URL |
repo_upstream.baseurl | INFRA | http://${admin_ip}/pigsty | Local repo baseurl |
infra_portal.endpoint | INFRA | ${admin_ip}:<port> | Nginx proxy backend |
dns_records | INFRA | ["${admin_ip} i.pigsty", ...] | DNS records |
node_default_etc_hosts | NODE | ["${admin_ip} i.pigsty"] | Default static DNS |
node_etc_hosts | NODE | [] | Custom static DNS |
node_dns_servers | NODE | ["${admin_ip}"] | Dynamic DNS servers |
node_ntp_servers | NODE | ["pool pool.ntp.org iburst"] | NTP servers (optional) |
For example, local uses the Nginx software repository at admin_ip:80/pigsty. DNS uses DNSMASQ at admin_ip:53. Both choices are optional. Nodes can install from Internet repositories, as most single-node templates do. They can also leave DNS unconfigured because Pigsty does not require it.
INFRA Node vs ADMIN Node
The ADMIN node usually also serves as the INFRA node, including in single-node deployments. With multiple infrastructure nodes, the first infra member usually administers the environment and others provide backups. You can also separate the roles.
For example, large production deployments can use 1–2 small DBA-managed VMs for administration. Use 2–3 high-capacity physical servers, or more, for monitoring infrastructure. Set admin_ip to an infrastructure node address. The parameter retains its historical name from when administration and infrastructure roles were combined.
For local management of cloud nodes, install Ansible on your laptop and select cloud servers as managed targets. The laptop is the administration node. Cloud servers provide infrastructure.
Multiple INFRA Nodes
One infrastructure node usually meets the requirements. Failure of its INFRA module does not interrupt database services on other nodes.
For higher monitoring and alerting availability, use multiple infrastructure nodes. Two nodes can provide redundancy and monitor each other. A distributed Victoria cluster can use more nodes for horizontal scaling without a fixed limit.
Each infrastructure node operates independently. Nginx uses local services, and VictoriaMetrics collects metrics from every environment service. Nodes send logs to all VictoriaLogs endpoints by default. Grafana is the exception: each instance registers every VictoriaMetrics, Logs, Traces, and PostgreSQL instance as a data source. Thus, each Grafana can access all monitoring data.
Dashboard and data-source changes affect only the Grafana instance you edit. For shared configuration, use a PostgreSQL database as Grafana storage. See Configure Grafana High Availability.
1.3 - PGSQL Arch
PGSQL organizes PostgreSQL as clusters. Each cluster is a logical group of database instances connected through primary-replica relationships.
Overview
The PGSQL module combines these components for production HA clusters:
| Component | Type | Description |
|---|---|---|
postgres | Database | Open-source relational database engine for PGSQL |
patroni | HA | Manages PostgreSQL, coordinates failover, leader election, config changes |
pgbouncer | Pool | Lightweight connection pooling middleware, reduces overhead, adds flexibility |
pgbackrest | Backup | Full/incremental backup and WAL archiving, supports local and object storage |
pg_exporter | Metrics | Exports PostgreSQL monitoring metrics in a Prometheus-compatible format |
pgbouncer_exporter | Metrics | Exports Pgbouncer connection pool metrics |
pgbackrest_exporter | Metrics | Exports backup status metrics |
vip-manager | VIP | Binds L2 VIP to current primary node for transparent failover [Optional] |
Enable vip-manager when needed. PGSQL also uses components from other modules:
| Component | Module | Type | Description |
|---|---|---|---|
haproxy | NODE | LB | Exposes service ports, routes traffic to primary or replicas |
vector | NODE | Logging | Collects PostgreSQL, Patroni, Pgbouncer logs and ships to center |
etcd | ETCD | DCS | Distributed consistent store for cluster metadata and leader info |
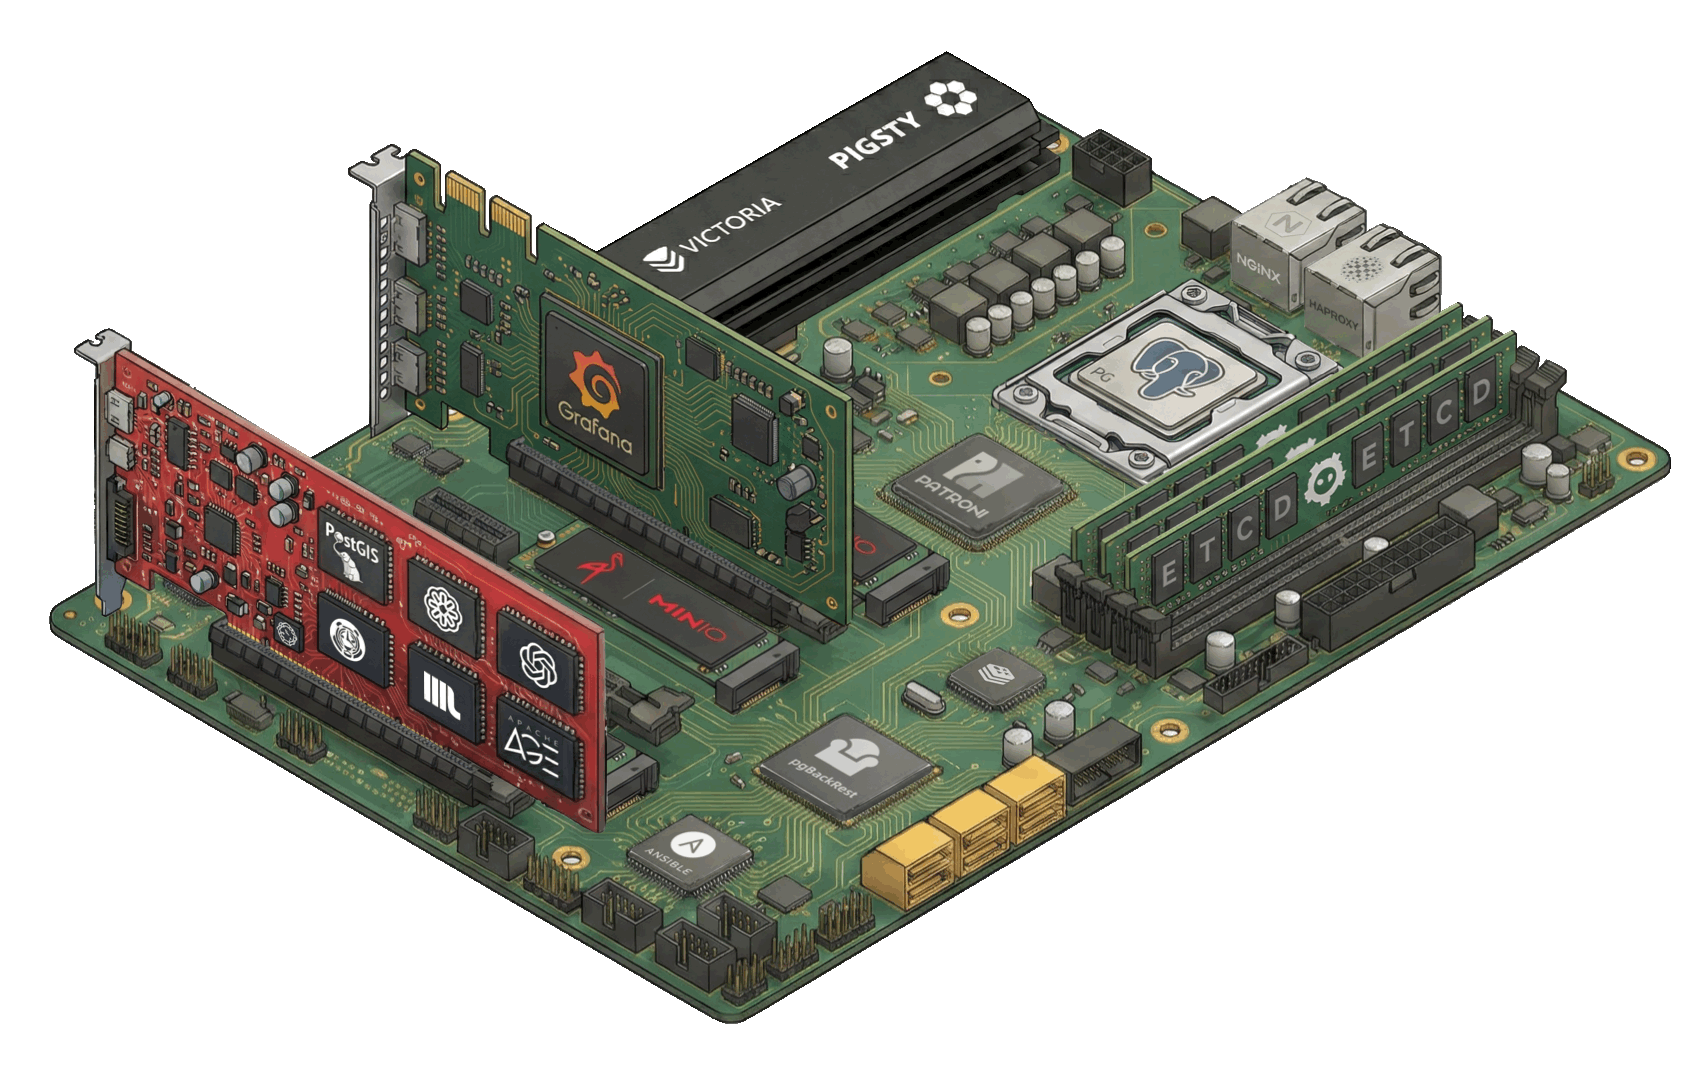
The PGSQL module combines the PostgreSQL engine with supporting services. Patroni and Etcd provide HA. pgBackRest and optional Silo provide backups. HAProxy, Pgbouncer, and vip-manager provide access. Exporters and Vector provide monitoring.
You can select other database kernels and extensions. The diagram represents the engine as a CPU and the complete service as a computer.
| Subsystem | Components | Function |
|---|---|---|
| HA Subsystem | Patroni + etcd | Failure detection, auto-failover, config management |
| Access Subsystem | HAProxy + Pgbouncer + vip-manager | Service exposure, load balancing, pooling, VIP |
| Backup Subsystem | pgBackRest (+ Silo) | Full/incremental backup, WAL archiving, PITR |
| Observability Subsystem | pg_exporter / pgbouncer_exporter / pgbackrest_exporter + Vector | Metrics collection, log aggregation |
Component Interaction
- Cluster DNS is resolved by DNSMASQ on infra nodes
- Cluster VIP is managed by vip-manager, which binds
pg_vip_addressto the cluster primary node.- vip-manager gets cluster leader info written by patroni from the etcd cluster
- Cluster services are exposed by HAProxy on nodes, different services distinguished by node ports (543x).
- HAProxy port 9101: Monitoring metrics & statistics & admin page
- HAProxy port 5433: Routes to primary pgbouncer: read-write service
- HAProxy port 5434: Routes to replica pgbouncer: read-only service
- HAProxy port 5436: Routes to primary postgres: default service
- HAProxy port 5438: Routes to offline postgres: offline service
- HAProxy routes traffic based on health check info from patroni.
- Pgbouncer is connection pooling middleware, listening on port 6432 by default, buffering connections, exposing additional metrics, and providing extra flexibility.
- PostgreSQL listens on port 5432, providing relational database services
- Installing PGSQL module on multiple nodes with the same cluster name automatically forms an HA cluster via streaming replication
- PostgreSQL process is managed by patroni by default.
- Patroni listens on port 8008 by default, supervising PostgreSQL server processes
- pg_exporter exposes postgres monitoring metrics on port 9630
- pgbouncer_exporter exposes pgbouncer metrics on port 9631
- pgBackRest uses local backup repository by default (
pgbackrest_method=local)- If using
local(default), pgBackRest creates local repository underpg_fs_bkupon primary node - If using
minio, pgBackRest creates the backup repository on dedicated Silo or an external S3 service
- If using
- Vector collects Postgres-related logs (postgres, pgbouncer, patroni, pgbackrest)
HA Subsystem
Patroni and etcd provide the HA subsystem. They detect failures, coordinate failover, and manage configuration.
Operation: Patroni manages each local PostgreSQL process. It writes the leader, members, and configuration to etcd. After primary failure, Patroni coordinates an election and promotes the healthiest replica. Recovery is automatic, with RTO typically below 45 seconds.
Key Interactions:
- PostgreSQL: Starts, stops, reloads PG as parent process, controls its lifecycle
- etcd: External dependency, writes/watches leader key for distributed consensus and failure detection
- HAProxy: Provides health checks via REST API (
:8008), reporting instance role - vip-manager: Watches leader key in etcd, auto-migrates VIP
For more information, see: High Availability and Config: PGSQL - PG_BOOTSTRAP
Access Subsystem
HAProxy, Pgbouncer, and vip-manager expose services, route traffic, and pool connections.
There are multiple access methods. A typical traffic path is: Client → DNS/VIP → HAProxy (543x) → Pgbouncer (6432) → PostgreSQL (5432)
| Layer | Component | Port | Role |
|---|---|---|---|
| L2 VIP | vip-manager | - | Binds L2 VIP to primary (optional) |
| L4 Load Bal | HAProxy | 543x | Service exposure, load balancing, health checks |
| L7 Pool | Pgbouncer | 6432 | Connection reuse, session management, transaction pooling |
Service Ports:
5433primary: Read-write service, routes to primary Pgbouncer5434replica: Read-only service, routes to replica Pgbouncer5436default: Default service, direct to primary (bypasses pool)5438offline: Offline service, direct to offline replica (ETL/analytics)
Key Features:
- HAProxy uses Patroni REST API to determine instance role, auto-routes traffic
- Pgbouncer uses transaction-level pooling, absorbs connection spikes, reduces PG connection overhead
- vip-manager watches etcd leader key, auto-migrates VIP during failover
For more information, see: Service Access and Config: PGSQL - PG_ACCESS
Backup Subsystem
pgBackRest provides backups and PITR. Optional Silo or external S3 storage can serve as the remote repository.
Backup Types:
- Full backup: Complete database copy
- Incremental/differential backup: Only backs up changed data blocks
- WAL archiving: Continuous transaction log archiving, enables any point-in-time recovery
Storage Backends:
local(default): Local disk, backups stored atpg_fs_bkupmount pointminio: S3-compatible object storage, supports centralized backup management and off-site DR
Key Interactions:
- pgBackRest → PostgreSQL: Executes backup commands, manages WAL archiving
- pgBackRest → Patroni: Recovery can bootstrap replicas as new primary or standby
- pgbackrest_exporter → VictoriaMetrics: Exports backup status metrics through the Prometheus-compatible protocol to monitor backup health
For more information, see: PITR, Backup & Recovery, and Config: PGSQL - PG_BACKUP
Observability Subsystem
Three Exporters collect metrics, and Vector collects logs.
| Component | Port | Target | Key Metrics |
|---|---|---|---|
| pg_exporter | 9630 | PostgreSQL | Sessions, transactions, replication lag, buffer hits |
| pgbouncer_exporter | 9631 | Pgbouncer | Pool utilization, wait queue, hit rate |
| pgbackrest_exporter | 9854 | pgBackRest | Latest backup time, size, type |
| vector | 9598 | postgres/patroni/pgbouncer logs | Structured log stream |
Data Flow:
- Metrics: Exporter → VictoriaMetrics (INFRA) → Grafana dashboards
- Logs: Vector → VictoriaLogs (INFRA) → Grafana log queries
pg_exporter and pgbouncer_exporter use local Unix sockets, independently of HA topology. Slim installation can disable them.
For more information, see: Config: PGSQL - PG_MONITOR
PostgreSQL
PostgreSQL is the PGSQL database engine. It listens on 5432 by default, with one instance per node.
Pigsty supports PostgreSQL 14–18 through binary packages from the PGDG repository. You can replace the default engine with a PG-compatible kernel. Up to 600 extensions are available.
Patroni manages PostgreSQL processes for HA by default. A single-node cluster has one primary. Additional nodes automatically join as replicas and receive changes through real-time physical replication. Replicas serve read-only traffic and can automatically replace a failed primary.
You can access PostgreSQL directly, or through HAProxy and Pgbouncer connection pool.
For more information, see: Config: PGSQL - PG_BOOTSTRAP
Patroni
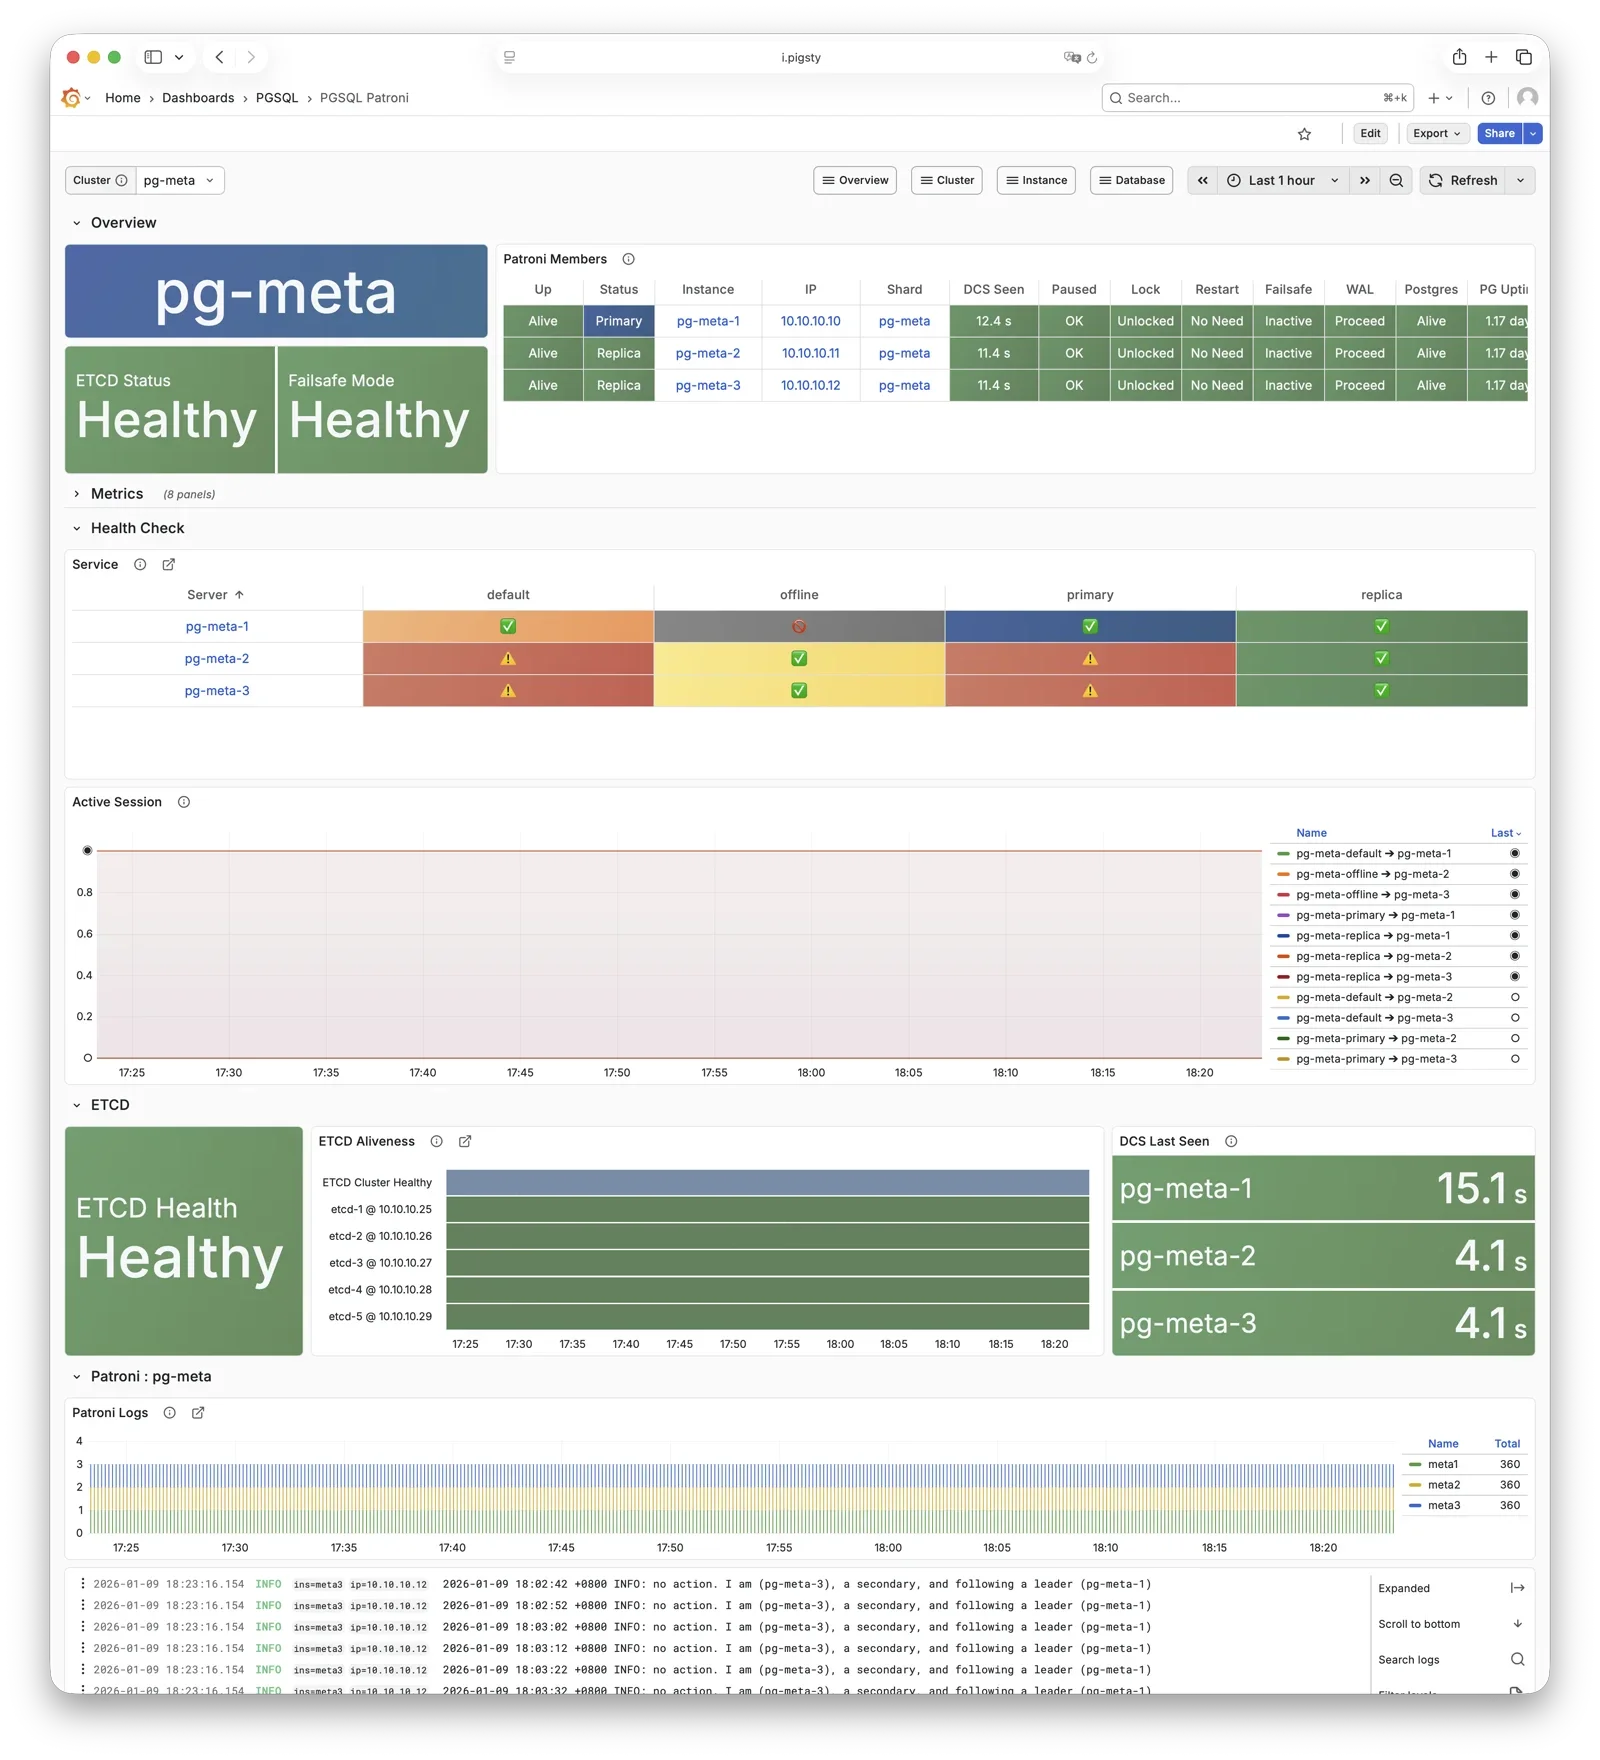
Patroni is the PostgreSQL HA control component, listening on port 8008 by default.
Patroni manages PostgreSQL startup, shutdown, configuration, and health. It writes leader and member records to etcd. It coordinates failover, replication factor, and parameter changes. Its REST API serves HAProxy, monitoring, and administrators.
HAProxy checks Patroni endpoints to identify instance roles and route primary or replica traffic. vip-manager watches the etcd leader key and moves the VIP when the primary changes.
For more information, see: Config: PGSQL - PG_BOOTSTRAP
Pgbouncer
Pgbouncer provides connection pooling on port 6432 by default. Each node has one Pgbouncer instance for its PostgreSQL instance.
Pgbouncer is stateless and connects to local PostgreSQL through a Unix socket. Its default transaction pooling handles connection bursts, stabilizes session counts, and reduces lock contention. This improves performance under high concurrency.
By default, read/write 5433 and read-only 5434 traffic use Pgbouncer. Default 5436 and offline 5438 services connect directly to PostgreSQL.
pgbouncer_poolmode defaults to transaction. Disable pooling with pgbouncer_enabled.
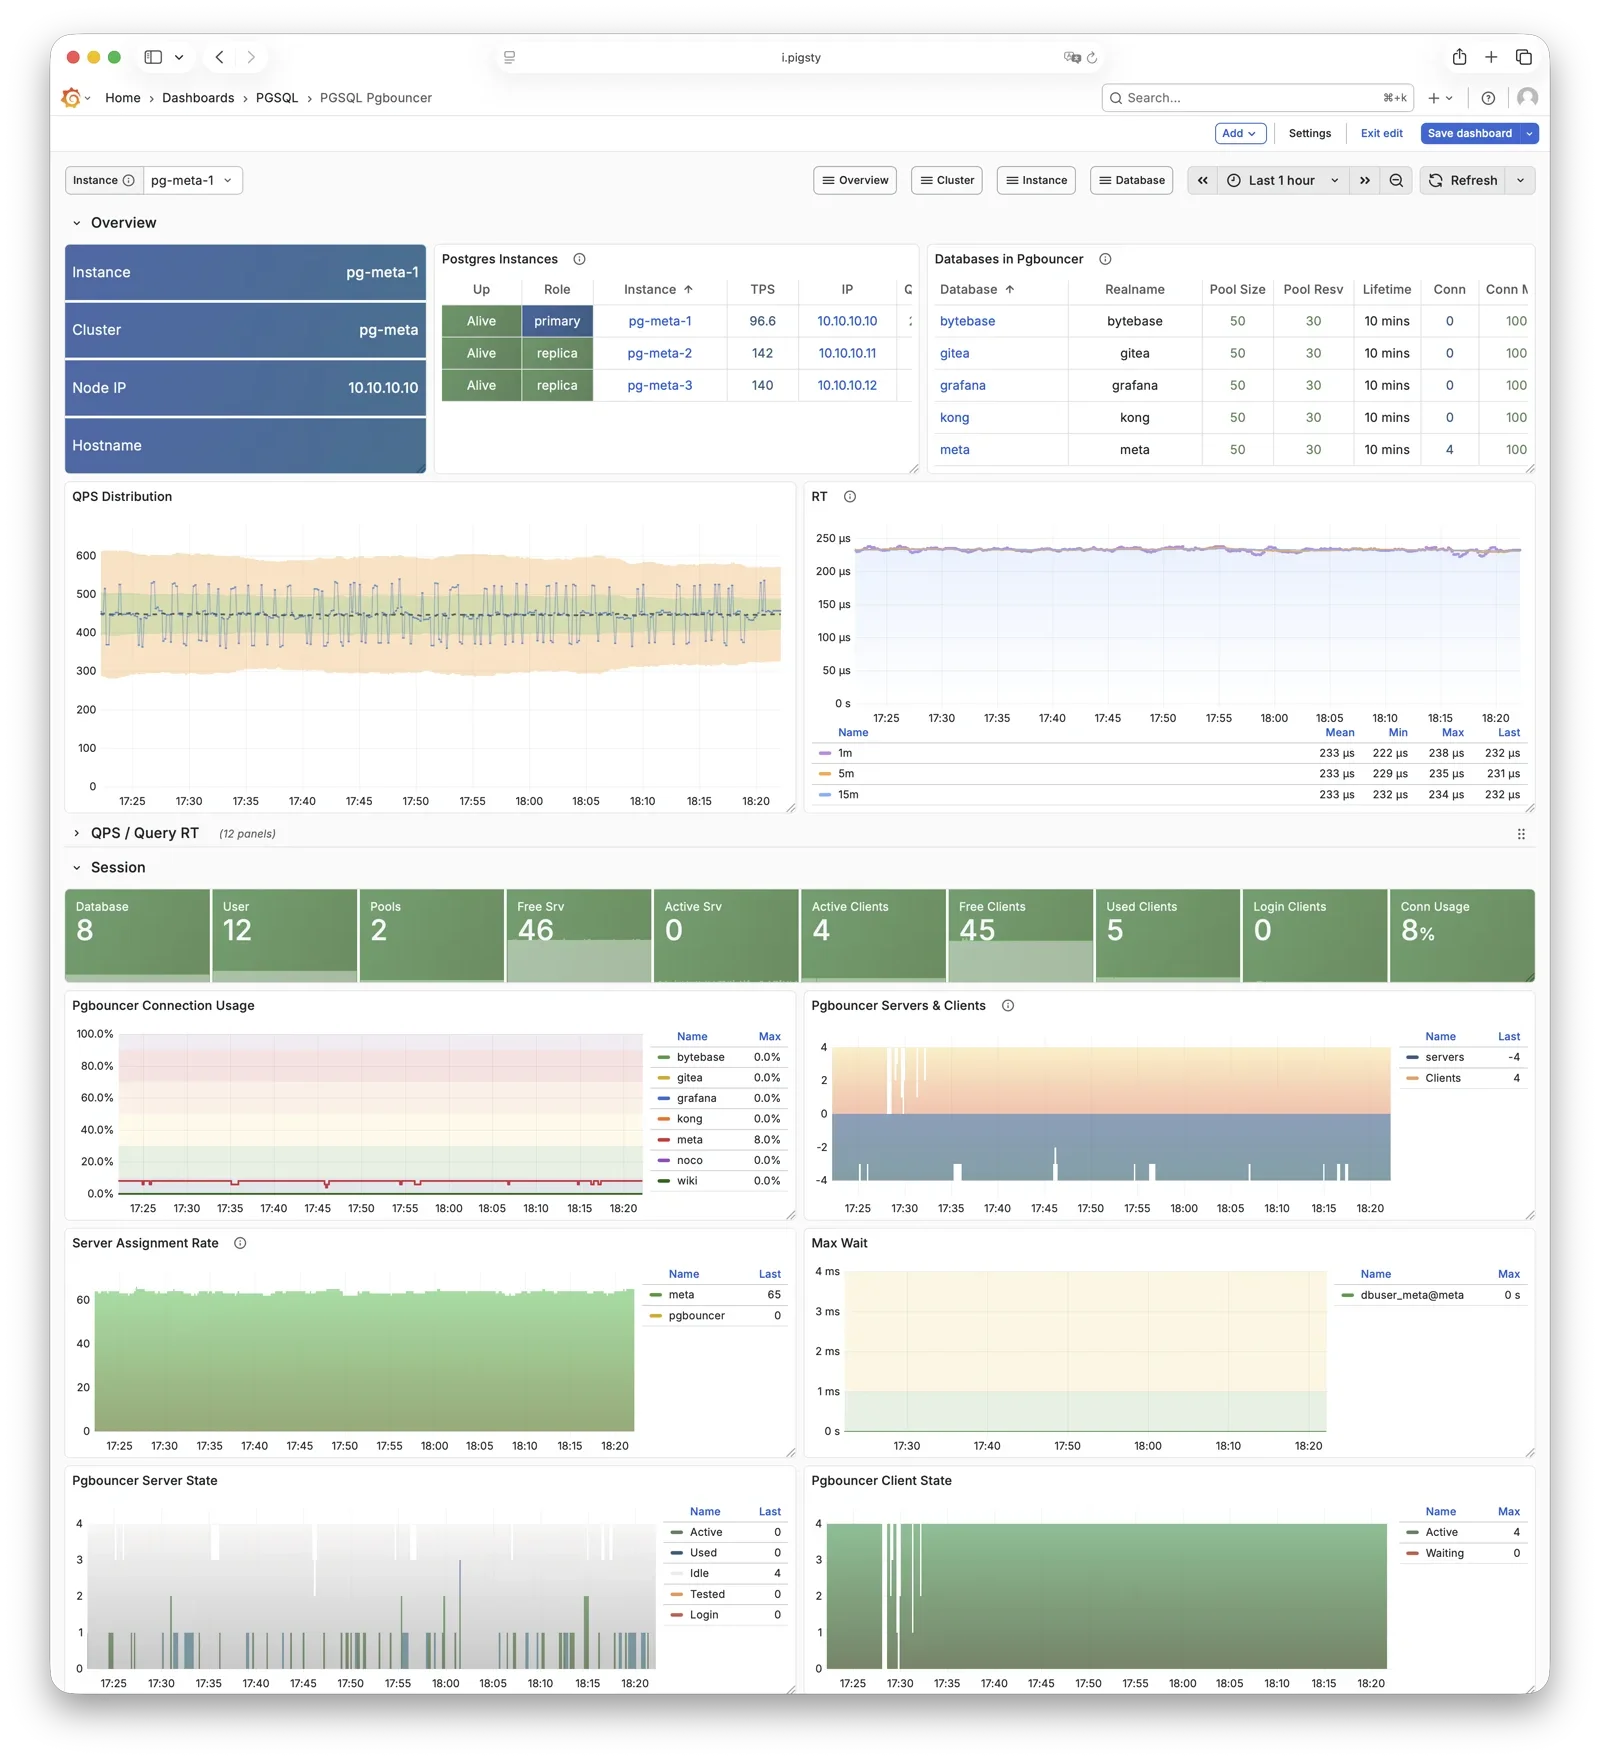
For more information, see: Config: PGSQL - PG_ACCESS
pgBackRest
pgBackRest provides full, incremental, and differential PostgreSQL backups and WAL archiving.
Pigsty uses pgBackRest for PITR to any time within the backup retention window.
pgBackRest coordinates with PostgreSQL for backups and archiving. By default, it creates a repository on the primary: pgbackrest_method = local. Configure Silo or external S3 storage for centralized backup management.
pgbackrest_init_backup can trigger the first full backup after initialization. Recovery integrates with Patroni to initialize replicas as new primaries or standbys.
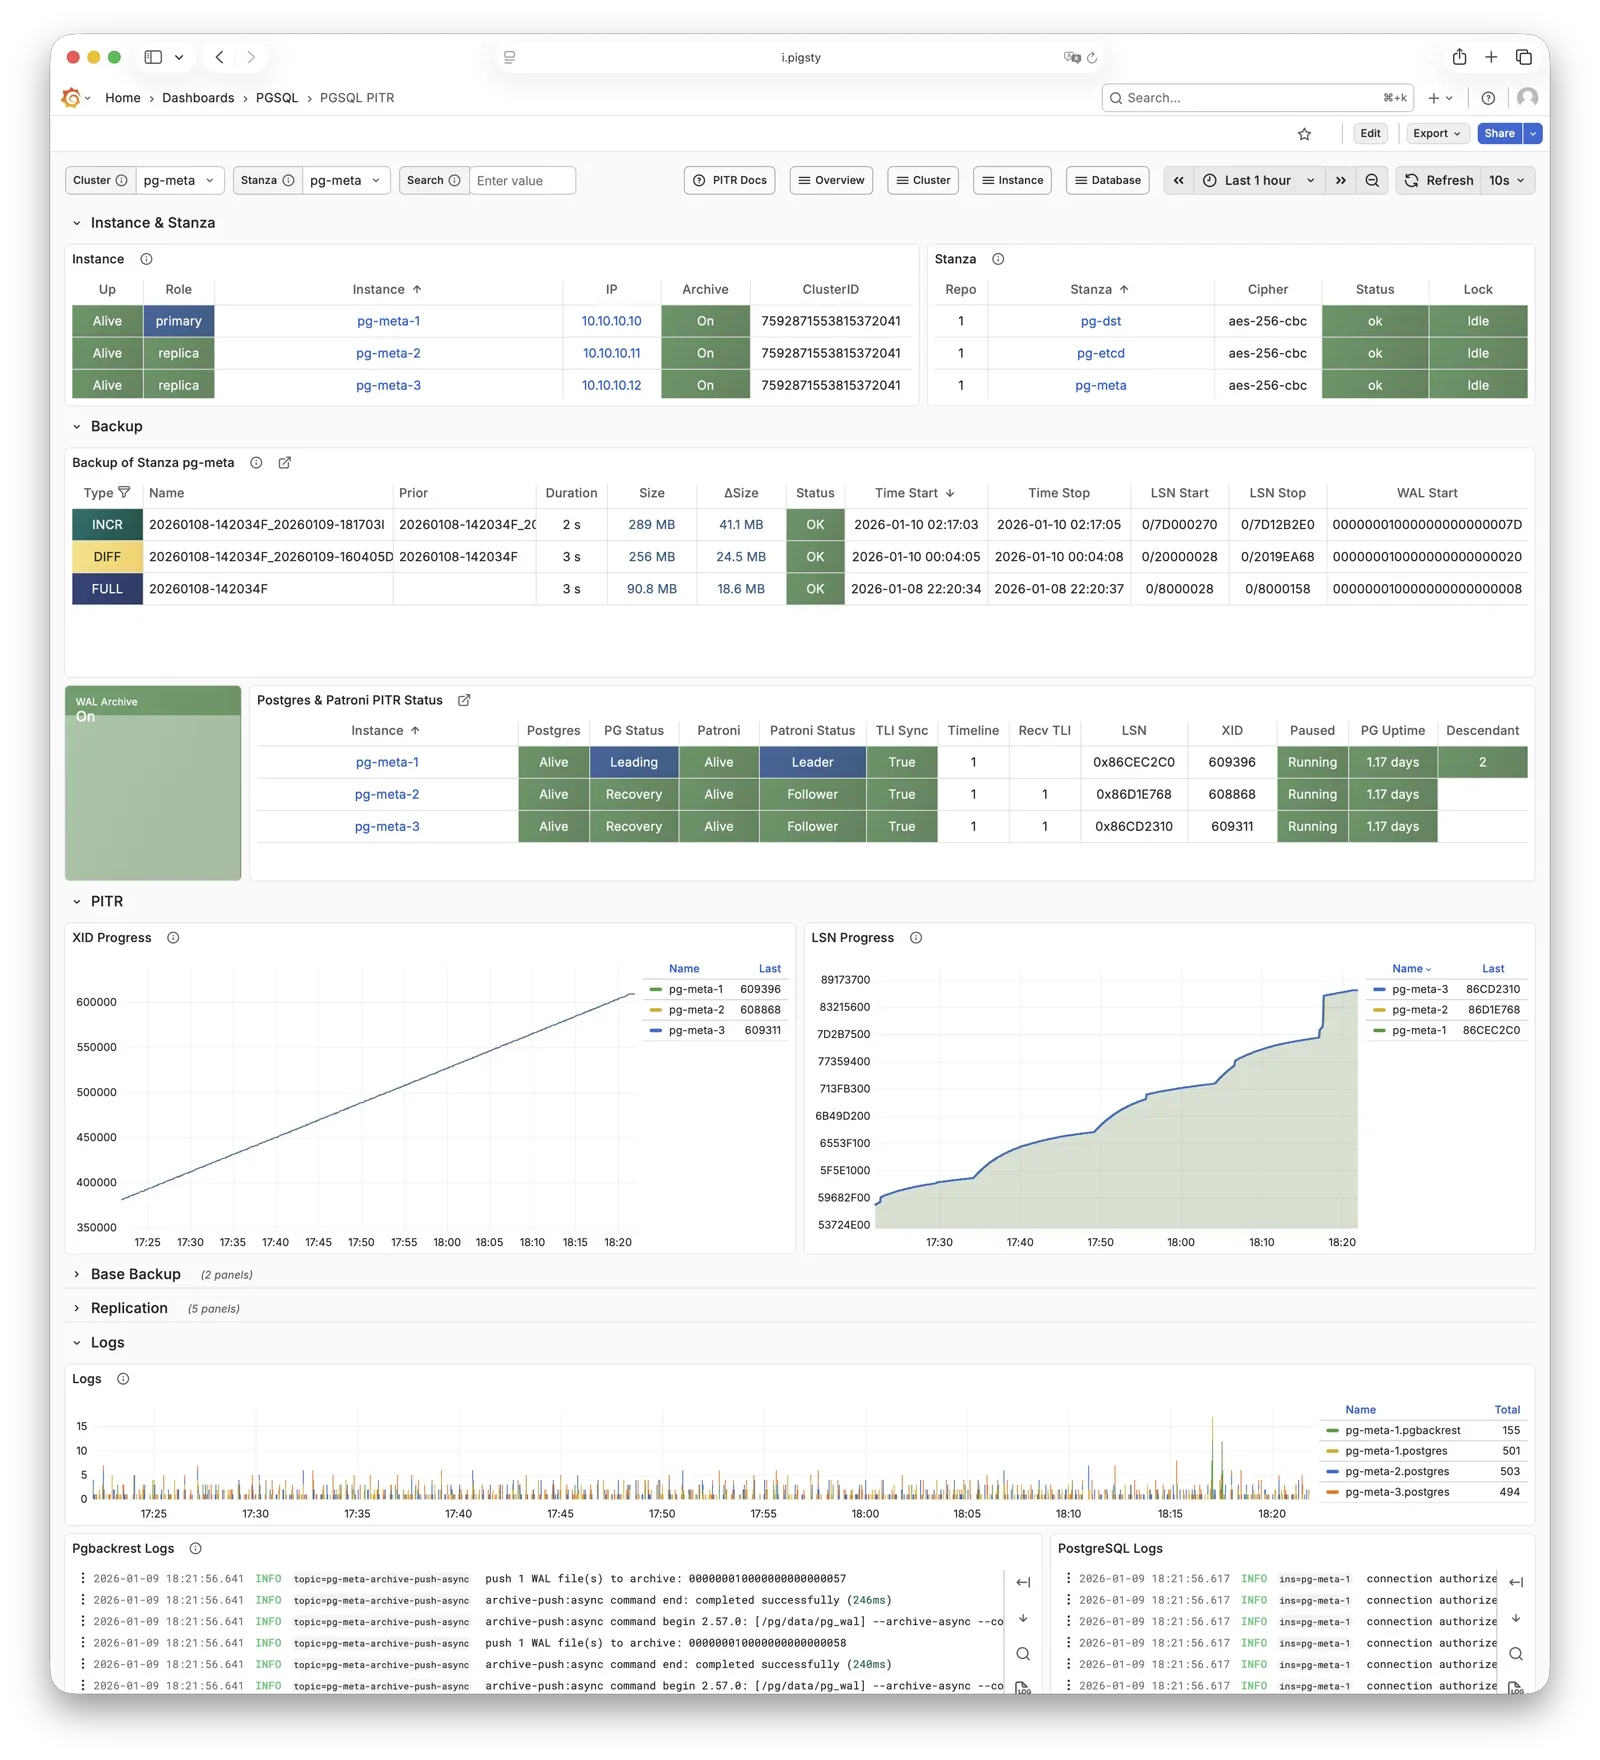
For more information, see: Backup & Recovery and Config: PGSQL - PG_BACKUP
HAProxy
HAProxy is the service entry point and load balancer, exposing multiple database service ports.
| Port | Service | Target | Description |
|---|---|---|---|
9101 | Admin | - | HAProxy statistics and admin page |
5433 | primary | Primary Pgbouncer | Read-write service, routes to primary pool |
5434 | replica | Replica Pgbouncer | Read-only service, routes to replica pool |
5436 | default | Primary Postgres | Default service, direct to primary (bypasses pool) |
5438 | offline | Offline Postgres | Offline service, direct to offline replica (ETL/analytics) |
HAProxy checks Patroni REST endpoints to identify roles and route primary or replica traffic. pg_default_services and pg_services define services.
By default, local HAProxy instances expose services. For higher traffic, use pg_service_provider to select a dedicated HAProxy node group.
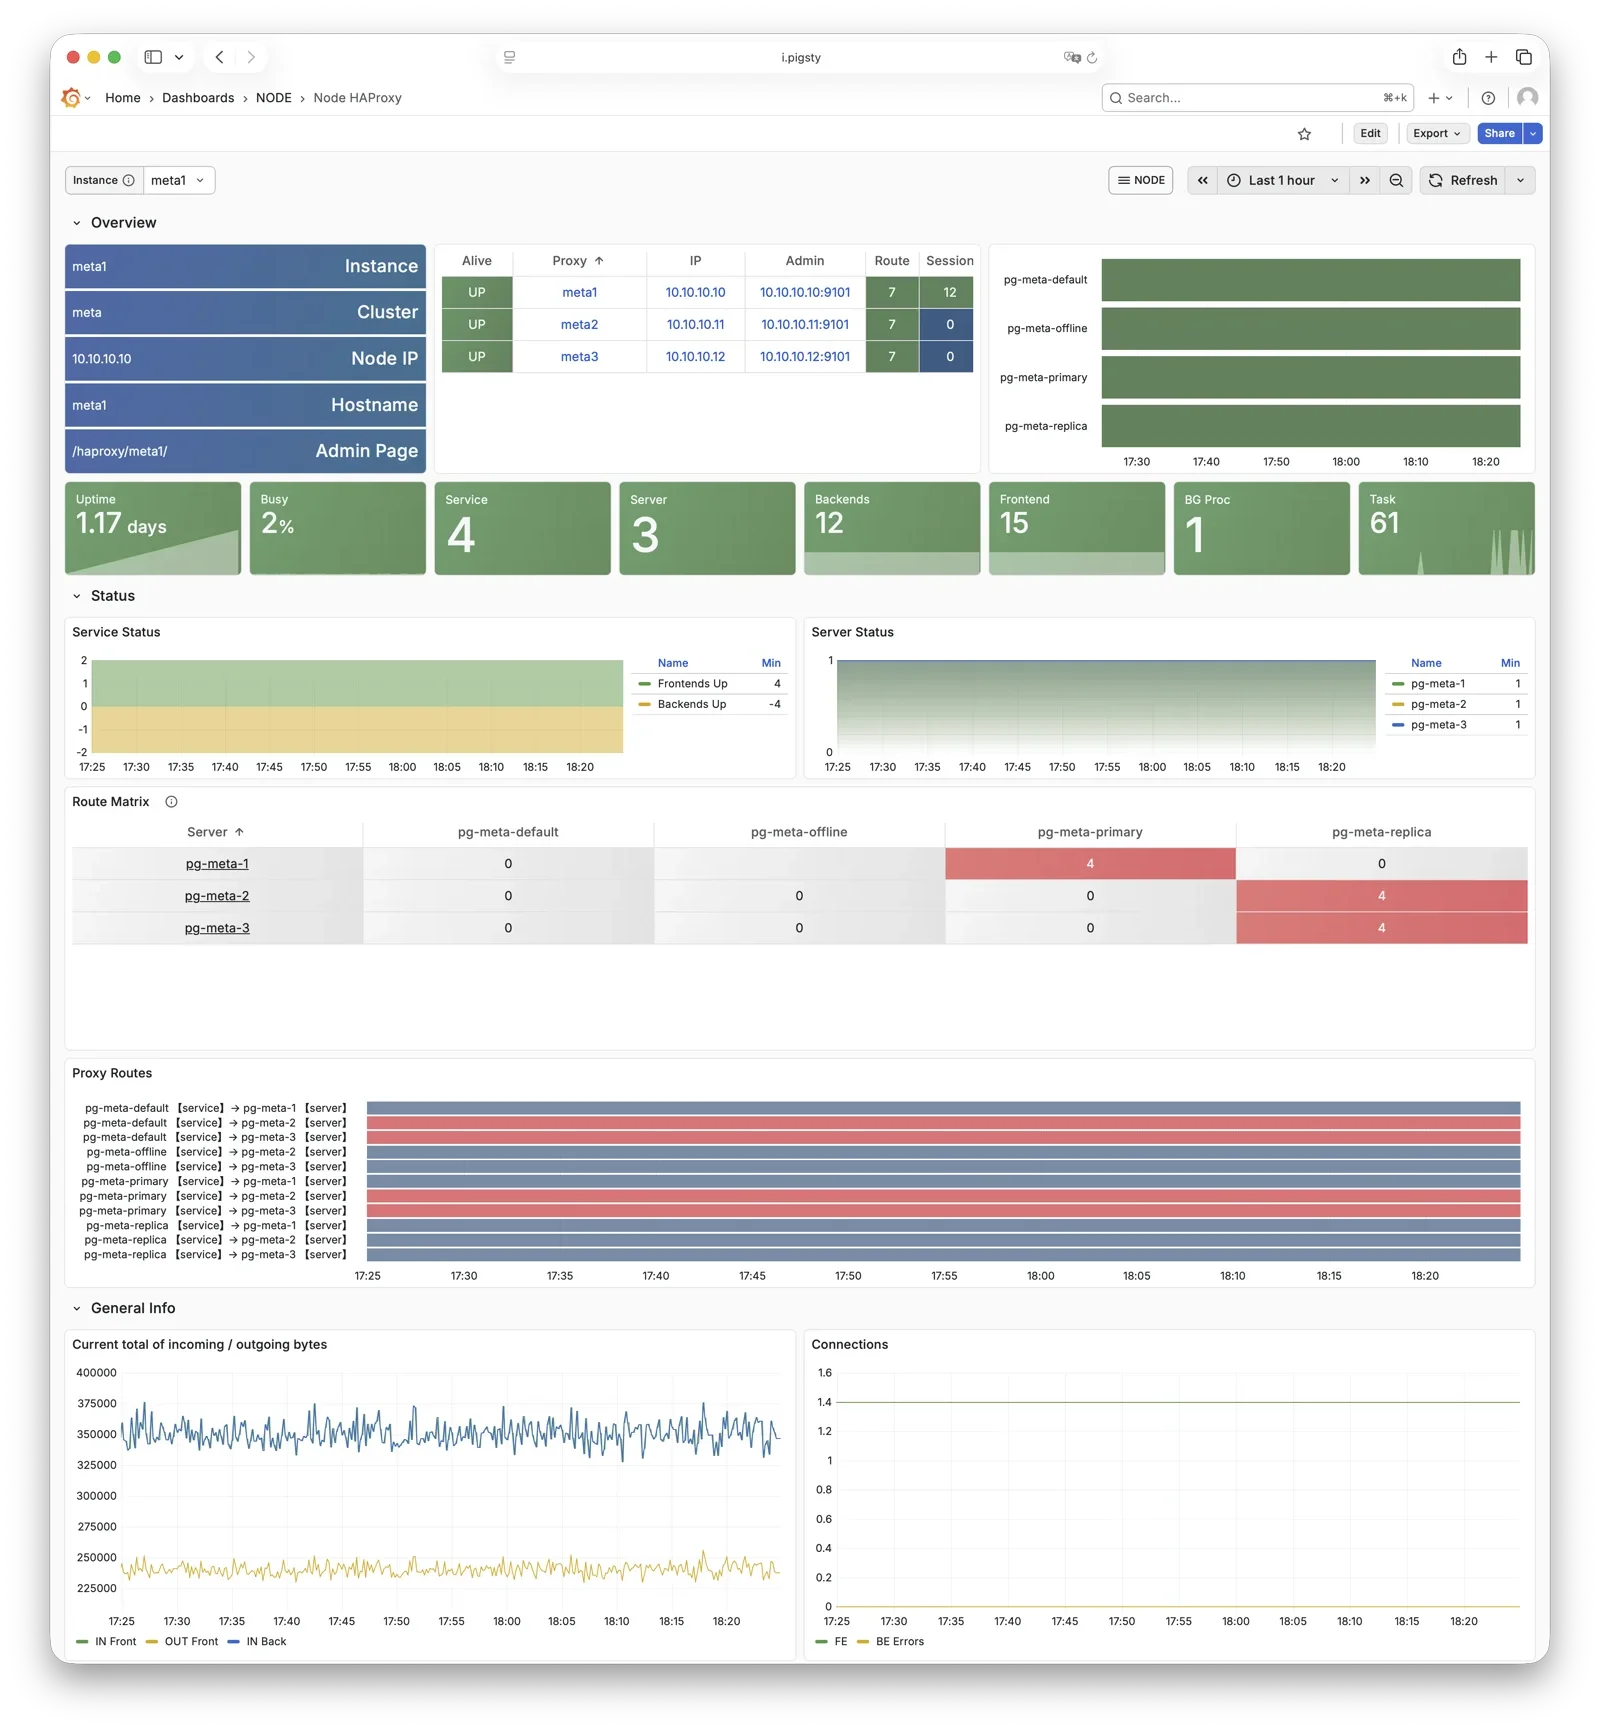
For more information, see: Service Access and Config: PGSQL - PG_ACCESS
vip-manager
vip-manager binds L2 VIP to the current primary node. This is an optional component; enable it if your network supports L2 VIP.
vip-manager runs on each PG node. It watches the leader key that Patroni writes to etcd. It binds pg_vip_address to the primary network interface. During failover, it releases the old binding and immediately binds the VIP to the new primary.
Enable this optional component with pg_vip_enabled. All nodes must share one VLAN or VIP migration fails. Public clouds usually do not support L2 VIP. Use it for on-premises or private cloud deployments.
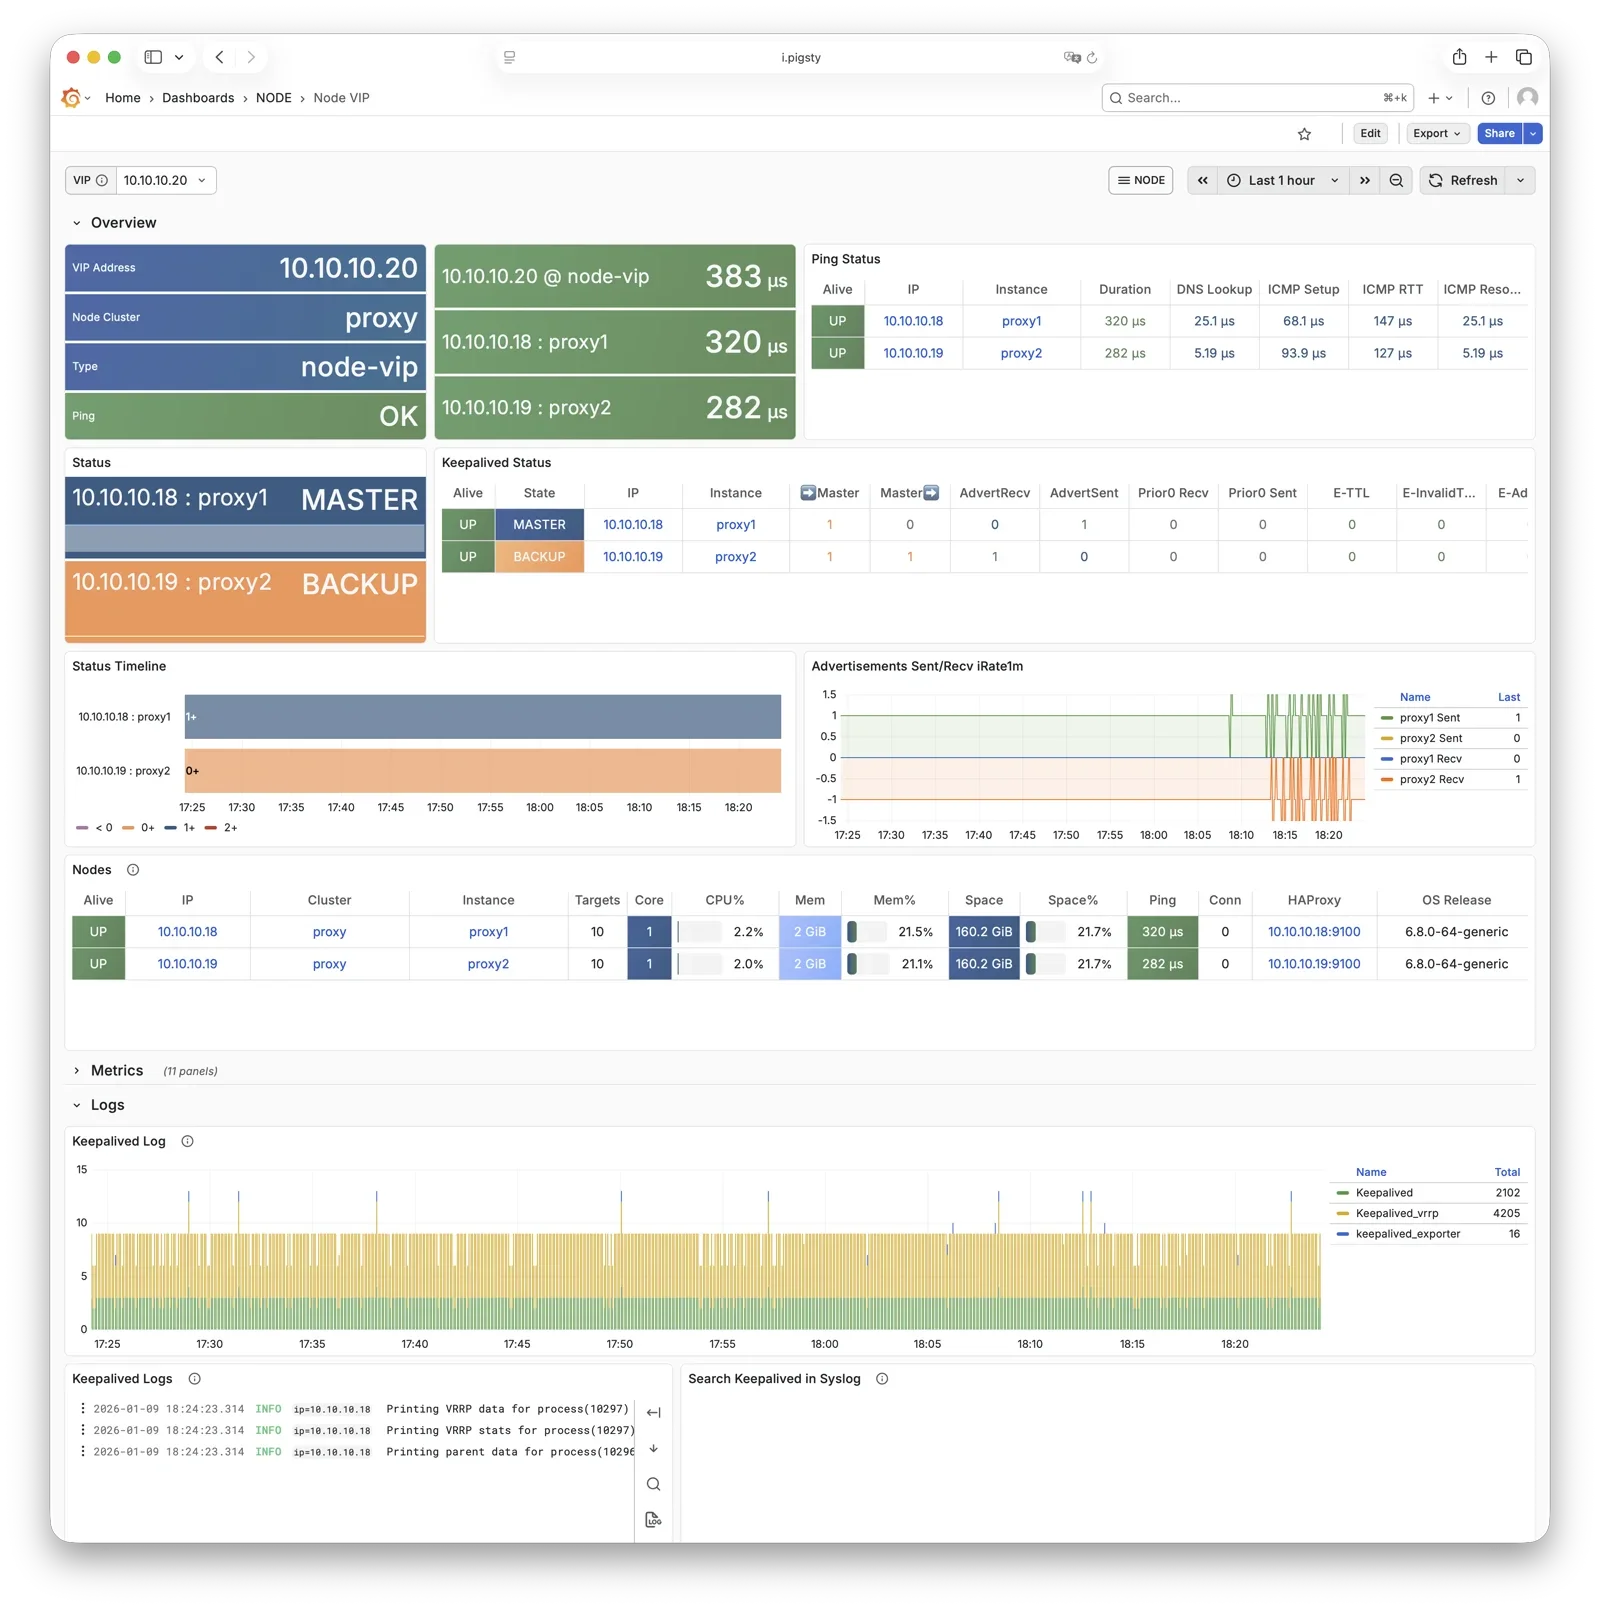
For more information, see: Tutorial: VIP Configuration and Config: PGSQL - PG_ACCESS
pg_exporter
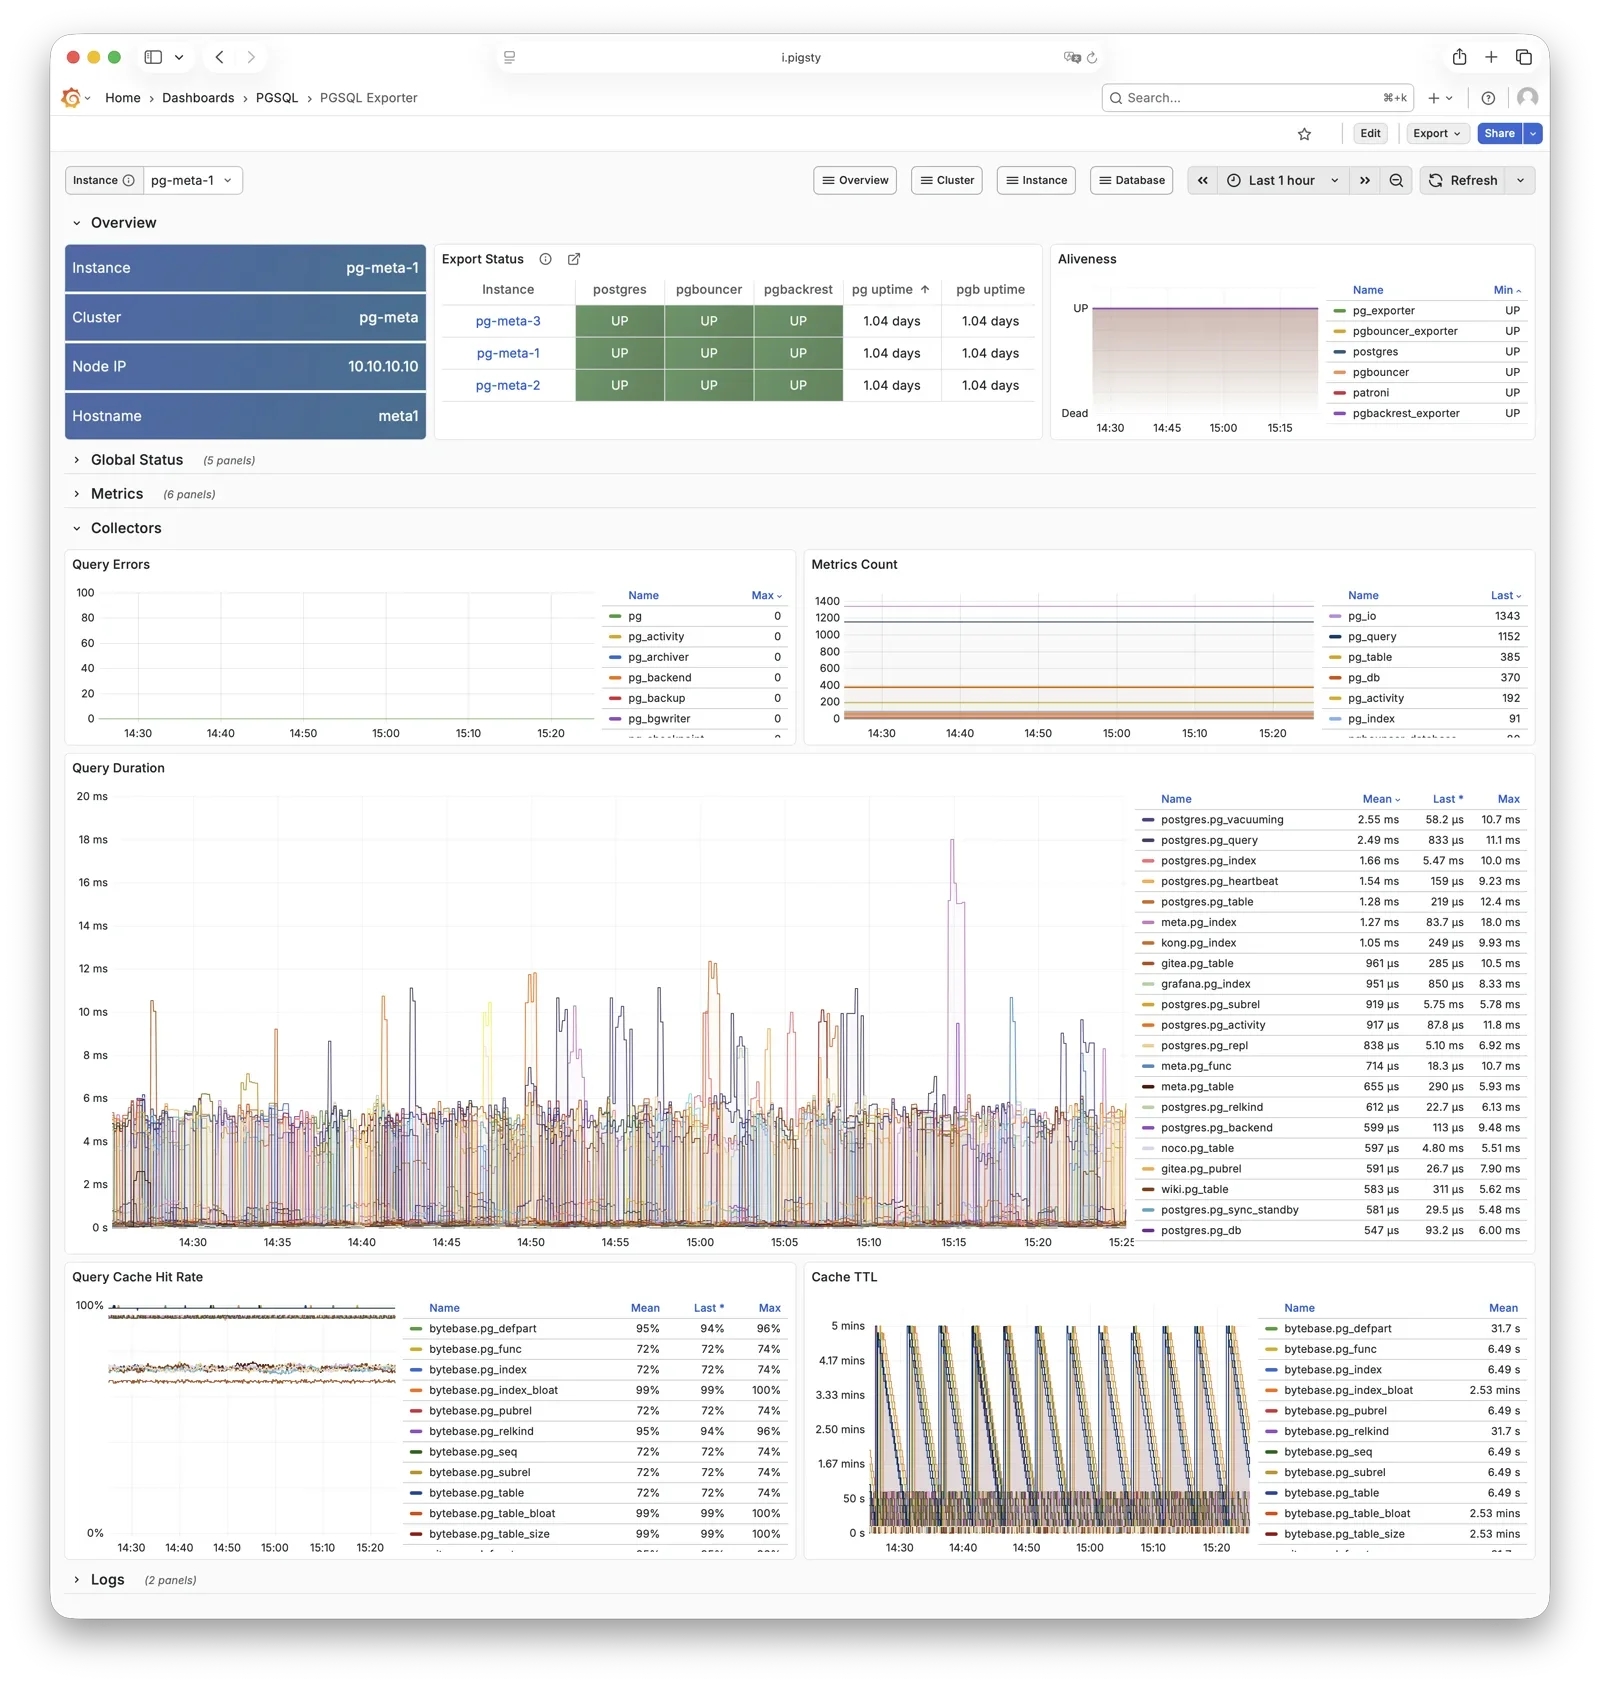
pg_exporter exports PostgreSQL monitoring metrics, listening on port 9630 by default.
pg_exporter connects to local PostgreSQL through a Unix socket. It exports sessions, buffer hits, replication lag, transaction rates, and other metrics. VictoriaMetrics on infrastructure nodes collects them.
Set collection rules with pg_exporter_config. Use pg_exporter_auto_discovery for automatic database discovery. pg_exporter_cache_ttls controls different cache lifetimes.
Disable this component through parameters. Slim installation leaves it disabled.
For more information, see: Config: PGSQL - PG_MONITOR
pgbouncer_exporter
pgbouncer_exporter exports Pgbouncer connection pool metrics, listening on port 9631 by default.
pgbouncer_exporter uses the pg_exporter binary with separate metric configuration. It supports pgbouncer 1.8–1.25+. Pgbouncer statistics views provide pool utilization, wait queue, and hit rate metrics.
Disabling Pgbouncer also disables its exporter. Slim installation leaves the exporter disabled.
For more information, see: Config: PGSQL - PG_MONITOR
pgbackrest_exporter
pgbackrest_exporter exports backup status metrics, listening on port 9854 by default.
pgbackrest_exporter reads pgBackRest status to report the latest backup time, size, type, and other metrics. Alert rules can detect expired or failed backups. Large repositories or many backups can make collection expensive. The default collection interval is 2 minutes, so a completed backup can take 2 minutes to appear in monitoring.
For more information, see: Config: PGSQL - PG_MONITOR
etcd
etcd is a distributed consistent store (DCS), providing cluster metadata storage and leader election capability for Patroni.
The separate ETCD module manages etcd. PGSQL relies on it for HA. Patroni stores cluster state, leader information, and configuration there so nodes can reach consensus. vip-manager reads the leader key to move the VIP automatically.
For more information, see: ETCD Module
vector
The NODE module deploys Vector to collect PostgreSQL-related logs efficiently.
Vector reads node log directories for PostgreSQL, Pgbouncer, Patroni, and pgBackRest. It sends structured records to infrastructure-node VictoriaLogs for central storage and queries.
For more information, see: NODE Module
2 - ER Model
A deployment is the largest entity in Pigsty. This entity-relationship diagram shows its main entities and their relationships:
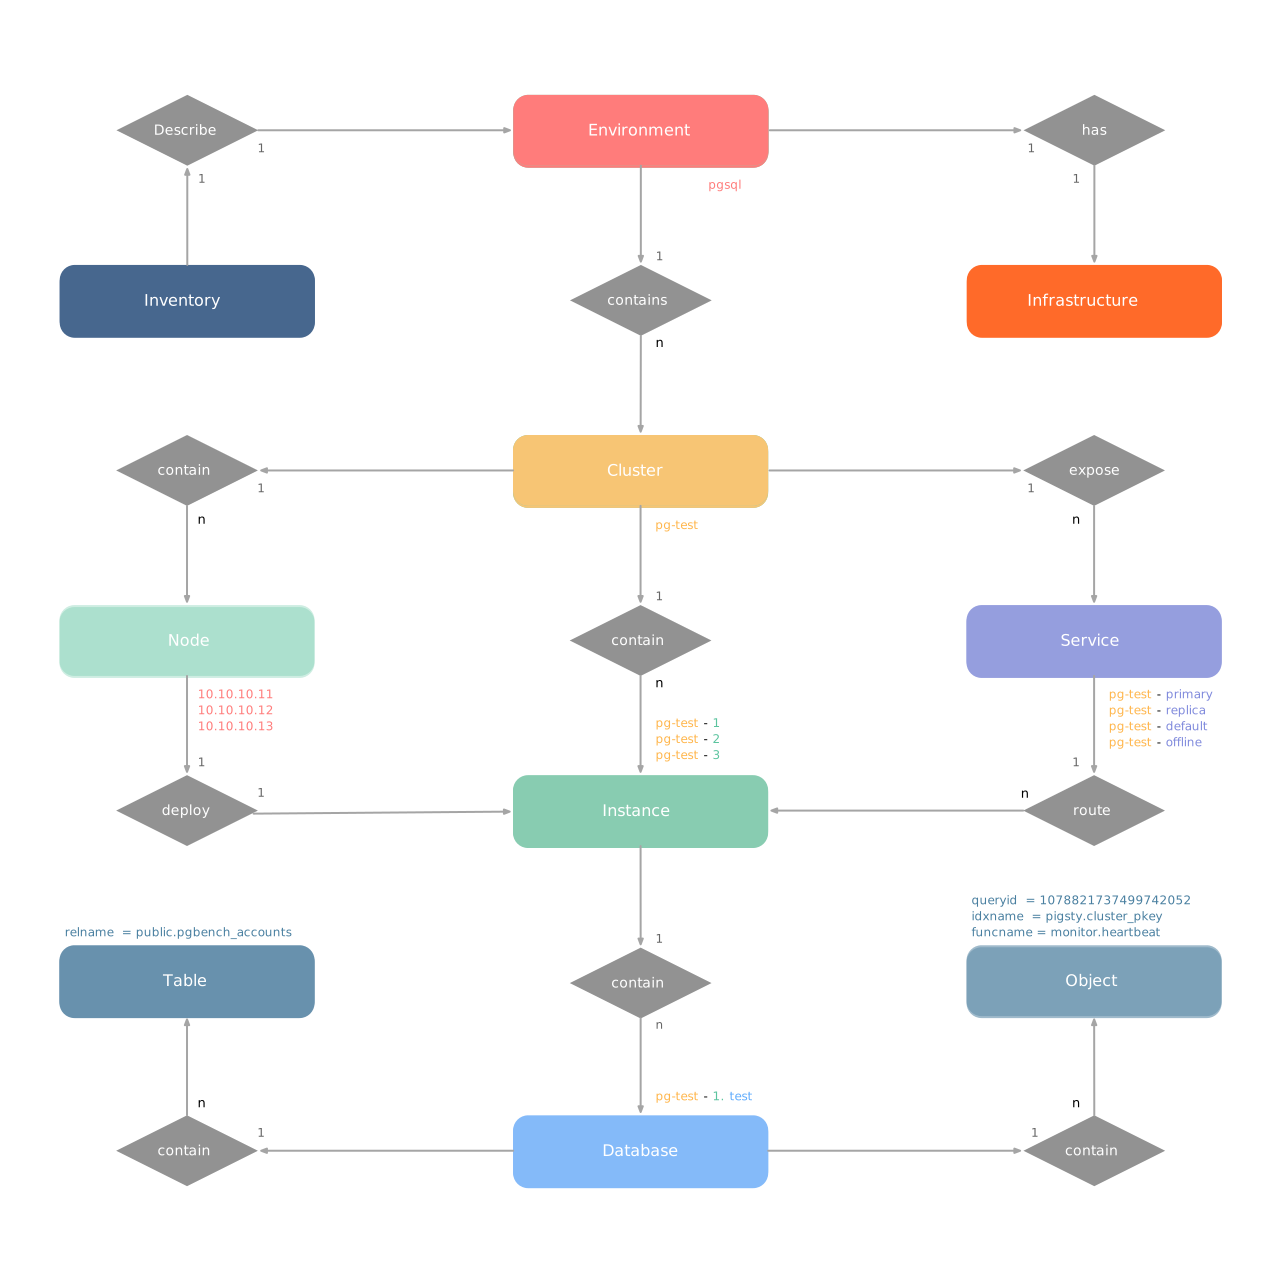
A deployment is also an environment. Examples include Production (Prod), User Acceptance Testing (UAT), Staging, Testing, and Development (Devbox). Each environment has a Pigsty inventory that describes all its entities and attributes.
An environment usually has shared infrastructure (INFRA). This includes ETCD for the HA DCS and MINIO for centralized backup storage. Infrastructure serves multiple PostgreSQL clusters and other database modules. Deployments without infrastructure are also possible.
Pigsty organizes almost all database modules into clusters. Each cluster is an Ansible group with node resources. PostgreSQL HA, Redis, Etcd, and Silo use this model. An environment can contain multiple clusters.
2.1 - E-R Model of Infra Cluster
The INFRA module is a management hub made of infrastructure nodes, rather than a traditional cluster. It provides core services for the deployment. Each node is an autonomous service unit that runs components such as Nginx, Grafana, and VictoriaMetrics. Together, these nodes provide observability and management for database clusters.
There are two core entities in Pigsty’s INFRA module:
- Node: A server that runs infrastructure components. It can be a physical server, VM, container, or Pod.
- Component: An infrastructure service on a node, such as Nginx, Grafana, or VictoriaMetrics.
INFRA nodes usually also serve as administration nodes, which form the Pigsty control plane.
Component Composition
Each INFRA node runs the following core components:
| Component | Port | Description |
|---|---|---|
| Nginx | 80/443 | Web portal, local repo, unified reverse proxy |
| Grafana | 3000 | Visualization platform, dashboards, data apps |
| VictoriaMetrics | 8428 | Time-series database, Prometheus API compatible |
| VictoriaLogs | 9428 | Log database, receives structured logs from Vector |
| VictoriaTraces | 10428 | Trace storage for slow SQL / request tracing |
| VMAlert | 8880 | Alert rule evaluator based on VictoriaMetrics |
| Alertmanager | 9059 | Alert aggregation and dispatch |
| Blackbox Exporter | 9115 | ICMP/TCP/HTTP black-box probing |
| DNSMASQ | 53 | DNS server for internal domain resolution |
| Chronyd | 123 | NTP time server |
These components together form Pigsty’s observability infrastructure.
Examples
This example defines a two-node INFRA deployment:
The configuration defines these entities:
| Group | Description |
|---|---|
infra | INFRA infrastructure node group |
| Node | Description |
infra-1 | 10.10.10.10 INFRA node #1 |
infra-2 | 10.10.10.11 INFRA node #2 |
For production, use at least two INFRA nodes for component redundancy.
Identity Parameters
The INFRA_ID parameter group assigns deterministic identities to INFRA entities. One parameter is required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
infra_seq | int | Node | INFRA node sequence, required | Natural number, starting from 1, unique within group |
Set the node sequence number at node level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Node | infra-{{ infra_seq }} | infra-1, infra-2 |
INFRA assigns infra-N identifiers to distinguish infrastructure nodes in monitoring. This does not change their hostname or system identity. Nodes retain their existing hostname or IP address for identification.
Service Portal
INFRA nodes provide web access through Nginx. infra_portal defines the services that Nginx exposes.
The default configuration only defines the home server:
Pigsty configures reverse proxy endpoints for enabled components, including Grafana, VictoriaMetrics, and AlertManager. To access them through separate domains, add explicit configuration:
| Domain | Service | Description |
|---|---|---|
i.pigsty | Home | Pigsty homepage |
g.pigsty | Grafana | Monitoring dashboard |
p.pigsty | VictoriaMetrics | TSDB Web UI |
a.pigsty | Alertmanager | Alert management UI |
Use domain names to access Pigsty services where possible, instead of an IP address and port.
Deployment Scale
The number of INFRA nodes depends on deployment scale and HA requirements:
| Scale | INFRA Nodes | Description |
|---|---|---|
| Dev/Test | 1 | Single-node deployment, all on one node |
| Small Prod | 1-2 | Single or dual node, can share with other services |
| Medium Prod | 2-3 | Dedicated INFRA nodes, redundant components |
| Large Prod | 3+ | Multiple INFRA nodes, component separation |
In a single-node deployment, INFRA shares a node with PGSQL, ETCD, and other modules. Small deployments usually use INFRA nodes as the administration node, backup administration node, and local software repository (/www/pigsty). Larger deployments can assign these responsibilities to dedicated nodes.
Monitoring Label System
Pigsty collects metrics from INFRA components themselves. Unlike database modules, INFRA treats each component as a separate monitoring object. The cls (class) label distinguishes component types.
| Label | Description | Example |
|---|---|---|
cls | Component type, each forming a “class” | nginx |
ins | Instance name, format {component}-{infra_seq} | nginx-1 |
ip | INFRA node IP running the component | 10.10.10.10 |
job | VictoriaMetrics scrape job, fixed as infra | infra |
A two-node INFRA deployment with infra_seq: 1 and infra_seq: 2 uses these component labels:
| Component | cls | ins Example | Port |
|---|---|---|---|
| Nginx | nginx | nginx-1, nginx-2 | 9113 |
| Grafana | grafana | grafana-1, grafana-2 | 3000 |
| VictoriaMetrics | vmetrics | vmetrics-1, vmetrics-2 | 8428 |
| VictoriaLogs | vlogs | vlogs-1, vlogs-2 | 9428 |
| VictoriaTraces | vtraces | vtraces-1, vtraces-2 | 10428 |
| VMAlert | vmalert | vmalert-1, vmalert-2 | 8880 |
| Alertmanager | alertmanager | alertmanager-1, alertmanager-2 | 9059 |
| Blackbox | blackbox | blackbox-1, blackbox-2 | 9115 |
All INFRA component metrics have job="infra". The cls label distinguishes components:
2.2 - E-R Model of PostgreSQL Cluster
PGSQL organizes PostgreSQL as clusters. Each cluster is a logical group of database instances connected through primary-replica relationships.
Each cluster is an autonomous business unit with at least one primary instance. It exposes database capabilities through services.
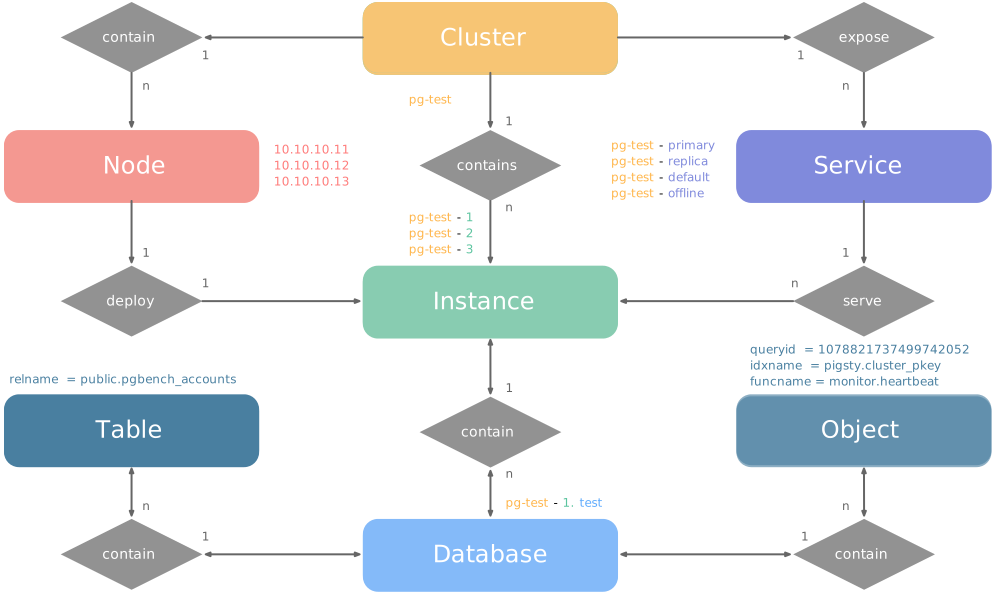
There are four core entities in Pigsty’s PGSQL module:
- Cluster: An autonomous PostgreSQL business unit and the top-level namespace for other entities.
- Service: A named abstraction that exposes capabilities and routes traffic through node ports.
- Instance: One PostgreSQL server, including its running processes and database files, on one node.
- Node: A hardware resource that runs Linux and Systemd. It can be a physical server, VM, container, or Pod.
Two business entities, Database and Role, complete this logical model:
Examples
The following two examples show the model. The four-node Pigsty sandbox contains a three-node pg-test cluster:
This configuration defines a high-availability PostgreSQL cluster with these entities:
| Cluster | Description |
|---|---|
pg-test | PostgreSQL 3-node HA cluster |
| Instance | Description |
pg-test-1 | PostgreSQL instance #1, default primary |
pg-test-2 | PostgreSQL instance #2, initial replica |
pg-test-3 | PostgreSQL instance #3, initial replica |
| Service | Description |
pg-test-primary | Read-write service (routes to primary pgbouncer) |
pg-test-replica | Read-only service (routes to replica pgbouncer) |
pg-test-default | Direct read-write service (routes to primary postgres) |
pg-test-offline | Offline read service (routes to dedicated postgres) |
| Node | Description |
node-1 | 10.10.10.11 Node #1, hosts pg-test-1 PG instance |
node-2 | 10.10.10.12 Node #2, hosts pg-test-2 PG instance |
node-3 | 10.10.10.13 Node #3, hosts pg-test-3 PG instance |
Identity Parameters
The PG_ID parameter group assigns deterministic identities to PGSQL entities. Three parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
pg_cluster | string | Cluster | PG cluster name, required | Valid DNS name, regex [a-zA-Z0-9-]+ |
pg_seq | int | Instance | PG instance number, required | Natural number, starting from 0 or 1, unique within cluster |
pg_role | enum | Instance | PG instance role, required | Enum: primary, replica, offline |
Set the cluster name at cluster level. Set each instance number and role at instance level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ pg_cluster }}-{{ pg_seq }} | pg-test-1, pg-test-2, pg-test-3 |
| Service | {{ pg_cluster }}-{{ pg_role }} | pg-test-primary, pg-test-replica, pg-test-offline |
| Node | Explicitly specified or borrowed from PG | pg-test-1, pg-test-2, pg-test-3 |
Pigsty uses an exclusive 1:1 mapping between nodes and PostgreSQL instances. By default, the node inherits its PostgreSQL instance identifier through node_id_from_pg. Set nodename to override this name. Alternatively, disable nodename_overwrite to retain the current default.
Sharding Identity Parameters
To serve one business with multiple PostgreSQL clusters (sharding), use two additional identity parameters: pg_shard and pg_group.
These clusters share one pg_shard name. Each has its own pg_group number, as in this Citus cluster:
A pg_cluster name usually combines {{ pg_shard }}{{ pg_group }}, for example pg-citus0 or pg-citus1.
Pigsty has dedicated dashboards for horizontally sharded clusters. Use this naming convention to compare shard performance and load in those dashboards.
Other identity parameters support specific uses:
pg_upstream: Set the upstream for a backup cluster or cascading replication.gp_role: Identify a Greenplum cluster role.pg_exporters: Define external monitoring instances.pg_offline_query: Define offline query instances.
See the PG_ID parameter documentation.
Monitoring Label System
The built-in monitoring system uses these identity parameters to identify PostgreSQL entities.
The labels cls, ins, and ip identify the cluster name, instance name, and node IP. They accompany job in all native VictoriaMetrics metrics and VictoriaLogs log streams.
These job values are fixed:
pgsql: PostgreSQL metrics.pgrds: Remote PostgreSQL instance metrics.postgres: PostgreSQL CSV logs.pgbackrest: pgBackRest logs.
Other PostgreSQL components collect logs through job: syslog.
Specific entity metrics also have these identity labels:
datname: Database name, if a metric belongs to a specific database.relname: Table name, if a metric belongs to a specific table.idxname: Index name, if a metric belongs to a specific index.funcname: Function name, if a metric belongs to a specific function.seqname: Sequence name, if a metric belongs to a specific sequence.query: Query fingerprint, if a metric belongs to a specific query.
2.3 - E-R Model of Etcd Cluster
The ETCD module organizes production ETCD into clusters. A cluster is a logical entity whose ETCD instances coordinate through the Raft consensus protocol.
Each cluster is an autonomous distributed key-value store with at least one ETCD instance. It provides services through client ports.
There are three core entities in Pigsty’s ETCD module:
- Cluster: An autonomous ETCD service unit and the top-level namespace for other entities.
- Instance: One ETCD server process on a node, participating in Raft consensus.
- Node: An implicitly declared hardware resource that runs Linux and Systemd.
The ETCD model has no Service entities or complex Role distinctions, unlike PostgreSQL. All ETCD instances are functionally equivalent. Raft elects one Leader; the others become Followers. Non-voting Learner members are also permitted during intermediate scale-out states.
Examples
This example defines a three-node ETCD cluster:
The configuration defines these entities:
| Cluster | Description |
|---|---|
etcd | ETCD 3-node HA cluster |
| Instance | Description |
etcd-1 | ETCD instance #1 |
etcd-2 | ETCD instance #2 |
etcd-3 | ETCD instance #3 |
| Node | Description |
10.10.10.10 | Node #1, hosts etcd-1 instance |
10.10.10.11 | Node #2, hosts etcd-2 instance |
10.10.10.12 | Node #3, hosts etcd-3 instance |
Identity Parameters
The ETCD parameter group assigns deterministic identities to ETCD entities. Two parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
etcd_cluster | string | Cluster | ETCD cluster name, required | Valid DNS name, defaults to fixed etcd |
etcd_seq | int | Instance | ETCD instance number, required | Natural number, starting from 1, unique within cluster |
Set the cluster name at cluster level and the instance number at instance level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ etcd_cluster }}-{{ etcd_seq }} | etcd-1, etcd-2, etcd-3 |
ETCD does not assign a separate identity to host nodes. It uses their existing hostname or IP address.
Ports & Protocols
Each ETCD instance listens on the following two ports:
| Port | Parameter | Purpose |
|---|---|---|
| 2379 | etcd_port | Client port, accessed by Patroni, vip-manager, etc. |
| 2380 | etcd_peer_port | Peer communication port, used for Raft consensus |
ETCD clusters enable TLS encryption and RBAC authentication by default. Clients need the correct certificates and passwords to access ETCD.
Cluster Size
ETCD cluster size determines availability. More than half the nodes, called a quorum, must be alive to maintain this distributed coordination service.
| Cluster Size | Quorum | Fault Tolerance | Use Case |
|---|---|---|---|
| 1 node | 1 | 0 | Dev, test, demo |
| 3 nodes | 2 | 1 | Small-medium production |
| 5 nodes | 3 | 2 | Large-scale production |
ETCD supports even member counts. However, they tolerate no more failures than the next smaller odd count. They also increase deployment and quorum costs. Production clusters therefore usually have one, three, or five members. Clusters with more than five members are uncommon.
Monitoring Label System
The built-in monitoring system uses these identity parameters to identify ETCD entities.
The labels cls, ins, and ip identify the cluster name, instance name, and node IP. They accompany job in all ETCD metrics collected by VictoriaMetrics. The ETCD metrics job is always etcd.
2.4 - MINIO Cluster Model
MINIO is the compatibility module name for object storage. Pigsty v4.5.0 deploys Silo with minio_type: silo. It groups object storage instances into a cluster.
Each cluster is an autonomous S3-compatible object store with at least one instance. It exposes services through the S3 API port.
There are three core entities in Pigsty’s MINIO module:
- Cluster: An autonomous object storage service unit and the top-level namespace for other entities.
- Instance: One Silo server process on a node, managing local disks.
- Node: An implicitly declared hardware resource that runs Linux and Systemd.
Silo also retains the Storage Pool concept for expansion.
Deployment Modes
Silo supports Pigsty’s three inventory deployment modes:
| Mode | Code | Description | Use Case |
|---|---|---|---|
| Single-Node Single-Drive | SNSD | Single node, single data directory or disk | Dev, test, demo |
| Single-Node Multi-Drive | SNMD | Single node, multiple disks, typically 4+ | Resource-constrained small deployments |
| Multi-Node Multi-Drive | MNMD | Multiple nodes, multiple disks per node | Production recommended |
For a quick SNSD experiment, you can use a regular directory. For multiple drives, use real disk mount points. Otherwise, Silo refuses to start.
Examples
This example explicitly selects Silo, the current default backend, and defines a four-node cluster with multiple drives:
The configuration defines four Silo nodes with four disks each. Instance identifiers retain MINIO compatibility names:
| Cluster | Description |
|---|---|
minio | Silo 4-node HA cluster |
| Instance | Description |
minio-1 | Object-storage instance #1, managing 4 disks |
minio-2 | Object-storage instance #2, managing 4 disks |
minio-3 | Object-storage instance #3, managing 4 disks |
minio-4 | Object-storage instance #4, managing 4 disks |
| Node | Description |
10.10.10.10 | Node #1, hosts minio-1 instance |
10.10.10.11 | Node #2, hosts minio-2 instance |
10.10.10.12 | Node #3, hosts minio-3 instance |
10.10.10.13 | Node #4, hosts minio-4 instance |
Identity Parameters
The MINIO parameter group assigns deterministic identities to MINIO entities. Two parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
minio_cluster | string | Cluster | Object-storage cluster name, required | Valid non-empty name, no default |
minio_seq | int | Instance | Object-storage instance number, required | Natural number, starting from 1, unique within cluster |
Set the cluster name at cluster level and the instance number at instance level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ minio_cluster }}-{{ minio_seq }} | minio-1, minio-2, minio-3, minio-4 |
MINIO uses the existing hostname or IP address as the host node identity. It does not assign another identity. minio_node generates internal Silo node names for cluster discovery in /etc/hosts. These names do not identify the host node.
Roles find members throughout the inventory by minio_cluster. The Ansible group name can differ from the cluster name. The retained backend selector minio_type currently must be silo.
Core Configuration Parameters
These parameters are also critical for Silo cluster configuration:
| Parameter | Type | Description |
|---|---|---|
minio_type | enum | Retained selector; currently only silo |
minio_data | path | Data directory, use {x...y} for multi-drive |
minio_node | string | Node name pattern for multi-node deployment |
minio_domain | string | Service domain, defaults to sss.pigsty |
These parameters determine minio_volumes, which the role writes to Silo’s MINIO_VOLUMES:
- SNSD: Direct
minio_datavalue, e.g.,/data/minio - SNMD: Expanded
minio_datadirectories, e.g.,/data{1...4} - MNMD: Combined
minio_nodeandminio_data, e.g.,https://minio-{1...4}.pigsty:9000/data{1...4}
Ports & Services
Each object-storage instance listens on the following ports:
| Port | Parameter | Purpose |
|---|---|---|
| 9000 | minio_port | S3 API service port |
| 9001 | minio_admin_port | Web admin console port |
MINIO enables HTTPS by default through minio_https. For the default pgBackRest S3 repository configuration, keep HTTPS enabled and install the Pigsty CA correctly.
Clients can reach a multi-node Silo cluster through any member. For a stable entry point, use a load balancer such as HAProxy with a VIP.
Resource Provisioning
After deployment, Pigsty creates these Silo resources. minio_provision controls this step:
Default Buckets (defined by minio_buckets):
| Bucket | Purpose |
|---|---|
pgsql | PostgreSQL pgBackREST backup storage |
meta | Metadata storage, versioning enabled |
data | General data storage |
Default Users (defined by minio_users):
| User | Default Password | Policy | Purpose |
|---|---|---|---|
pgbackrest | S3User.Backup | pgsql | PostgreSQL backup dedicated user |
s3user_meta | S3User.Meta | meta | Access meta bucket |
s3user_data | S3User.Data | data | Access data bucket |
These public default credentials are only for demonstrations and local development. Replace them before production deployment.
pgbackrest serves PostgreSQL cluster backups. The reserved users s3user_meta and s3user_data are not actively used.
Monitoring Label System
Pigsty uses these identity parameters to identify object storage entities. This example shows a Silo availability series:
cls, ins, and ip identify the cluster name, instance name, and node IP. For monitoring compatibility, job="minio" remains unchanged. The current backend label is flavor=silo. See the metric list for details.
2.5 - E-R Model of Redis Cluster
The Redis module organizes production Redis into clusters. A cluster is a logical entity with Redis instances on one or more nodes.
Each cluster is an autonomous, high-performance cache or storage unit with at least one Redis instance. It exposes services through ports.
There are three core entities in Pigsty’s Redis module:
- Cluster: An autonomous Redis service unit and the top-level namespace for other entities.
- Instance: One Redis server process using a specific port on a node.
- Node: An implicitly declared hardware resource that runs Linux and Systemd. It can host multiple Redis instances.
Redis usually runs multiple instances per node, unlike PostgreSQL. This uses multiple CPU cores on a physical server or VM. Nodes and instances therefore have a 1:N relationship. For production, Redis instances with more than 12 GB of memory are generally discouraged.
Operating Modes
redis_mode selects one of three Redis modes:
| Mode | Code | Description | HA Mechanism |
|---|---|---|---|
| Standalone | standalone | Classic master-replica, default mode | Requires Sentinel |
| Sentinel | sentinel | HA monitoring and auto-failover for standalone | Multi-node quorum |
| Native Cluster | cluster | Redis native distributed cluster, no sentinel needed | Built-in auto-failover |
- Standalone: The default mode. Set replication with
replica_of. HA requires a separate Sentinel cluster. - Sentinel: Monitor standalone clusters and provide automatic failover. Sentinel stores no business data. Multiple nodes provide HA for Sentinel itself.
- Native Cluster: Automatically shard data across multiple primaries. Each primary can have multiple replicas. Built-in HA removes the need for Sentinel.
Examples
The following examples show each mode.
Standalone Cluster
Classic master-replica on a single node:
| Cluster | Description |
|---|---|
redis-ms | Redis standalone cluster |
| Node | Description |
redis-ms-1 | 10.10.10.10 Node #1, hosts 2 instances |
| Instance | Description |
redis-ms-1-6379 | Primary instance, listening on port 6379 |
redis-ms-1-6380 | Replica instance, port 6380, replicates from 6379 |
Sentinel Cluster
This example puts three Sentinel instances on one node. redis_sentinel_monitor specifies the standalone clusters they monitor:
Native Cluster
This native distributed cluster has two nodes and six instances: the minimum specification of three primaries and three replicas.
This creates a 3 primary 3 replica native Redis cluster.
| Cluster | Description |
|---|---|
redis-test | Redis native cluster (3P3R) |
| Instance | Description |
redis-test-1-6379 | Instance on node 1, port 6379 |
redis-test-1-6380 | Instance on node 1, port 6380 |
redis-test-1-6381 | Instance on node 1, port 6381 |
redis-test-2-6379 | Instance on node 2, port 6379 |
redis-test-2-6380 | Instance on node 2, port 6380 |
redis-test-2-6381 | Instance on node 2, port 6381 |
| Node | Description |
redis-test-1 | 10.10.10.12 Node #1, hosts 3 instances |
redis-test-2 | 10.10.10.13 Node #2, hosts 3 instances |
Identity Parameters
The REDIS parameter group assigns deterministic identities to Redis entities. Three parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
redis_cluster | string | Cluster | Redis cluster name, required | Valid DNS name, regex [a-z][a-z0-9-]* |
redis_node | int | Node | Redis node number, required | Natural number, starting from 1, unique within cluster |
redis_instances | dict | Node | Redis instance definition, required | JSON object, key is port, value is instance config |
Set the cluster name at cluster level. Set the node number and instance definitions at node level. Pigsty generates these unique identifiers:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ redis_cluster }}-{{ redis_node }}-{{ port }} | redis-ms-1-6379, redis-ms-1-6380 |
Redis uses the existing hostname or IP address as the host node identity. It does not assign another identity. redis_node names instances, not host nodes.
Instance Definition
redis_instances is a JSON object. Each key is a port number; its value is the instance configuration:
Each Redis instance must use a unique port on its node. Avoid reserved ports below 1024 and conflicts with Pigsty ports. In standalone mode, replica_of defines replication. Use format '<ip> <port>' to specify the upstream primary address and port.
Each Redis node also runs Redis Exporter to collect metrics from all local instances:
| Port | Parameter | Purpose |
|---|---|---|
| 9121 | redis_exporter_port | Redis Exporter port |
The Redis deployment model has these limits:
- Node Exclusive: A node can belong to only one Redis cluster at a time.
- Port Unique: Instances on the same node must use different ports.
- Password Shared: Instances on the same node must share a password because of a redis_exporter limitation.
- Manual HA: Standalone clusters require additional Sentinel configuration for automatic failover.
Monitoring Label System
The built-in monitoring system uses these identity parameters to identify Redis entities.
The labels cls, ins, and ip identify the cluster name, instance name, and node IP. They accompany job in all Redis metrics collected by VictoriaMetrics. The Redis metrics job is always redis.
3 - Infra as Code
Pigsty uses IaC and GitOps. Describe the environment in a declarative inventory. Apply it with idempotent playbooks.
Declare the target state with parameters. Playbooks can repeatedly adjust nodes to that state. This resembles Kubernetes CRDs and Operators, implemented through Ansible on physical servers and VMs.
Pigsty was designed to manage large PostgreSQL deployments. Its target was to reproduce more than 100 database clusters, PG/Redis services, and monitoring on prepared servers within ten minutes. Manual GUI operations cannot complete that work in the available time. CLI-based IaC provides precise, efficient control.
pigsty.yml describes the deployment state. Production, staging, test, and development environments use the same deployment logic. Their inventories define the differences.
Store this configuration in Git for version history and auditing. You can also store it in PostgreSQL CMDB tables as infrastructure data. Integrate either method with existing workflows.
IaC supports enterprise operators, individual developers, and smaller organizations. Default values avoid the need to understand every parameter. Start a single-node database with zero configuration. Add two IP addresses for an enterprise HA PostgreSQL cluster.
Declare Modules
This default example installs INFRA, NODE, ETCD, and PGSQL on 10.10.10.10.
Run these playbooks to install the modules:
Declare Clusters
Install PGSQL on multiple nodes to declare a PostgreSQL cluster as one service unit:
For a three-node HA cluster using streaming replication, add this definition to all.children in pigsty.yml. The three nodes must already be managed by Pigsty.
After defining the cluster, create it with playbooks:
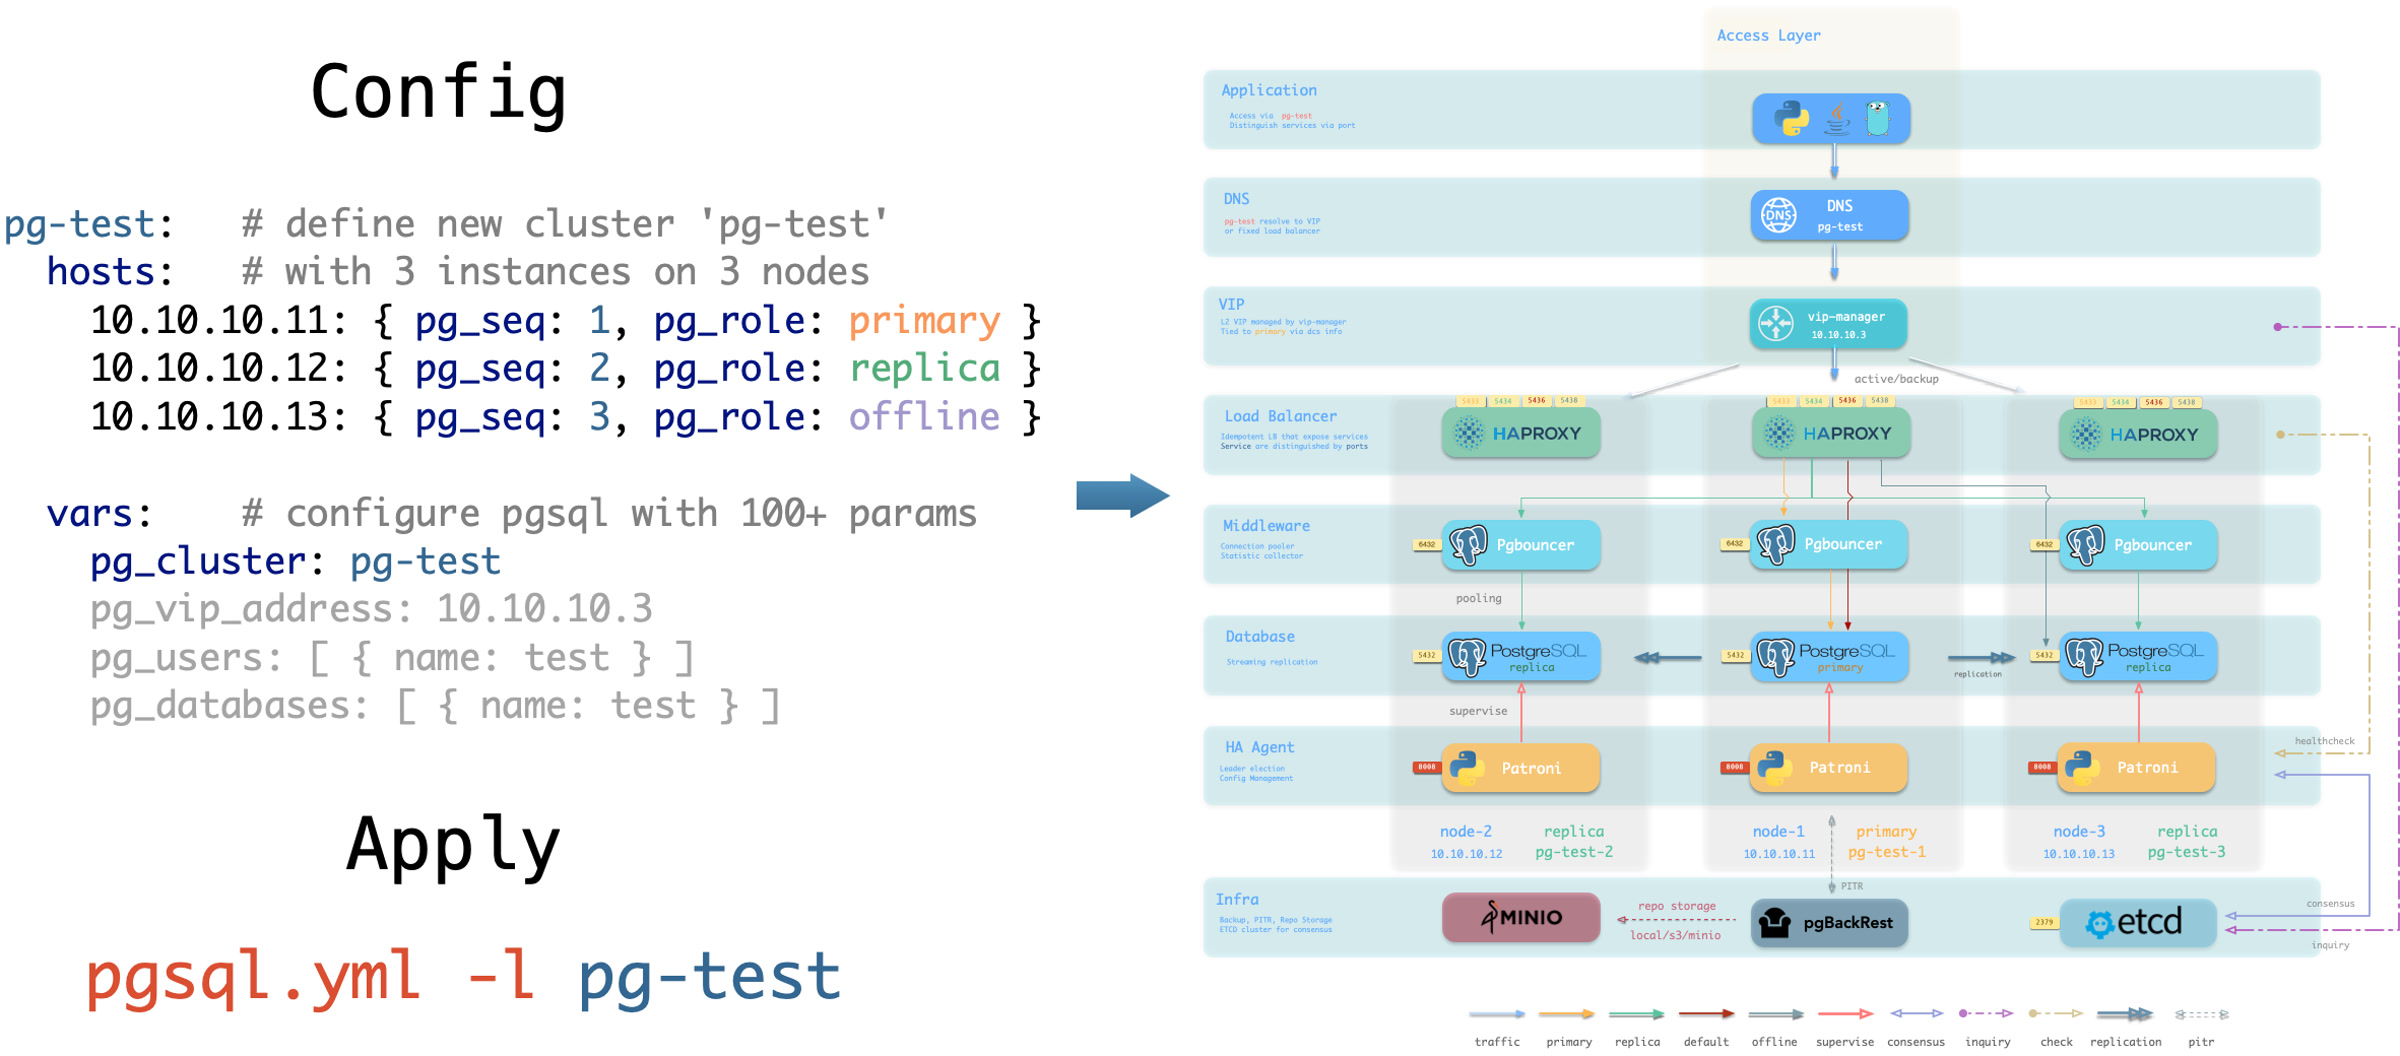
Instance roles include primary, replica, offline, delayed, and synchronous standby. Cluster types include standby, Citus, Redis, MINIO (Silo), and Etcd.
Customize Cluster Content
Declare databases, users, services, and HBA rules inside each cluster. This example customizes the default pg-meta single-node cluster:
It declares six business databases and seven business users. It adds a standby service for reads without replication delay, additional pg_hba rules, a primary L2 VIP, and a custom backup strategy.
Declare Access Control
Declarative configuration also controls access permissions. This example customizes security for pg-meta:
The three-node crit.yml template prioritizes consistency and zero-loss failover. It enables L2 VIP and restricts database and pool listeners to loopback, internal, and VIP addresses. It enables TLS for the Patroni API and PgBouncer. HBA rules require SSL for database access. $libdir/passwordcheck in pg_libs enforces the password policy.
A separate pg-meta-delay cluster follows pg-meta with a one-hour delay for emergency recovery after data deletion.
Citus Distributed Cluster
This configuration declares a four-node Citus cluster:
Redis Clusters
These examples declare Redis primary-replica, sentinel, and Redis Cluster deployments:
ETCD Cluster
This configuration declares a three-node Etcd cluster:
MINIO (Silo) Cluster
This configuration declares a three-node Silo cluster. Inventory groups and parameters retain MINIO compatibility names:
3.1 - Inventory
Each Pigsty deployment has an inventory that describes the infrastructure and database clusters.
Configuration File
By default, Pigsty uses Ansible YAML configuration format. The inventory is a single file, pigsty.yml.
Edit this file to customize the deployment. Alternatively, use the configure wizard to generate it automatically.
Configuration Structure
The inventory uses Ansible YAML configuration format. It contains global parameters in all.vars and groups in all.children.
Define clusters in all.children. Define infrastructure settings in all.vars, as this example shows:
Cluster Definition
Each Ansible group can represent a cluster. Examples include node, PostgreSQL, Redis, Etcd, and Silo clusters.
A cluster definition contains members (hosts) and parameters (vars). Define members in <cls>.hosts. Set configuration parameters in <cls>.vars. This example defines a three-node HA PostgreSQL cluster:
Cluster vars override global parameters. Instance vars override both cluster and global parameters.
Splitting Configuration
For a large deployment, you can split the inventory into multiple files. This can also help organize and maintain configuration.
Put cluster members in hosts.yml. Put cluster configuration parameters in the corresponding files under group_vars.
Switching Configuration
When you run a playbook, use -i to temporarily select a different inventory.
Ansible also accepts local yaml|ini configuration files, a CMDB, or other dynamic configuration scripts.
The ansible.cfg file in the Pigsty home directory sets the default inventory to pigsty.yml in that directory. You can change this setting.
You can store the inventory in a CMDB metabase to integrate it with existing systems.
3.2 - Configure
The configure configuration wizard generates pigsty.yml for your current environment.
This script is optional. If you know how to configure Pigsty, edit pigsty.yml directly and skip the wizard.
Quick Start
Enter the Pigsty source directory and run ./configure to start the wizard. Without arguments, it uses the meta single-node template:
The command starts with the selected template. It detects the current node IP address and region, then generates pigsty.yml for that environment.
demo/configure.cast — /demo/configure.cast
Features
The configure script makes these adjustments from your environment and input. By default, it generates pigsty.yml in the Pigsty directory.
- Detect the current node IP address. If the node has multiple addresses, ask you to select a primary IP address as its identity.
- Replace
10.10.10.10in the template with this address. Setadmin_ipto the same value. - Detect the region. Set
regiontodefaultfor global software repositories orchinafor Chinese mirrors. - For instances with fewer than four vCPUs, use the
tinytemplate fornode_tuneandpg_conf. This reduces resource use. - With
-v, changepg_versionandpg18-*package-group aliases to the specified major version. Exclude the fixed-kernel templatesmssql,polar, andpg19. - With
-g, replace recognized default passwords with strong random passwords. This is strongly recommended. Review other values against the Default Credentials Checklist. - For PG major versions ≥ 17, prefer the built-in
C.UTF-8locale, or the OS-supportedC.UTF-8. - Check that the core deployment dependency
ansibleis available. - Check that the deployment target accepts SSH connections and can run commands with sudo. Use
-sto skip these checks.
Usage Examples
Command Arguments
Argument Details
| Argument | Description |
|---|---|
-c, --conf | Generate config from conf/<template>.yml, supports subdirectories like ha/full |
-i, --ip | Replace placeholder 10.10.10.10 in config template with specified IP |
-v, --version | Specify PostgreSQL major version (14-19); PG19 is Beta, so prefer the dedicated pg19 template |
-r, --region | Set software repo mirror region: default, china (Chinese mirrors), europe (European) |
-o, --output | Output path, default pigsty.yml; relative paths use Pigsty home, absolute paths are used as given |
-s, --skip | Skip IP probing, target SSH/Sudo checks, and effective IP replacement; keep 10.10.10.10 |
-x, --proxy | Write current environment proxy variables (HTTP_PROXY, HTTPS_PROXY, ALL_PROXY, NO_PROXY) to config |
-n, --non-interactive | Non-interactive mode; a single/demo IP is auto-selected, while ambiguous multi-IP hosts require -i |
-p, --port | SSH port used by readiness checks only; it does not write ansible_port into the generated config |
-g, --generate | Generate random values for passwords in config file, improving security (strongly recommended) |
Execution Flow
The configure script detects and configures settings in this order:
Automatic Behaviors
Region Detection
The script tests network access to detect mainland China behind the GFW:
- If Google is reachable, use
region: defaultrepositories. - If Google is unreachable but
https://pigsty.ccis reachable, setregion: china. - If neither endpoint is reachable, use
region: defaultand warn that internet access is unavailable. - To set the region manually, use
-r.
IP Address Handling
The script selects the primary IP address in this order:
- Command line argument: Use the address specified with
-i. - Single IP detection: If the node has only one IP address, select it automatically.
- Demo IP detection: If
10.10.10.10exists, select it automatically for the sandbox environment. - Interactive input: If multiple addresses remain, ask you to select or enter one.
Low-End Hardware Optimization
If the script detects fewer than four CPU cores (1–3), it changes these settings:
These settings support operation on virtual machines with limited resources.
Locale Settings
The script enables C.UTF-8 as the default locale if either condition applies:
- PostgreSQL version is ≥ 17, with built-in Locale Provider support.
- The operating system supports the
C.UTF-8orC.utf8locale.
China Region Special Handling
For region china, the script automatically enables:
docker_registry_mirrorsfor faster Docker downloads through mirrors.PIP_MIRROR_URLfor faster Python downloads through mirrors.
Password Generation
With -g, the script generates a random 24-character string for each of these passwords:
| Password Parameter | Description |
|---|---|
grafana_admin_password | Grafana admin password |
pg_admin_password | PostgreSQL admin password |
pg_monitor_password | PostgreSQL monitor user password |
pg_replication_password | PostgreSQL replication user password |
patroni_password | Patroni API password |
haproxy_admin_password | HAProxy admin password |
minio_secret_key | Silo Root Secret |
etcd_root_password | ETCD Root password |
It also replaces the following placeholder passwords:
DBUser.Meta→ random passwordDBUser.Viewer→ random passwordS3User.Backup→ random passwordS3User.Meta→ random passwordS3User.Data→ random passwordDBUser.Supa→ random passwordVibe.Coding→ random password
Configuration Templates
The script reads templates from conf/. Set -c to a relative path without the .yml suffix, such as ha/full or app/immich.
Core Templates
| Template | Description |
|---|---|
meta | Default template: Single-node installation with INFRA + NODE + ETCD + PGSQL |
rich | Feature-rich version: Includes almost all extensions, Silo, local repo |
slim | Minimal version: PostgreSQL + ETCD only, no monitoring infrastructure |
fat | Complete version: rich base with more extensions installed |
pgsql | Pure PostgreSQL template |
pg19 | Single-node PostgreSQL 19 Beta evaluation template |
infra | Pure infrastructure template |
HA Templates (ha/)
| Template | Description |
|---|---|
ha/dual | 2-node HA cluster |
ha/trio | 3-node HA cluster |
ha/full | 4-node complete sandbox environment |
ha/safe | Security-hardened HA configuration |
ha/octo | Compact 8-node HA simulation |
ha/simu | 20-node production simulation environment |
ha/citus | 13-node Citus distributed cluster |
Application Templates
| Template | Description |
|---|---|
supabase | Supabase self-hosted configuration |
app/dify | Dify AI platform configuration |
app/odoo | Odoo ERP configuration |
app/electric | Electric sync engine configuration |
app/insforge | Insforge backend platform configuration |
app/hindsight | Hindsight application configuration |
app/teable | Teable table database configuration |
app/mattermost | Mattermost collaboration platform configuration |
app/maybe | Maybe finance application configuration |
app/registry | Docker Registry configuration |
app/immich | Immich photo and video management |
app/jumpserver | JumpServer bastion host |
Special Kernel Templates
| Template | Description |
|---|---|
ivory | IvorySQL: Oracle-compatible PostgreSQL |
mssql | Babelfish: SQL Server-compatible PostgreSQL |
polar | PolarDB: Alibaba Cloud open-source distributed PostgreSQL |
ha/citus | Citus: Distributed PostgreSQL HA cluster |
mysql | OpenHalo: MySQL protocol-compatible PostgreSQL |
pgtde | Percona PostgreSQL Server: transparent encryption |
oriole | OrioleDB: Next-generation storage engine |
agens | AgensGraph: graph database kernel |
pgedge | pgEdge: distributed PostgreSQL kernel |
mongo | MongoDB-compatible stack template |
Demo and Build Templates
| Template | Description |
|---|---|
vibe | Vibe Coding development environment |
docker | Run Pigsty inside a Docker container |
demo/bare | Minimal readable single-node example |
demo/el | Full parameter example for EL distributions |
demo/debian | Full parameter example for Debian/Ubuntu |
demo/demo | Multi-module demo environment |
demo/kernel | Ten-node database-kernel matrix |
demo/redis | Redis replica, Sentinel, and native Cluster demo |
demo/minio | Multi-node, multi-drive Silo demo (source default) |
demo/kafka | Kafka KRaft development and secure-cluster demo |
demo/mysql | Native MySQL 8.4 pilot demo |
demo/remote | Remote PostgreSQL/RDS monitoring example |
demo/saas | Legacy single-node SaaS component bundle |
demo/wool | Small cloud-instance example for China |
build/oss | Cross-distribution open-source package build env |
build/dev | Three-node development and build environment |
Output Example
Environment Variables
The script supports the following environment variables:
| Environment Variable | Description | Default |
|---|---|---|
PIGSTY_HOME | Pigsty installation directory | ~/pigsty |
METADB_URL | Metabase connection URL | service=meta |
HTTP_PROXY | HTTP proxy | - |
HTTPS_PROXY | HTTPS proxy | - |
ALL_PROXY | Universal proxy | - |
NO_PROXY | Proxy whitelist | Built-in default |
Notes
Passwordless access: Before you run
configure, the current user must have passwordless sudo and passwordless SSH access to localhost. Thebootstrapscript can configure both.IP address selection: Select an internal IP as the primary address. Do not select a public IP or
127.0.0.1.Password security: In production, always change default passwords. Use
-gto randomize recognized credentials. Review the Default Credentials Checklist for remaining values.Configuration review: After the script completes, review the generated
pigsty.yml. Check that it meets your requirements.Multiple executions: You can run
configureagain to regenerate configuration. Each run overwrites the existingpigsty.yml.macOS limitations: On macOS, the script skips some Linux checks and uses placeholder IP
10.10.10.10. macOS can serve only as an administration node.
FAQ
How to use a custom configuration template?
Place your configuration file in the conf/ directory, then specify it with the -c argument:
How to generate different configurations for multiple clusters?
Use the -o argument to specify different output files:
Then specify the configuration file when running playbooks:
How to handle multiple IPs in non-interactive mode?
You must explicitly specify the IP address using the -i argument:
How to keep the placeholder IP in the template?
Use the -s argument to skip IP replacement:
Related Documentation
- Inventory: Understand the Ansible inventory structure
- Parameters: Understand Pigsty parameter hierarchy and priority
- Templates: View all available configuration templates
- Installation: Understand the complete installation process
- Metabase: Use PostgreSQL as a dynamic configuration source
3.3 - Parameters
Use inventory parameters to customize infrastructure settings and database configuration.
Parameter List
The current source and reference pages list 373 public parameters across 10 official modules. See Reference - Parameter List for the complete list. The native MySQL 8.4 pilot module has 13 additional public parameters. They are listed separately and excluded from this total.
| Module | Groups | Params | Description |
|---|---|---|---|
| PGSQL | 9 | 124 | PostgreSQL high-availability cluster configuration |
| INFRA | 10 | 73 | Software repositories and Victoria observability infrastructure |
| NODE | 11 | 73 | Node initialization, system tuning, and operations baseline |
| ETCD | 2 | 13 | ETCD cluster and removal protection parameters |
| MINIO | 2 | 22 | Silo deployment, observability, and removal parameters |
| REDIS | 2 | 22 | Redis/Valkey deployment and removal parameters |
| DOCKER | 1 | 8 | Docker engine parameters |
| JUICE | 1 | 2 | JuiceFS instance and cache parameters |
| VIBE | 1 | 18 | Code/Jupyter/Node.js/Claude/Codex configuration |
| KAFKA | 2 | 18 | Kafka deployment and removal-protection parameters |
Parameter Form
Parameters are key-value pairs that describe entities. A key is a string. A value can be a boolean, string, number, array, or object.
Parameter Priority
Set parameters at these levels, listed from highest to lowest priority:
| Level | Location | Description | Priority |
|---|---|---|---|
| CLI | -e command line argument | Passed via command line | Highest (5) |
| Host/Instance | <group>.hosts.<host> | Parameters specific to a single host | Higher (4) |
| Group/Cluster | <group>.vars | Parameters shared by hosts in group/cluster | Medium (3) |
| Global | all.vars | Parameters shared by all hosts | Lower (2) |
| Default | <roles>/default/main.yml | Role implementation defaults | Lowest (1) |
These examples show parameter priority:
- Set
-e grafana_clean=trueon the playbook command line to erase Grafana data. - Set host variable
pg_roleto override the PostgreSQL instance role. - Set group variable
pg_clusterto override the PostgreSQL cluster name. - Set global variable
node_ntp_serversto specify NTP servers. - If you do not set
pg_version, Pigsty uses thepgsqlrole default,18.
Except for identity parameters, all parameters have defaults. You do not need to set them explicitly.
Identity Parameters
Identity parameters identify entities. They have no defaults and must be set explicitly, with the exception below.
| Module | Identity Parameters |
|---|---|
PGSQL | pg_cluster, pg_seq, pg_role, … |
NODE | nodename, node_cluster |
ETCD | etcd_cluster, etcd_seq |
MINIO | minio_cluster, minio_seq |
REDIS | redis_cluster, redis_node, redis_instances |
INFRA | infra_seq |
etcd_cluster is an exception. It defaults to etcd. Set minio_cluster explicitly in each object storage cluster’s variables. It no longer has a default. Do not set it in all.vars: this marks every host as a MINIO module member.
3.4 - Conf Templates
The inventory defines the deployment through declarative configuration. Customize its pigsty.yml file for your requirements.
New users can start with ready-to-use templates for common deployment scenarios.
Each template is a predefined pigsty.yml file with defaults for a specific scenario.
Select a template, then change it to meet your requirements.
Using Templates
The optional configure wizard generates an inventory from your environment and input, with suitable defaults.
Use ./configure -c <conf> to select a template. <conf> is relative to conf; the .yml suffix is optional.
If no template is specified, Pigsty defaults to the meta.yml single-node configuration template.
Template List
Main Templates
Use these templates to install Pigsty on one server:
| Template | Description |
|---|---|
meta.yml | Default template, single-node PostgreSQL online installation |
rich.yml | Feature-rich template with local repo, Silo, and more examples |
slim.yml | Minimal template, PostgreSQL only without monitoring and infrastructure |
Database Kernel Templates
Templates for various database management systems and kernels:
| Template | Description |
|---|---|
pgsql.yml | Native PostgreSQL kernel, basic features (14~18) |
pg19.yml | PostgreSQL 19 Beta trial template |
mssql.yml | Babelfish kernel, SQL Server protocol compatible (17/18) |
polar.yml | PolarDB PG kernel, Aurora/RAC style (17) |
ivory.yml | IvorySQL kernel, Oracle syntax compatible (18) |
mysql.yml | OpenHalo kernel, MySQL compatible (14) |
pgtde.yml | Percona PostgreSQL Server transparent encryption (18) |
oriole.yml | OrioleDB kernel, OLTP enhanced (16~18) |
agens.yml | AgensGraph graph database kernel (17) |
pgedge.yml | pgEdge distributed database kernel (15~18, default 18) |
supabase.yml | Supabase self-hosted configuration (15~18) |
You can add more nodes later or use HA templates to plan your cluster from the start.
HA Templates
Use these templates for a deployment with multiple nodes and high availability:
| Template | Description |
|---|---|
dual.yml | 2-node semi-HA deployment |
trio.yml | 3-node standard HA deployment |
full.yml | 4-node standard deployment |
safe.yml | 4-node security-enhanced deployment with delayed replica |
octo.yml | Compact 8-node HA simulation |
simu.yml | 20-node production environment simulation |
ha/citus.yml | Citus distributed HA PostgreSQL (14~18) |
Application Templates
Use these templates to run applications with Docker:
| Template | Description |
|---|---|
supabase.yml | Start single-node Supabase |
odoo.yml | Start Odoo ERP system |
dify.yml | Start Dify AI workflow system |
electric.yml | Start Electric sync engine |
insforge.yml | Start Insforge backend platform |
hindsight.yml | Start Hindsight application |
mattermost.yml | Start Mattermost collaboration platform |
teable.yml | Start Teable spreadsheet database |
maybe.yml | Start Maybe finance app |
registry.yml | Start Docker Registry |
Demo Templates
Pigsty also provides these demonstration templates:
| Template | Description |
|---|---|
el.yml | Full-parameter config file for EL 8/9 systems |
debian.yml | Full-parameter config file for Debian/Ubuntu systems |
remote.yml | Example config for monitoring remote PostgreSQL clusters or RDS |
redis.yml | Redis cluster example configuration |
minio.yml | 4-node multi-drive Silo cluster example (source default) |
kafka.yml | Kafka dynamic KRaft example with a single-node dev cluster and a three-node secure cluster |
mysql.yml | Native MySQL 8.4 single-node/three-node pilot example; distinct from OpenHalo conf/mysql.yml |
demo.yml | Configuration file for Pigsty public demo site |
fat.yml | Single-node config with local repo and full feature set |
infra.yml | Deploy only the infrastructure modules |
vibe.yml | Vibe Coding / AI application development template |
mongo.yml | FerretDB / MongoDB-compatible example |
docker.yml | Docker application host template |
Build Templates
Use these templates for development and testing:
| Template | Description |
|---|---|
build/oss.yml | Open source build config for EL 9/10, Debian 12/13, Ubuntu 22.04/24.04/26.04 |
build/dev.yml | Development and testing build config |
3.5 - Use CMDB as Config Inventory
Use a PostgreSQL metabase as a dynamic configuration source instead of static YAML files.
Overview
A CMDB (Configuration Management Database) stores configuration in database tables.
By default, Pigsty uses static pigsty.yml as the Ansible inventory.
A static file is simple. Larger deployments can need finer control, concurrent editing, and external integration beyond one file’s practical limits.
| Feature | Static YAML File | CMDB Metabase |
|---|---|---|
| Querying | Manual search/grep | SQL queries with any conditions, aggregation analysis |
| Versioning | Depends on Git or manual backup | Database transactions, audit logs, time-travel snapshots |
| Access Control | File system permissions, coarse-grained | PostgreSQL fine-grained access control |
| Concurrent Editing | Requires file locking or merge conflicts | Database transactions naturally support concurrency |
| External Integration | Requires YAML parsing | Standard SQL interface, easy integration with any language |
| Scalability | Difficult to maintain when file becomes too large | Scales to physical limits |
| Dynamic Generation | Static file, changes require manual application | Immediate effect, real-time configuration changes |
The sample pg-meta.meta database baseline defines the CMDB schema.
How It Works
CMDB replaces the static inventory with an executable script that returns JSON, as Ansible supports. Enabling CMDB creates inventory.sh:
Whenever Ansible reads the inventory, this script queries pigsty.inventory in PostgreSQL and returns JSON.
The architecture is:
flowchart LR
    conf["bin/inventory_conf"]
    tocmdb["bin/inventory_cmdb"]
    load["bin/inventory_load"]
    ansible["🚀 Ansible"]

    subgraph static["📄 Static Config Mode"]
        yml[("pigsty.yml")]
    end

    subgraph dynamic["🗄️ CMDB Dynamic Mode"]
        sh["inventory.sh"]
        cmdb[("PostgreSQL CMDB")]
    end

    conf -->|"switch"| yml
    yml -->|"load config"| load
    load -->|"write"| cmdb
    tocmdb -->|"switch"| sh
    sh --> cmdb

    yml --> ansible
    cmdb --> ansible
Data Model
The CMDB database schema is defined in files/cmdb.sql, with all objects in the pigsty schema.
Core Tables
| Table | Description | Primary Key |
|---|---|---|
pigsty.group | Cluster/group definitions, corresponds to Ansible groups | cls |
pigsty.host | Host definitions, belongs to a group | (cls, ip) |
pigsty.global_var | Global variables, corresponds to all.vars | key |
pigsty.group_var | Group variables, corresponds to all.children.<cls>.vars | (cls, key) |
pigsty.host_var | Host variables, host-level variables | (cls, ip, key) |
pigsty.default_var | Default variable definitions, stores parameter metadata | key |
pigsty.job | Job records table, records executed tasks | id |
Table Structure Details
Cluster Table pigsty.group
Host Table pigsty.host
Global Variables Table pigsty.global_var
Group Variables Table pigsty.group_var
Host Variables Table pigsty.host_var
Core Views
These views expose configuration data:
| View | Description |
|---|---|
pigsty.inventory | Core view: Generates Ansible dynamic inventory JSON |
pigsty.raw_config | Raw configuration in JSON format |
pigsty.global_config | Global config view, merges defaults and global vars |
pigsty.group_config | Group config view, includes host list and group vars |
pigsty.host_config | Host config view, merges group and host-level vars |
pigsty.pg_cluster | PostgreSQL cluster view |
pigsty.pg_instance | PostgreSQL instance view |
pigsty.pg_database | PostgreSQL database definition view |
pigsty.pg_users | PostgreSQL user definition view |
pigsty.pg_service | PostgreSQL service definition view |
pigsty.pg_hba | PostgreSQL HBA rules view |
pigsty.pg_remote | Remote PostgreSQL instance view |
pigsty.inventory converts database configuration to Ansible inventory JSON:
Utility Scripts
Use these three scripts to manage the CMDB:
| Script | Function |
|---|---|
bin/inventory_load | Load YAML configuration file into PostgreSQL database |
bin/inventory_cmdb | Switch configuration source to CMDB (dynamic inventory script) |
bin/inventory_conf | Switch configuration source to static config file pigsty.yml |
inventory_load
Parse a YAML configuration file and import it into the CMDB:
The script performs these operations:
- Clears existing data in the
pigstyschema - Parses the YAML configuration file
- Writes global variables to the
global_vartable - Writes cluster definitions to the
grouptable - Writes cluster variables to the
group_vartable - Writes host definitions to the
hosttable - Writes host variables to the
host_vartable
Environment Variables
PIGSTY_HOME: Pigsty installation directory, defaults to~/pigstyMETADB_URL: Database connection URL, defaults toservice=meta
inventory_cmdb
Switch Ansible to use CMDB as the configuration source:
The script performs these operations:
- Creates dynamic inventory script
${PIGSTY_HOME}/inventory.sh - Modifies
ansible.cfgto setinventorytoinventory.sh
The generated inventory.sh contains:
inventory_conf
Switch back to a static YAML configuration file:
The script modifies ansible.cfg to set inventory back to pigsty.yml.
Usage Workflow
First-time CMDB Setup
- Initialize the CMDB schema. Pigsty installation usually does this automatically:
- Load configuration into the database:
- Switch to CMDB mode:
- Verify configuration:
Query Configuration
After you enable CMDB, use SQL to query the configuration:
Modify Configuration
Use SQL to change the configuration directly:
Configuration changes are immediately available. You do not need to reload or restart a service.
Switch Back to Static Configuration
Switch back to a static configuration file:
Advanced Usage
Export Configuration
Export CMDB configuration to YAML format:
Or use the ansible-inventory command:
Configuration Auditing
Track configuration changes using the mtime field:
Integration with External Systems
CMDB uses standard PostgreSQL. You can integrate it with these systems:
- Web Management Interface: Expose configuration data through a REST API, such as PostgREST.
- CI/CD Pipelines: Read and write database data directly from deployment scripts.
- Monitoring & Alerting: Generate monitoring rules from configuration data.
- ITSM Systems: Synchronize data with enterprise CMDB systems.
Considerations
Data Consistency: After you change configuration, run the corresponding Ansible playbooks again to apply it to the environment.
Backup: CMDB configuration data is critical. Back it up regularly.
Permissions: Set appropriate CMDB database access permissions to prevent accidental changes.
Transactions: Make batch configuration changes in a transaction. This permits rollback if an error occurs.
Connection Pooling:
inventory.shopens a new connection each time it runs. Consider connection pooling if Ansible runs frequently.
Summary
Use CMDB for large cluster deployments, complex queries, external integration, or fine-grained access control. PostgreSQL stores the configuration and provides database functions to manage it.
| Feature | Description |
|---|---|
| Storage | PostgreSQL pigsty schema |
| Dynamic Inventory | inventory.sh script |
| Config Load | bin/inventory_load |
| Switch to CMDB | bin/inventory_cmdb |
| Switch to YAML | bin/inventory_conf |
| Core View | pigsty.inventory |
4 - High Availability
Overview
Pigsty PostgreSQL clusters include HA through Patroni, Etcd, and HAProxy.
A cluster with two or more instances gains automatic HA without extra configuration. A surviving instance can provide the complete database service. Clients can connect through any cluster node without tracking primary-replica changes.
Default norm mode targets RTO below 45 seconds. With asynchronous replication, pg_rpo=1MiB limits sampled lag for failover candidates. It does not bound actual data loss. Strict synchronous mode with crit.yml gives acknowledged transactions RPO = 0 during failover. Configure these settings for your hardware and reliability requirements.
Built-in HAProxy load balancers switch traffic automatically. Clients can use DNS, VIP, LVS, and other access methods. Failover and switchover cause brief interruptions but require no connection-string changes or application restarts. These short maintenance windows support sequential cluster maintenance and upgrades without application coordination. Automatic recovery lets staff defer hardware repairs until the next day.
Large organizations and core institutions have run Pigsty in production for extended periods. The largest deployment has 25K CPU cores and more than 220 PostgreSQL instances. Each large instance uses 64 cores, 512GB memory, and 3TB NVMe SSD storage. Over five years, this deployment maintained more than 99.999% availability despite dozens of hardware failures and other incidents.
What problems does High Availability solve?
- Improve availability in the data security C/IA model: RPO ≈ 0 and RTO < 45s.
- Perform sequential maintenance with short maintenance windows.
- Recover automatically from hardware failures without immediate staff intervention.
- Use replicas for read-only requests to reduce primary load and use available resources.
What are the costs of High Availability?
- Infrastructure: HA needs DCS, such as etcd, zk, or consul, for consensus.
- Minimum deployment: Meaningful HA requires at least three nodes.
- Resources: Each replica consumes more resources, although this is usually manageable.
- Complexity: Backup costs and operational complexity increase substantially, requiring management tools.
Limitations of High Availability
Streaming replicas receive changes in real time, including accidental or defective changes such as DROP TABLE and DELETE. HA therefore cannot recover data lost through human error or software defects. Use delayed clusters or PITR with earlier base backups and archived WAL.
| Configuration Strategy | RTO | RPO |
|---|---|---|
| Standalone + Nothing | Data permanently lost, unrecoverable | All data lost |
| Standalone + Base Backup | Depends on backup size and bandwidth (hours) | Lose data since last backup (hours to days) |
| Standalone + Base Backup + WAL Archive | Depends on backup size and bandwidth (hours) | Lose unarchived data (tens of MB) |
| Primary-Replica + Manual Failover | ~10 minutes | Lose data in replication lag (~100KB) |
| Primary-Replica + Auto Failover | Within 1 minute | Lose data in replication lag (~100KB) |
| Primary-Replica + Auto Failover + Sync Commit | Within 1 minute | No data loss |
How It Works
The HA components work together as follows:
- PostgreSQL uses standard streaming replication to build physical replicas; replicas take over when the primary fails.
- Patroni manages PostgreSQL server processes and handles high availability matters.
- Etcd provides distributed configuration storage (DCS) capability and is used for leader election after failures.
- Patroni relies on Etcd to reach cluster leader consensus and provides health check interfaces externally.
- HAProxy exposes cluster services externally and uses Patroni health check interfaces to automatically distribute traffic to healthy nodes.
- vip-manager provides an optional Layer 2 VIP, retrieves leader information from Etcd, and binds the VIP to the node where the cluster primary resides.
Primary failure triggers an election. The healthiest replica, with the highest LSN and least potential data loss, becomes primary. Read/write traffic then moves to it. From failure until promotion, writes block or fail. This write service interruption typically lasts 15–30 seconds and usually remains below 1 minute.
After a replica fails, read-only traffic moves to other replicas. If all replicas fail, the primary handles it. Queries running on the failed replica abort because their connections reset. Other available replicas immediately take over read-only service.
Patroni and Etcd detect failures together. The leader holds a lease and must renew it before its TTL expires. Default norm mode uses 30 seconds. Expiration triggers Failover and a new election.
Use Switchover to change primary without a failure. Writes experience a brief interruption before routing to the new primary. Use this for sequential server maintenance or upgrades.
4.1 - RPO Trade-offs
RPO (Recovery Point Objective) defines the maximum amount of data loss allowed when the primary fails.
Critical data, such as financial transactions, typically requires RPO = 0: no data loss.
Stricter RPO targets increase write latency and reduce throughput. Replica failure can also make the primary unavailable. Some workloads accept limited data loss for higher performance and availability.
Trade-offs
Asynchronous replicas normally lag behind the primary by about 10KB–100KB or 100µs–10ms, depending on network and throughput. At primary failure, a replica might not have received the latest data. Promotion can lose those unreplicated changes.
pg_rpo sets Patroni maximum_lag_on_failover. The default is 1048576 (1MiB). This is a sampled candidate-lag threshold. It does not set a hard bound on actual data loss.
After primary failure, Pigsty can promote a replica whose lag is within the threshold. If every replica exceeds it, Pigsty refuses [automatic failover] to avoid data loss. An operator must choose between waiting for primary recovery, which might never occur, and accepting loss through forced promotion.
Patroni does not sample primary WAL position continuously. Worst-case asynchronous loss can include WAL from the latest ttl window. On average, sampling adds roughly loop_wait/2 of WAL. Account for write rate when setting the threshold. A higher threshold allows more candidates and increases the chance of automatic failover.
Set pg_rpo = 0 to enable synchronous replication. The primary acknowledges writes only after at least one replica persists them. This removes replication lag for acknowledged writes, but increases latency and reduces throughput.
flowchart LR
    A([Primary Failure]) --> B{Synchronous<br/>Replication?}

    B -->|No| C{Lag < RPO?}
    B -->|Yes| D{Sync Replica<br/>Available?}

    C -->|Yes| E[Lossy Auto Failover<br/>Sampled candidate lag is within threshold]
    C -->|No| F[Refuse Auto Failover<br/>Wait for Primary Recovery<br/>or Manual Intervention]

    D -->|Yes| G[Lossless Auto Failover<br/>RPO = 0]
    D -->|No| H{Strict Mode?}

    H -->|No| C
    H -->|Yes| F

    style A fill:#dc3545,stroke:#b02a37,color:#fff
    style E fill:#F0AD4E,stroke:#146c43,color:#fff
    style G fill:#198754,stroke:#146c43,color:#fff
    style F fill:#BE002F,stroke:#565e64,color:#fff
Protection Modes
Pigsty offers three protection modes for different RPO requirements. They resemble Oracle Data Guard protection modes.
- Default asynchronous mode: Commit after local WAL persistence without waiting for replicas. Replica failures do not affect the primary.
- Primary failure can lose unsent or unreceived WAL. The 1MiB default sampled candidate threshold does not bound actual loss.
- Use for performance-sensitive workloads that tolerate limited failure-related data loss.
- Set
pg_rpo = 0to enablesynchronous_mode: true. - Normally, wait for at least one replica acknowledgement to prevent data loss. If all synchronous replicas fail, automatically switch to asynchronous operation.
- This balances data protection and availability. It is recommended for critical production workloads.
- Use
crit.ymlto enablesynchronous_mode: trueandsynchronous_mode_strict: true. - A transaction must persist on at least one replica before success. If all synchronous replicas fail, the primary refuses writes.
- Use for financial transactions, medical records, and other workloads with very strict integrity requirements.
| Name | Maximum Performance | Maximum Availability | Maximum Protection |
|---|---|---|---|
| Replication | Asynchronous | Synchronous | Strict Synchronous |
| Data Loss | Possible (replication lag) | Zero normally, minor when degraded | Zero |
| Write Latency | Lowest | Medium (+1 network RTT) | Medium (+1 network RTT) |
| Throughput | Highest | Reduced | Reduced |
| Replica Failure Impact | None | Auto degrade, service continues | Primary stops writes |
| RPO | Possible loss; 1MiB default candidate threshold | = 0 normally / possible loss after degradation | = 0 |
| Use Case | Typical business, performance first | Critical business, safety first | Financial core, compliance first |
| Configuration | Default config | pg_rpo = 0 | pg_conf: crit.yml |
Implementation
These modes use two Patroni parameters: synchronous_mode and synchronous_mode_strict.
synchronous_modeenables synchronous replication. When enabled,synchronous_mode_strictcontrols strict behavior.synchronous_mode_strict = falseis the default. If replicas fail, allow asynchronous operation so the primary continues service: Maximum Availability.synchronous_mode_strict = trueprevents asynchronous fallback. The primary stops writes until a synchronous replica recovers: Maximum Protection.
| Mode | synchronous_mode | synchronous_mode_strict | Replication Mode | Replica Failure Behavior |
|---|---|---|---|---|
| Max Performance | false | - | Async | No impact |
| Max Availability | true | false | Synchronous | Auto degrade to async |
| Max Protection | true | true | Strict Synchronous | Primary refuses writes |
Set pg_rpo to 0 to enable synchronous_mode and Maximum Availability. Select pg_conf = crit.yml to enable synchronous_mode_strict and Maximum Protection. You can also enable watchdog to fence a frozen primary node or Patroni process instead of degrading. This provides behavior equivalent to Oracle Maximum Protection.
You can configure Patroni directly. Consult Patroni and PostgreSQL documentation for stronger protection options:
- Configure the synchronous replica list. Add synchronous replicas for greater disaster tolerance, use quorum commit, or require acknowledgements from all replicas.
- Set
synchronous_committo'remote_apply'for consistent primary/replica reads and writes. Oracle Maximum Protection corresponds toremote_write.
Recommendations
Maximum Performance is the default asynchronous mode and suits most workloads. It accepts some failure-related loss for higher throughput and availability. pg_rpo sets sampled candidate lag. Actual worst-case loss also depends on write rate, ttl, and sampling time.
Maximum Availability suits high-integrity workloads. Acknowledged transactions are protected while a synchronous replica is healthy. If all synchronous replicas fail, the cluster can switch to asynchronous operation. At least two PostgreSQL nodes are required: one primary and one replica. Set pg_rpo to 0.
Maximum Protection suits financial transactions, medical records, and other workloads requiring strict integrity. Use at least three nodes: one primary and two replicas. With only two nodes, replica failure stops primary writes and reduces service availability. With three, the primary can continue after one replica fails.
4.2 - Failure Model
Patroni failures have 10 categories by failure target. Detection paths group them into five categories, described here.
| # | Failure Scenario | Description | Final Path |
|---|---|---|---|
| 1 | PG process crash | crash, OOM killed | Active Detection |
| 2 | PG connection refused | max_connections | Active Detection |
| 3 | PG zombie | Process alive but unresponsive | Active Detection (timeout) |
| 4 | Patroni process crash | kill -9, OOM | Passive Detection |
| 5 | Patroni zombie | Process alive but stuck | Watchdog |
| 6 | Node down | Power outage, hardware failure | Passive Detection |
| 7 | Node zombie | IO hang, CPU starvation | Watchdog |
| 8 | Primary ↔ DCS network failure | Firewall, switch failure | Network Partition |
| 9 | Storage failure | Disk failure, disk full, mount failure | Active Detection or Watchdog |
| 10 | Manual switchover | Switchover/Failover | Manual Trigger |
For RTO calculations, all failures follow two paths. This section calculates their minimum, maximum, and average recovery times.
- Passive election triggered after Patroni loses contact
- Patroni actively detects failure and triggers switchover
flowchart LR
    A([Primary Failure]) --> B{Patroni<br/>Detected?}

    B -->|PG Crash| C[Attempt Local Restart]
    B -->|Node Down| D[Wait TTL Expiration]

    C -->|Success| E([Local Recovery])
    C -->|Fail/Timeout| F[Release Leader Lock]

    D --> F
    F --> G[Replica Election]
    G --> H[Execute Promote]
    H --> I[HAProxy Detects]
    I --> J([Service Restored])

    style A fill:#dc3545,stroke:#b02a37,color:#fff
    style E fill:#198754,stroke:#146c43,color:#fff
    style J fill:#198754,stroke:#146c43,color:#fff
4.2.1 - Model of Patroni Passive Failure
infographic list-row-simple-horizontal-arrow
data

  desc Lease Expiration Stages
  items
    - label Lease Expiration
    - label Replica Detect
    - label Elect & Promote
    - label Haproxy Up
theme light
  palette antv
RTO Timeline
tooltip: { trigger: axis, axisPointer: { type: shadow }, formatter: $fn:fmt }
legend: { top: 0, itemGap: 12, data: [Lease Expiration, Replica Detection, Lock Contest & Promote, Health Check] }
grid: { left: 64, right: 24, bottom: 32, top: 40 }
xAxis: { type: value, name: Seconds, nameLocation: end, max: 160, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: true, lineStyle: { type: dashed, opacity: 0.5 } }, minorTick: { show: true, splitNumber: 5 }, minorSplitLine: { show: true, lineStyle: { type: dotted, opacity: 0.2 } } }
yAxis: { type: category, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: false }, axisLabel: { fontSize: 10, fontFamily: monospace }, data: [wide-max, wide-avg, wide-min, "", safe-max, safe-avg, safe-min, "", norm-max, norm-avg, norm-min, "", fast-max, fast-avg, fast-min] }
series:
  - { name: Lease Expire, type: bar, stack: main, barWidth: 20, z: 2, emphasis: { focus: series }, itemStyle: { color: "#e15759" }, data: [120, 110, 100, "-", 60, 55, 50, "-", 30, 27, 25, "-", 20, 17, 15] }
  - { name: Replica Detect, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#edc949" }, data: [20, 10, 0, "-", 10, 5, 0, "-", 5, 3, 0, "-", 5, 3, 0] }
  - { name: Elect & Promote, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#59a14f" }, data: [2, 1, 0, "-", 2, 1, 0, "-", 2, 1, 0, "-", 2, 1, 0] }
  - { name: HAProxy Check, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#4e79a7" }, data: [8, 6, 4, "-", 6, 5, 3, "-", 4, 3, 2, "-", 2, 2, 1] }
  - { name: Total RTO, type: bar, barGap: "-100%", barWidth: 20, z: 1, itemStyle: { color: "#888", opacity: 0 }, emphasis: { itemStyle: { opacity: 0 } }, data: [150, 127, 104, "-", 78, 66, 53, "-", 41, 34, 27, "-", 29, 23, 16] }
  - { name: RTO Budget, type: bar, barGap: "-100%", barWidth: 20, z: 0, itemStyle: { color: "rgba(0,0,0,0.08)" }, emphasis: { itemStyle: { color: "rgba(0,0,0,0.12)" } }, data: [150, 150, 150, "-", 90, 90, 90, "-", 45, 45, 45, "-", 30, 30, 30] }
Failure Model
| Phase | Best | Worst | Average | Description |
|---|---|---|---|---|
| Lease Expiration | ttl - loop | ttl | ttl - loop/2 | Best: crash just before refresh Worst: crash right after refresh |
| Replica Detect | 0 | loop | loop / 2 | Best: exactly at check point Worst: just missed check point |
| Election Promote | 0 | 2 | 1 | Best: direct lock and promote Worst: API timeout + Promote |
| HAProxy Check | (rise-1) × fastinter | (rise-1) × fastinter + inter | (rise-1) × fastinter + inter/2 | Best: state change before check Worst: state change right after check |
Key Difference Between Passive and Active Failover:
| Scenario | Patroni Status | Lease Handling | Primary Wait Time |
|---|---|---|---|
| Active Failover (PG crash) | Alive, healthy | Actively tries to restart PG, releases lease on timeout | primary_start_timeout |
| Passive Failover (Node crash) | Dies with node | Cannot actively release, must wait for TTL expiration | ttl |
During passive failure, Patroni stops with the node and cannot release the Leader Key. An election waits until the DCS lease TTL expires.
Timeline Analysis
Phase 1: Lease Expiration
Primary Patroni renews the Leader Key each loop_wait cycle and resets its TTL.
- Best case: Failure occurs just before lease refresh (elapsed
loopsince last refresh), remaining TTL =ttl - loop - Worst case: Failure occurs right after lease refresh, must wait full
ttl - Average case:
ttl - loop/2
Phase 2: Replica Detection
Each loop_wait cycle, replicas check the DCS Leader Key.
- Best case: Replica happens to wake when lease expires, wait
0 - Worst case: Replica just entered sleep when lease expires, wait
loop - Average case:
loop/2
Phase 3: Lock Contest & Promote
After detecting Leader Key expiration, replicas begin an election. The winner acquires the key and runs pg_ctl promote.
- Query replica replication positions in parallel through REST APIs. Typical response time is 10ms; the hardcoded timeout is 2s.
- Compare WAL positions and select the best candidate. Replicas attempt atomic CAS creation of the Leader Key.
- Run
pg_ctl promote. Its duration is usually negligible.
- Best case: Single replica or immediate lock acquisition and promotion, constant overhead
0.1s - Worst case: DCS API call timeout:
2s - Average case:
1sconstant overhead
Phase 4: Health Check
HAProxy requires rise consecutive successful checks before routing traffic to the new primary.
- Best case: New primary promoted just before check,
(rise-1) × fastinter - Worst case: New primary promoted right after check,
(rise-1) × fastinter + inter - Average case:
(rise-1) × fastinter + inter/2
RTO Formula
Add the phase durations to calculate total RTO:
Best Case
Average Case
Worst Case
Model Calculation
Apply the four RTO presets to these formulas:
Four Mode Calculation Results (unit: seconds, format: min / avg / max)
| Phase | fast | norm | safe | wide |
|---|---|---|---|---|
| Lease Expiration | 15 / 17 / 20 | 25 / 27 / 30 | 50 / 55 / 60 | 100 / 110 / 120 |
| Replica Detection | 0 / 3 / 5 | 0 / 3 / 5 | 0 / 5 / 10 | 0 / 10 / 20 |
| Lock Contest & Promote | 0 / 1 / 2 | 0 / 1 / 2 | 0 / 1 / 2 | 0 / 1 / 2 |
| Health Check | 1 / 2 / 2 | 2 / 3 / 4 | 3 / 5 / 6 | 4 / 6 / 8 |
| Total | 16 / 23 / 29 | 27 / 34 / 41 | 53 / 66 / 78 | 104 / 127 / 150 |
4.2.2 - Model of Patroni Active Failure
infographic list-row-simple-horizontal-arrow
data
  desc When Patroni is healthy but PostgreSQL crashes
  items
    - label Crash Found
    - label Restart Timeout
    - label Replica Detect
    - label Elect Promote
    - label HAProxy Check
theme light
  palette antv
RTO Timeline
tooltip: { trigger: axis, axisPointer: { type: shadow }, formatter: $fn:fmt }
legend: { top: 0, itemGap: 12, data: [ Crash Found, Restart Timeout, Replica Detection, Elect Promote, HAProxy Check] }
grid: { left: 64, right: 24, bottom: 32, top: 40 }
xAxis: { type: value, name: Seconds, nameLocation: end, max: 160, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: true, lineStyle: { type: dashed, opacity: 0.5 } }, minorTick: { show: true, splitNumber: 5 }, minorSplitLine: { show: true, lineStyle: { type: dotted, opacity: 0.2 } } }
yAxis: { type: category, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: false }, axisLabel: { fontSize: 10, fontFamily: monospace }, data: [wide-max, wide-avg, wide-min, "", safe-max, safe-avg, safe-min, "", norm-max, norm-avg, norm-min, "", fast-max, fast-avg, fast-min] }
series:
  - { name: Crash Found, type: bar, stack: main, barWidth: 20, z: 2, emphasis: { focus: series }, itemStyle: { color: "#b07aa1" }, data: [20, 10, 0, "-", 10, 5, 0, "-", 5, 3, 0, "-", 5, 3, 0] }
  - { name: Restart Timeout, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#f28e2c" }, data: [95, 95, 0, "-", 45, 45, 0, "-", 25, 25, 0, "-", 15, 15, 0] }
  - { name: Replica Detect, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#edc949" }, data: [20, 10, 0, "-", 10, 5, 0, "-", 5, 3, 0, "-", 5, 3, 0] }
  - { name: Elect Promote, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#59a14f" }, data: [2, 1, 0, "-", 2, 1, 0, "-", 2, 1, 0, "-", 2, 1, 0] }
  - { name: HAProxy Check, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#4e79a7" }, data: [8, 6, 4, "-", 6, 5, 3, "-", 4, 3, 2, "-", 2, 2, 1] }
  - { name: RTO Total, type: bar, barGap: "-100%", barWidth: 20, z: 1, itemStyle: { color: "#888", opacity: 0 }, emphasis: { itemStyle: { opacity: 0 } }, data: [145, 122, 4, "-", 73, 61, 3, "-", 41, 35, 2, "-", 29, 24, 1] }
  - { name: RTO Budget, type: bar, barGap: "-100%", barWidth: 20, z: 0, itemStyle: { color: "rgba(0,0,0,0.08)" }, emphasis: { itemStyle: { color: "rgba(0,0,0,0.12)" } }, data: [150, 150, 150, "-", 90, 90, 90, "-", 45, 45, 45, "-", 30, 30, 30] }
Failure Model
| Item | Best | Worst | Average | Description |
|---|---|---|---|---|
| Crash Found | 0 | loop | loop/2 | Best: PG crashes right before check Worst: PG crashes right after check |
| Restart Timeout | 0 | start | start | Best: PG recovers instantly Worst: Wait full start timeout before releasing lease |
| Replica Detect | 0 | loop | loop/2 | Best: Right at check point Worst: Just missed check point |
| Elect Promote | 0 | 2 | 1 | Best: Acquire lock and promote directly Worst: API timeout + Promote |
| HAProxy Check | (rise-1) × fastinter | (rise-1) × fastinter + inter | (rise-1) × fastinter + inter/2 | Best: State changes before check Worst: State changes right after check |
Key Difference Between Active and Passive Failure:
| Scenario | Patroni Status | Lease Handling | Main Wait Time |
|---|---|---|---|
| Active Failure (PG crash) | Alive, healthy | Actively tries to restart PG, releases lease after timeout | primary_start_timeout |
| Passive Failure (node down) | Dies with node | Cannot actively release, must wait for TTL expiry | ttl |
During active failure, Patroni remains available. It detects a PostgreSQL crash and attempts a restart. If restart succeeds, service recovers locally. If recovery times out, Patroni releases the Leader Key and triggers an election.
Timing Analysis
Phase 1: Failure Detection
Each loop_wait cycle, Patroni checks PostgreSQL through pg_isready or a process check.
- Best case: PG crashes right before Patroni check, detected immediately, wait
0 - Worst case: PG crashes right after check, wait for next cycle, wait
loop - Average case:
loop/2
Phase 2: Restart Timeout
After detecting a crash, Patroni attempts to restart PostgreSQL. There are two possible results:
Path A: Self-healing Success (Best case)
- PostgreSQL restarts and service recovers.
- No failover occurs, so RTO is very short.
- Wait:
0relative to the failover path.
Path B: Failover Required (Average/Worst case)
- PostgreSQL does not recover before
primary_start_timeout. - Patroni releases the Leader Key.
- Wait:
start.
Note: The average assumes failover is necessary. A quick local restart can substantially reduce RTO.
Phase 3: Standby Detection
Standbys check the DCS Leader Key each loop_wait cycle. After the primary releases it, they detect its absence and begin an election.
- Best case: Standby wakes right when lease is released, wait
0 - Worst case: Standby just went to sleep when lease released, wait
loop - Average case:
loop/2
Phase 4: Lock & Promote
When the Leader Key is absent, standbys begin an election. The winner acquires the key and runs pg_ctl promote.
- Query standby replication positions in parallel through REST APIs. Typical response time is 10ms; the hardcoded timeout is 2s.
- Compare WAL positions and select the best candidate. Standbys attempt atomic CAS creation of the Leader Key.
- Run
pg_ctl promote. Its duration is usually negligible.
- Best case: Single standby or direct lock acquisition and promote, constant overhead
0.1s - Worst case: DCS API call timeout:
2s - Average case:
1sconstant overhead
Phase 5: Health Check
HAProxy requires rise consecutive successful checks before it marks the new primary healthy.
- Best case: New primary comes up right at check time,
(rise-1) × fastinter - Worst case: New primary comes up right after check,
(rise-1) × fastinter + inter - Average case:
(rise-1) × fastinter + inter/2
RTO Formula
Add the phase durations to calculate total RTO:
Best Case (PG instant self-healing)
Average Case (Failover required)
Worst Case
Model Calculation
Apply the four RTO presets to these formulas:
Calculation Results for Four Modes (unit: seconds, format: min / avg / max)
| Phase | fast | norm | safe | wide |
|---|---|---|---|---|
| Failure Detection | 0 / 3 / 5 | 0 / 3 / 5 | 0 / 5 / 10 | 0 / 10 / 20 |
| Restart Timeout | 0 / 15 / 15 | 0 / 25 / 25 | 0 / 45 / 45 | 0 / 95 / 95 |
| Standby Detection | 0 / 3 / 5 | 0 / 3 / 5 | 0 / 5 / 10 | 0 / 10 / 20 |
| Lock & Promote | 0 / 1 / 2 | 0 / 1 / 2 | 0 / 1 / 2 | 0 / 1 / 2 |
| Health Check | 1 / 2 / 2 | 2 / 3 / 4 | 3 / 5 / 6 | 4 / 6 / 8 |
| Total | 1 / 24 / 29 | 2 / 35 / 41 | 3 / 61 / 73 | 4 / 122 / 145 |
Comparison with Passive Failure
| Phase | Active Failure (PG crash) | Passive Failure (node down) | Description |
|---|---|---|---|
| Detection Mechanism | Patroni active detection | TTL passive expiry | Active detection discovers failure faster |
| Core Wait | start | ttl | start is usually less than ttl, but requires additional failure detection time |
| Lease Handling | Active release | Passive expiry | Active release is more timely |
| Self-healing Possible | Yes | No | Active detection can attempt local recovery |
RTO Comparison (Average case):
| Mode | Active Failure (PG crash) | Passive Failure (node down) | Difference |
|---|---|---|---|
| fast | 24s | 23s | +1s |
| norm | 35s | 34s | +1s |
| safe | 61s | 66s | -5s |
| wide | 122s | 127s | -5s |
Analysis: In
fastandnorm, active failures wait forprimary_start_timeout(start), making RTO slightly longer than for passive failures. Insafeandwide,start < ttl - loop, so active recovery is faster. A successful local restart can make the best-case active RTO much shorter.
4.2.3 - Network Partition
infographic list-row-simple-horizontal-arrow
data
  title Network Partition Failover Flow
  desc Primary partitioned from DCS, Patroni proactively demotes to prevent split-brain, waits for TTL expiration before switchover
  items
    - label Primary Demote
      desc Patroni demotes PG after retry timeout
      icon mingcute/shield-fill
    - label Lease Expiration
      desc Leader Key TTL expires
      icon mingcute/close-circle-fill
    - label Replica Detection
      desc Replica detects lease expiration, starts election
      icon mingcute/key-2-fill
    - label Lock & Promote
      desc Replica acquires lock and promotes to new primary
      icon mingcute/radar-fill
    - label Health Check
      desc HAProxy detects new primary online
      icon mingcute/arrow-up-circle-fill
theme light
  palette antv
RTO Timeline
tooltip: { trigger: axis, axisPointer: { type: shadow }, formatter: $fn:fmt }
legend: { top: 0, itemGap: 12, data: [Primary Demote, Lease Expiration, Replica Detection, Lock & Promote, Health Check] }
grid: { left: 64, right: 24, bottom: 32, top: 40 }
xAxis: { type: value, name: sec, nameLocation: end, max: 160, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: true, lineStyle: { type: dashed, opacity: 0.5 } }, minorTick: { show: true, splitNumber: 5 }, minorSplitLine: { show: true, lineStyle: { type: dotted, opacity: 0.2 } } }
yAxis: { type: category, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: false }, axisLabel: { fontSize: 10, fontFamily: monospace }, data: [wide-max, wide-avg, wide-min, "", safe-max, safe-avg, safe-min, "", norm-max, norm-avg, norm-min, "", fast-max, fast-avg, fast-min] }
series:
  - { name: Primary Demote, type: bar, stack: main, barWidth: 20, z: 2, emphasis: { focus: series }, itemStyle: { color: "#76b7b2" }, data: [50, 40, 30, "-", 30, 25, 20, "-", 15, 13, 10, "-", 10, 8, 5] }
  - { name: Lease Expiration, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#e15759" }, data: [70, 70, 70, "-", 30, 30, 30, "-", 15, 15, 15, "-", 10, 10, 10] }
  - { name: Replica Detection, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#edc949" }, data: [20, 10, 0, "-", 10, 5, 0, "-", 5, 3, 0, "-", 5, 3, 0] }
  - { name: Lock & Promote, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#59a14f" }, data: [2, 1, 0, "-", 2, 1, 0, "-", 2, 1, 0, "-", 2, 1, 0] }
  - { name: Health Check, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#4e79a7" }, data: [8, 6, 4, "-", 6, 5, 3, "-", 4, 3, 2, "-", 2, 2, 1] }
  - { name: RTO Total, type: bar, barGap: "-100%", barWidth: 20, z: 1, itemStyle: { color: "#888", opacity: 0 }, emphasis: { itemStyle: { opacity: 0 } }, data: [150, 127, 104, "-", 78, 66, 53, "-", 41, 34, 27, "-", 29, 23, 16] }
  - { name: RTO Budget, type: bar, barGap: "-100%", barWidth: 20, z: 0, itemStyle: { color: "rgba(0,0,0,0.08)" }, emphasis: { itemStyle: { color: "rgba(0,0,0,0.12)" } }, data: [150, 150, 150, "-", 90, 90, 90, "-", 45, 45, 45, "-", 30, 30, 30] }
Failure Model
| Phase | Best | Worst | Average | Notes |
|---|---|---|---|---|
| Demote | retry | loop + retry | loop/2 + retry | Patroni retries after detecting partition, demotes after timeout |
| Lease Expiration | ttl - loop - retry | ttl - loop - retry | ttl - loop - retry | Remaining TTL time after demotion (approximately constant) |
| Replica Detection | 0 | loop | loop/2 | Best: Right at detection point Worst: Just missed detection |
| Lock & Promote | 0 | 2 | 1 | Best: Direct lock and promote Worst: API timeout + Promote |
| Health Check | (rise-1) × fastinter | (rise-1) × fastinter + inter | (rise-1) × fastinter + inter/2 | Best: State changes before check Worst: State changes right after check |
Key difference between network partition and node crash:
| Scenario | Patroni State | PostgreSQL State | Lease Handling | Split-brain Risk |
|---|---|---|---|---|
| Node Crash (Expire) | Dies with node | Completely unavailable | Passive wait for TTL expiration | None |
| Network Partition (This scenario) | Alive but cannot access DCS | May still be running (needs active demotion) | Passive wait for TTL expiration | Yes, needs protection |
During a network partition, the primary can continue accepting writes, creating split-brain risk. If Patroni cannot renew the Leader Key, it actively demotes PostgreSQL to read-only or shuts it down.
Timeline Analysis
Phase 1: Primary Demotion
If a network partition blocks DCS access, primary Patroni retries its failed Leader Key renewal.
- Detection: The next
loop_waitcycle detects the partition. - Retry: Patroni retries DCS operations during
retry_timeout. - Demotion: After retries time out, Patroni demotes PostgreSQL to prevent split brain.
Design constraint: loop_wait + 2 × retry_timeout ≤ ttl lets the primary demote before the lease expires.
Phase 2: Lease Expiration
After demotion, the Leader Key remains in DCS until its TTL expires.
After demotion, the cluster waits for the remaining TTL. Partition detection and remaining TTL are negatively correlated in this model. An earlier partition means slower detection but more remaining TTL. Their sum is constant:
Note: Demotion plus lease expiration takes approximately ttl, as with an expired lease after node failure.
Phase 3: Replica Detection
Each loop_wait cycle, a replica checks the DCS Leader Key.
- Best case: Replica wakes right when lease expires, wait
0 - Worst case: Replica just entered sleep when lease expires, wait
loop - Average case:
loop/2
Phase 4: Lock & Promote
After detecting Leader Key expiration, replicas begin an election.
- Best case: Single replica or directly acquires lock and promotes,
≈ 0 - Worst case: DCS API call timeout,
2s - Average case:
1s
Phase 5: Health Check
HAProxy requires rise consecutive successful checks before it marks the new primary healthy.
- Best case:
(rise-1) × fastinter - Worst case:
(rise-1) × fastinter + inter - Average case:
(rise-1) × fastinter + inter/2
RTO Formula
Add the phase durations to calculate total RTO.
Demotion plus lease expiration is approximately ttl. Thus, the network-partition RTO formula matches the expired-lease failure formula:
Best Case
Average Case
Worst Case
Model Calculation
Apply the four RTO presets to these formulas:
Patroni constraint validation (loop + 2×retry ≤ ttl):
| Mode | loop | retry | TTL | loop + 2×retry | Meets constraint? |
|---|---|---|---|---|---|
| fast | 5 | 5 | 20s | 15s | ✓ Safe |
| norm | 5 | 10 | 30s | 25s | ✓ Safe |
| safe | 10 | 20 | 60s | 50s | ✓ Safe |
| wide | 20 | 30 | 120s | 80s | ✓ Safe |
Four mode calculation results (seconds, format: min / avg / max)
| Phase | fast | norm | safe | wide |
|---|---|---|---|---|
| Primary Demote | 5 / 8 / 10 | 10 / 13 / 15 | 20 / 25 / 30 | 30 / 40 / 50 |
| Lease Expiration | 10 | 15 | 30 | 70 |
| Replica Detection | 0 / 3 / 5 | 0 / 3 / 5 | 0 / 5 / 10 | 0 / 10 / 20 |
| Lock & Promote | 0 / 1 / 2 | 0 / 1 / 2 | 0 / 1 / 2 | 0 / 1 / 2 |
| Health Check | 1 / 2 / 2 | 2 / 3 / 4 | 3 / 5 / 6 | 4 / 6 / 8 |
| Total | 16 / 23 / 29 | 27 / 34 / 41 | 53 / 66 / 78 | 104 / 127 / 150 |
Network partitions and node crashes have the same RTO in this model because both wait for TTL expiration.
Split-brain Protection
Split brain is the main partition risk: the old primary might still accept writes. Patroni provides these protections:
1. Primary Self-Demotion
If Patroni cannot renew the Leader Key, it actively demotes PostgreSQL.
2. Linux Watchdog
If Patroni hangs and cannot demote PostgreSQL, Linux watchdog forces a system restart.
3. Fencing Mechanism
Configure fencing scripts to isolate the old primary forcibly, for example by disabling its network interface or stopping services.
Special Scenarios
Scenario A: Primary partitioned from DCS, replicas normal
The following is the most common partition scenario and the main subject of this page.
- Primary Patroni cannot refresh Leader Key → Active demotion
- Replica normally detects TTL expiration → Elected as new primary
- RTO ≈ Expire failure RTO
Scenario B: Primary normal, replica partitioned from DCS
- Primary normally refreshes Leader Key
- Replica cannot participate in election (but replication can continue)
- No failover triggered, service continues normally
Scenario C: All nodes partitioned from DCS
- Primary demotes, replica cannot elect
- Cluster completely unavailable
- Requires manual intervention to restore DCS connectivity
Comparison with Other Failures
| Failure Type | Primary State | Lease Handling | RTO | Split-brain Risk |
|---|---|---|---|---|
| Expire Failure | Node crash | Passive wait TTL expiration | 16s ~ 150s | None |
| Crash Failure | PG crash, Patroni alive | Release after restart timeout | 1s ~ 111s | None |
| Network Partition | Alive but isolated from DCS | Passive wait TTL expiration | 16s ~ 150s | Yes, needs protection |
| Manual Switchover | Normal or failed | Direct release/acquire | 1s ~ 11s | None |
A network partition has the same RTO as an expired-lease failure, but also needs split-brain protection. The constraint loop_wait + 2 × retry_timeout ≤ ttl is central to that protection.
4.3 - RTO Trade-offs
RTO (Recovery Time Objective) defines the maximum time required for the system to restore write capability when the primary fails.
Critical transaction systems typically need the shortest practical RTO, often below one minute.
Shorter RTO increases false failover risk. Network jitter can appear to be a failure. Cross-datacenter or cross-region deployments often allow 1–2 minutes to reduce this risk.
Trade-offs
pg_rto controls the failover unavailability limit. Presets fast, norm, safe, and wide support different network and deployment conditions. The default is norm, approximately 45 seconds.
Recovery includes detection, DCS lock expiration, election, promotion, and HAProxy detection of the new primary. Shorter phase timeouts reduce RTO. They also increase sensitivity to network jitter and false failover risk.
Choose a preset that balances recovery speed and false failover risk for your network. Poor networks need longer timeouts. Stable networks can use shorter timeouts.
flowchart LR
    A([Primary Failure]) --> B{Patroni<br/>Detected?}

    B -->|PG Crash| C[Attempt Local Restart]
    B -->|Node Down| D[Wait TTL Expiration]

    C -->|Success| E([Local Recovery])
    C -->|Fail/Timeout| F[Release Leader Lock]

    D --> F
    F --> G[Replica Election]
    G --> H[Execute Promote]
    H --> I[HAProxy Detects]
    I --> J([Service Restored])

    style A fill:#dc3545,stroke:#b02a37,color:#fff
    style E fill:#198754,stroke:#146c43,color:#fff
    style J fill:#198754,stroke:#146c43,color:#fff
Four Modes
Select one of four RTO presets for the network conditions.
| Name | fast | norm | safe | wide |
|---|---|---|---|---|
| Use Case | Same rack | Same datacenter (default) | Same region, cross-DC | Cross-region/continent |
| Network | < 1ms, very stable | 1-5ms, normal | 10-50ms, cross-DC | 100-200ms, public network |
| Target RTO | 30s | 45s | 90s | 150s |
| False Failover Risk | Higher | Medium | Lower | Very Low |
| Configuration | pg_rto: fast | pg_rto: norm | pg_rto: safe | pg_rto: wide |
- Use for stable networks below 1ms latency, such as one rack or switch.
- Average RTO: 14s; worst case: 29s. TTL is 20s; check interval is 5s.
- This needs the best network quality. Jitter can trigger failover, so false failover risk is higher.
- Default mode for normal same-datacenter networks, 1–5ms latency, and reasonable packet loss.
- Average RTO: 21s; worst case: 43s. TTL is 30s, allowing some network variation.
- This balances recovery speed and stability for most production environments.
- Use for same-region or same-area datacenters with 10–50ms latency and occasional jitter.
- Average RTO: 43s; worst case: 91s. TTL is 60s.
- The 60s primary restart wait allows more local recovery time and reduces false failover risk.
- Use across regions or continents with 100–200ms latency and possible public-network packet loss.
- Average RTO: 92s; worst case: 207s. TTL is 120s.
- Slower recovery provides a very low false failover rate for geographic disaster recovery.
RTO Timeline
Patroni HA has two main paths. Active detection finds a PostgreSQL crash and attempts a restart. Passive lease expiration waits for the TTL after node failure, then starts an election.
tooltip: { trigger: axis, axisPointer: { type: shadow }, formatter: $fn:fmt }
legend: { top: 0, itemGap: 10, data: [Lease Expiration, Failure Detection, Restart Timeout, Replica Detection, Lock & Promote, Health Check] }
grid: { left: 110, right: 24, bottom: 32, top: 40 }
xAxis: { type: value, name: Seconds, nameLocation: end, max: 160, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: true, lineStyle: { type: dashed, opacity: 0.5 } }, minorTick: { show: true, splitNumber: 5 }, minorSplitLine: { show: true, lineStyle: { type: dotted, opacity: 0.2 } } }
yAxis: { type: category, axisLine: { show: true }, axisTick: { show: true }, splitLine: { show: false }, axisLabel: { fontSize: 9, fontFamily: monospace }, data: [wide-passive-max, wide-passive-avg, wide-passive-min, wide-active-max, wide-active-avg, wide-active-min, "", safe-passive-max, safe-passive-avg, safe-passive-min, safe-active-max, safe-active-avg, safe-active-min, "", norm-passive-max, norm-passive-avg, norm-passive-min, norm-active-max, norm-active-avg, norm-active-min, "", fast-passive-max, fast-passive-avg, fast-passive-min, fast-active-max, fast-active-avg, fast-active-min] }
series:
  - { name: Lease Expiration, type: bar, stack: main, barWidth: 16, z: 2, emphasis: { focus: series }, itemStyle: { color: "#e15759" }, data: [120, 110, 100, "-", "-", "-", "-", 60, 55, 50, "-", "-", "-", "-", 30, 27, 25, "-", "-", "-", "-", 20, 17, 15, "-", "-", "-"] }
  - { name: Failure Detection, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#b07aa1" }, data: ["-", "-", "-", 20, 10, 0, "-", "-", "-", "-", 10, 5, 0, "-", "-", "-", "-", 5, 3, 0, "-", "-", "-", "-", 5, 3, 0] }
  - { name: Restart Timeout, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#f28e2c" }, data: ["-", "-", "-", 95, 95, 0, "-", "-", "-", "-", 45, 45, 0, "-", "-", "-", "-", 25, 25, 0, "-", "-", "-", "-", 15, 15, 0] }
  - { name: Replica Detection, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#edc949" }, data: [20, 10, 0, 20, 10, 0, "-", 10, 5, 0, 10, 5, 0, "-", 5, 3, 0, 5, 3, 0, "-", 5, 3, 0, 5, 3, 0] }
  - { name: Lock & Promote, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#59a14f" }, data: [2, 1, 0, 2, 1, 0, "-", 2, 1, 0, 2, 1, 0, "-", 2, 1, 0, 2, 1, 0, "-", 2, 1, 0, 2, 1, 0] }
  - { name: Health Check, type: bar, stack: main, z: 2, emphasis: { focus: series }, itemStyle: { color: "#4e79a7" }, data: [8, 6, 4, 8, 6, 4, "-", 6, 5, 3, 6, 5, 3, "-", 4, 3, 2, 4, 3, 2, "-", 2, 2, 1, 2, 2, 1] }
  - { name: RTO Total, type: bar, barGap: "-100%", barWidth: 16, z: 1, itemStyle: { color: "#888", opacity: 0 }, emphasis: { itemStyle: { opacity: 0 } }, data: [150, 127, 104, 145, 122, 4, "-", 78, 66, 53, 73, 61, 3, "-", 41, 34, 27, 41, 35, 2, "-", 29, 23, 16, 29, 24, 1] }
  - { name: RTO Budget, type: bar, barGap: "-100%", barWidth: 16, z: 0, itemStyle: { color: "rgba(0,0,0,0.08)" }, emphasis: { itemStyle: { color: "rgba(0,0,0,0.12)" } }, data: [150, 150, 150, 150, 150, 150, "-", 90, 90, 90, 90, 90, 90, "-", 45, 45, 45, 45, 45, 45, "-", 30, 30, 30, 30, 30, 30] }
Implementation
Each preset selects values for these 10 Patroni and HAProxy parameters:
| Component | Parameter | fast | norm | safe | wide | Description |
|---|---|---|---|---|---|---|
patroni | ttl | 20 | 30 | 60 | 120 | Leader lock TTL (seconds) |
loop_wait | 5 | 5 | 10 | 20 | HA loop check interval (seconds) | |
retry_timeout | 5 | 10 | 20 | 30 | DCS operation retry timeout (seconds) | |
primary_start_timeout | 15 | 25 | 45 | 95 | Primary restart wait time (seconds) | |
safety_margin | 5 | 5 | 10 | 15 | Watchdog safety margin (seconds) | |
haproxy | inter | 1s | 2s | 3s | 4s | Normal state check interval |
fastinter | 500ms | 1s | 1500ms | 2s | State transition check interval | |
downinter | 1s | 2s | 3s | 4s | DOWN state check interval | |
rise | 3 | 3 | 3 | 3 | Consecutive successes to mark UP | |
fall | 3 | 3 | 3 | 3 | Consecutive failures to mark DOWN |
Patroni Parameters
ttl: Leader lease lifetime. Failure to renew triggers expiration and election. It sets passive detection delay.loop_wait: Main loop interval. Each cycle checks health and synchronizes state.retry_timeout: DCS retry period. After partition-related retries fail, the primary demotes to prevent split brain.primary_start_timeout: Time allowed for local restart after a PostgreSQL crash. On expiration, release the Leader lock and fail over.safety_margin: Watchdog time allowance for restarting the system before split brain can occur.
HAProxy Parameters
inter: Check interval while service state is stable.fastinter: Shorter check interval during state changes.downinter: Check interval for recovery after a service is marked DOWN.rise: Consecutive successes required for UP. A new primary must pass this many checks before receiving traffic.fall: Consecutive failures required for DOWN.
Key Constraint
Patroni constraint: The primary must complete demotion before TTL expiration to prevent split brain.
Data Summary
Recommendations
fast requires latency below 1ms and very low packet loss. Use it only within one rack or switch for strict RTO targets. Test it thoroughly in production before enabling it.
norm is the default for most same-datacenter deployments. This page’s model gives passive and active averages of about 34 and 35 seconds. Its timeout allowance reduces false failovers from jitter.
safe suits same-city datacenters with higher latency or occasional jitter. Longer timeouts reduce false failovers. It is recommended for cross-datacenter recovery.
wide suits high-latency, cross-region or cross-continent networks, including public-network packet loss. It favors stability over speed. Its long timeouts keep false failover rates very low.
| Mode | Target RTO | Passive RTO | Active RTO | Scenario |
|---|---|---|---|---|
fast | 30 | 16 / 23 / 29 | 1 / 24 / 29 | Same switch, high-quality network |
norm | 45 | 27 / 34 / 41 | 2 / 35 / 41 | Default, same DC, standard network |
safe | 90 | 53 / 66 / 78 | 3 / 61 / 73 | Same-city active-active / cross-DC DR |
wide | 150 | 104 / 127 / 150 | 4 / 122 / 145 | Geo-DR / cross-country |
default | 326 | 22 / 34 / 46 | 2 / 314 / 326 | Patroni default params |
Set pg_rto to a preset name to configure Patroni and HAProxy automatically. The template checks pg_rto in pg_rto_plan. A numeric or unknown key falls back to norm. This fallback does not support an RTO expressed as seconds.
Presets come from pg_rto_plan. Override this mapping for a custom RTO strategy.
4.4 - Service Access
Split read and write operations, route traffic correctly, and deliver PostgreSQL cluster capabilities reliably.
A service exposes database cluster capabilities through a stable interface that hides the underlying cluster details.
Services provide stable production access, especially during HA failover. Personal users usually do not need this abstraction.
Personal Users
Services are mainly for production. Personal users with one node can connect directly through the instance name or IP address.
For example, connect to the default single-node pg-meta.meta database with any of these three users:
Service Overview
Production clusters commonly use primary-replica replication. Exactly one primary accepts writes. Replicas continuously receive its change logs and can serve read-only requests. This reduces primary load for read-heavy workloads. Separate write requests from read-only requests to use this capacity.
Pgbouncer reduces connection and backend-process overhead for frequent short connections. ETL and change operations can bypass the pool for direct access. Failover changes the primary, so write traffic must follow the new leader automatically. The Service abstraction combines read/write separation, pooled or direct access, and automatic failover routing.
Every database cluster needs this basic service:
- Read-write service (primary): Can read from and write to the database
Production clusters should provide at least these two services:
- Read-write service (primary): Write data: Can only be served by the primary.
- Read-only service (replica): Read data: Can be served by replicas; falls back to primary when no replicas are available
Depending on the workload, add services such as:
- Default direct service (default): Let administrators bypass the connection pool.
- Offline replica service (offline): Use a dedicated replica for ETL and analytics, separate from online reads.
- Sync replica service (standby): Serve reads without replication delay from a synchronous standby or primary.
- Delayed replica service (delayed): Read earlier cluster data from delayed replicas.
Access Services
Pigsty provides service access up to the cluster HAProxy endpoints. Clients can reach these load balancers in several ways.
Typically, DNS or a VIP points to one or more cluster load balancers.
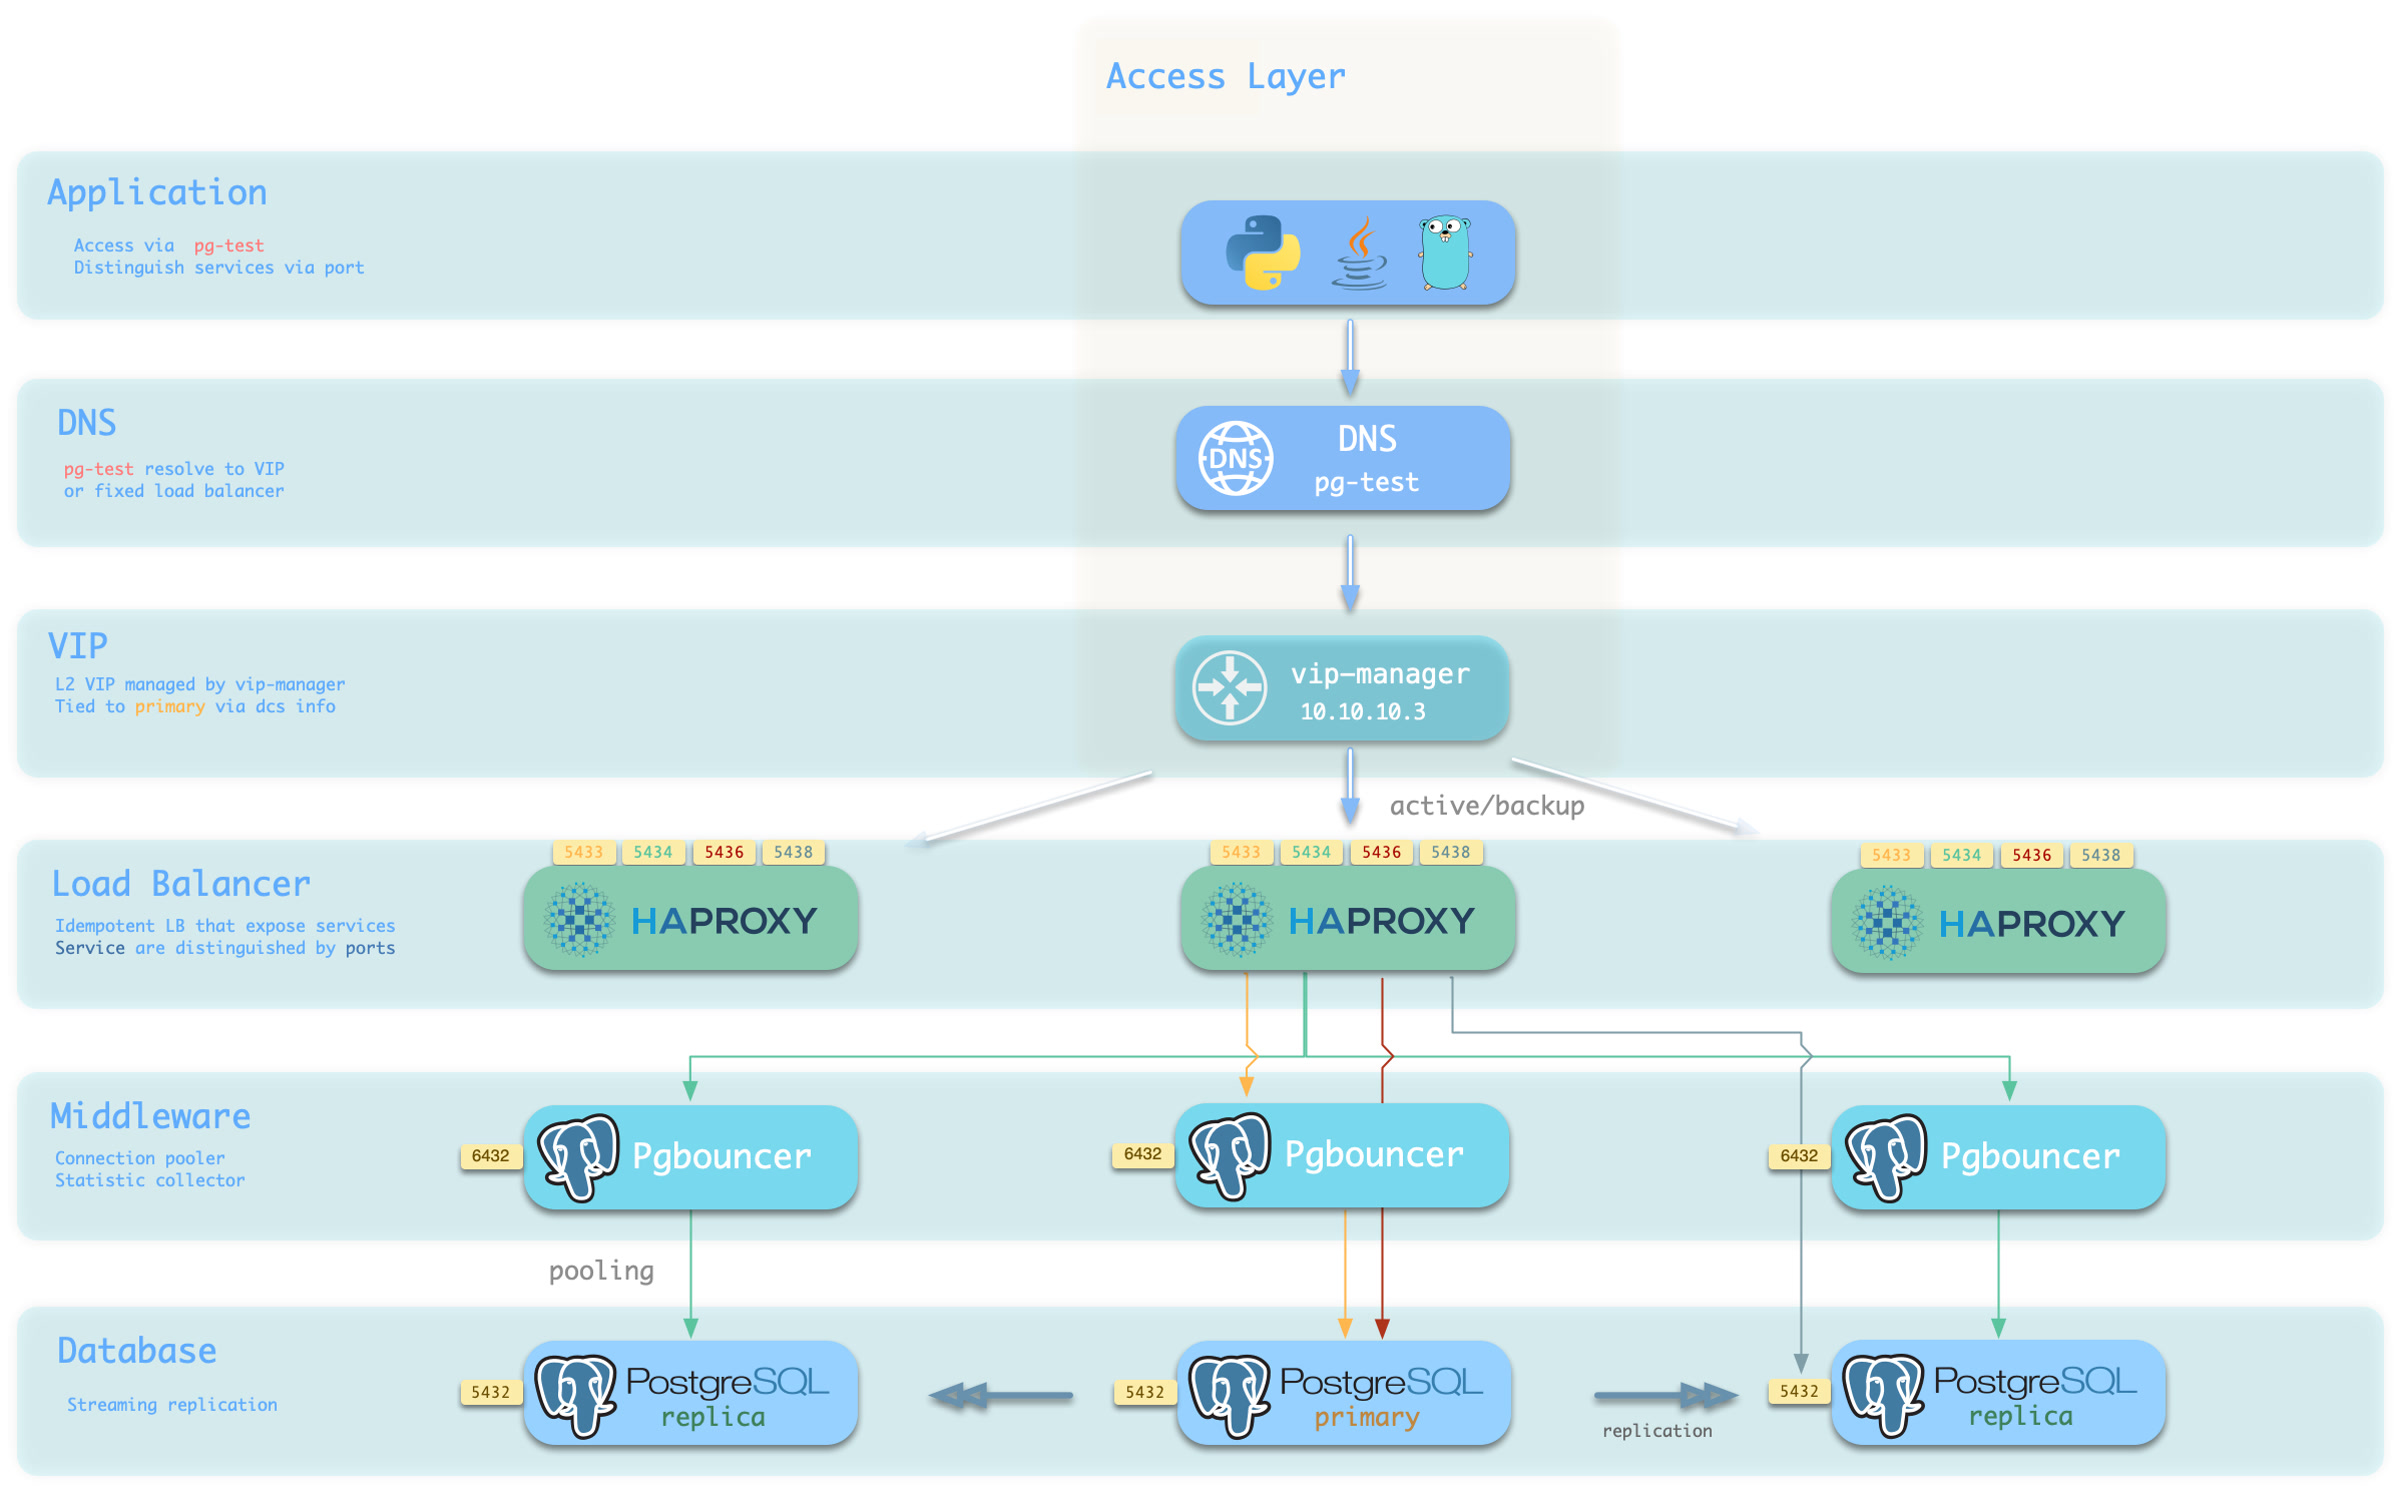
Choose a host and port combination for the required access method.
Host
| Type | Sample | Description |
|---|---|---|
| Cluster Domain Name | pg-test | Resolved by dnsmasq on INFRA nodes; with pg_dns_target: auto, points to the VIP when enabled, otherwise to the primary IP |
| Cluster VIP Address | 10.10.10.3 | When pg_vip_enabled is enabled, an L2 VIP managed by vip-manager and bound to the primary node |
| Instance Hostname | pg-test-1 | Access via any instance hostname (resolved by dnsmasq @ infra nodes) |
| Instance IP Address | 10.10.10.11 | Access any instance’s IP address |
Port
Different ports select different PostgreSQL services.
| Port | Service | Type | Description |
|---|---|---|---|
| 5432 | postgres | Database | Direct access to postgres server |
| 6432 | pgbouncer | Middleware | Access postgres through connection pool middleware |
| 5433 | primary | Service | Access primary pgbouncer (or postgres) |
| 5434 | replica | Service | Access replica pgbouncer (or postgres) |
| 5436 | default | Service | Access primary postgres |
| 5438 | offline | Service | Access offline postgres |
Combinations
5 - Point-in-Time Recovery — A Time Machine for PostgreSQL
Point-in-Time Recovery (PITR) can restore an earlier cluster state after accidental deletion of data, a table, or a database.
Pigsty enables PITR in its standard PostgreSQL configuration. This work once required specialist DBA knowledge.
Replication Is Not Backup
High availability can fail over to another instance after hardware failure. However, replication is not backup.
Streaming replication sends every primary change to replicas within milliseconds. This includes DELETE without WHERE or DROP TABLE against the wrong database. Failover handles machine failure. If the data is wrong, every replica can contain the same error.
Database disasters fall into two main classes. Multiple copies and automatic failover handle physical service failures. Logical errors require history: a base backup and continuous WAL archives. PostgreSQL uses them to reconstruct the state before an error.
| Threat | High Availability | Delayed Cluster | PITR |
|---|---|---|---|
| Hardware or instance failure | ✔ Automatic failover | ✘ | ✔, with a longer RTO |
| Accidental DML, table drop, or database drop | ✘ The error is replicated | ✔ Within the delay | ✔ At any recoverable point |
| Defective software corrupts data over time | ✘ The error is replicated | ✔ Within the delay | ✔ Try different recovery targets |
| Entire cluster or site is lost | ✘ | ✘ | ✔ Only if the repository survives that failure domain |
These mechanisms work together. HA restores service quickly. A delayed cluster provides a short recovery window. PITR provides the final recovery path through historical data.
How the Time Machine Works
A database is a state machine. A base backup is a complete physical snapshot at one point. WAL (Write-Ahead Log) records later state changes. With the snapshot and unbroken WAL history, PostgreSQL can replay to any covered target. The backup sets the earliest recovery point. The latest archived WAL sets the most recent recovery point.
Base backup + WAL archive = point-in-time recovery
Pigsty manages both inputs. By default, cluster initialization attempts an initial full backup. The primary continuously sends completed WAL segments to the selected repository. See How PITR Works for backups, archives, targets, and timelines.
Available Out of the Box
The standard PostgreSQL configuration enables PITR. Pigsty prepares each cluster with a backup repository, WAL archiving, and pgBackRest recovery tools. Customize the declarative policy with these parameters:
The default local method stores backups under /pg/backup and retains two full backups. One successful daily full backup gives a recovery window of roughly 24–48 hours. The remote minio preset uses Silo or compatible S3 storage, AES-256-CBC repository encryption, and time-based retention. With 14-day retention and weekly full backups, its steady-state window is roughly 14–21 days. Both ranges are policy estimates. Actual coverage starts at the oldest usable backup and ends at the latest WAL in the repository.
For declarative recovery, specify a target. The playbook stops the cluster, restores files, replays WAL, and rebuilds HA. An operator must verify the recovered business state.
This follows Pigsty’s declarative configuration model. The cluster definition includes backup policy. The recovery target is another declared parameter.
Benefits and Costs
PITR improves data integrity and availability:
- RPO (maximum data loss) usually decreases to minutes. WAL that has not reached a surviving repository sets this limit.
- RTO (time to restore service) becomes tens of minutes to hours, instead of permanent loss. It depends on backup size, WAL replay distance, and disk or network throughput.
| Standalone strategy | Event | RTO | RPO |
|---|---|---|---|
| No backup | Host and local data are lost | Permanent loss | All data |
| Base backups only | Host and local data are lost | Backup size and bandwidth, often hours | Changes since the latest backup |
| Base backups + WAL archives | Host and local data are lost | Backup size, replay distance, and bandwidth | WAL not yet present in the surviving repository |
The costs fall mainly into three areas:
- Confidentiality: Backups copy business data and need encryption and access control. The remote preset enables repository encryption. Change its default password.
- Resources: Backups consume storage; archiving consumes bandwidth. Compression, bundling, and block incremental backup reduce these costs. Capacity planning remains necessary.
- Operations: Monitor backup status and rehearse recovery. A successful backup job does not prove that recovery can meet the required RTO.
PITR does not replace HA. Production designs usually combine HA for physical failures with PITR for logical errors and site recovery.
Next Steps
- How PITR Works: snapshots, WAL history, recovery windows, targets, and timelines
- PITR Architecture: pgBackRest, repository selection, archive flow, scheduling, and failover behavior
- PITR Tradeoffs: failure domains, capacity, retention, and backup frequency
- Declarative Recovery: the
pg_pitrparameter,pgsql-pitr.yml, andpig pitr - PITR Scenarios: accidental deletion, bad releases, investigation, and site loss
For the operational runbooks, see PGSQL Backup and Recovery.
5.1 - How PITR Works
A database is a state machine. WAL (Write-Ahead Log) records its changes in order. PostgreSQL writes each change to WAL before applying it to data files. Keep a physical snapshot and all later WAL to replay the database to a selected consistent state.
PITR combines three elements: a snapshot (base backup), history (WAL archive), and a target where replay stops.
Snapshot: Base Backup
A base backup is a physical snapshot of the whole PostgreSQL cluster. It provides the recovery starting point. Pigsty uses pgBackRest to manage three backup types:
| Type | Contents | Recovery characteristics |
|---|---|---|
| Full | All database-cluster files | Self-contained, shortest chain, largest backup |
| Differential | Changes since the latest full backup | Restore uses the full plus the differential |
| Incremental | Changes since the latest backup of any type | Smallest backup, restore depends on its complete chain |
Run pg-backup [full|diff|incr] to start a backup. With no argument, it requests incr. If no valid full backup exists, pgBackRest creates one instead. pg_crontab declares recurring jobs and installs them in the postgres user’s crontab.
Backup frequency affects recovery time. A newer usable backup requires less WAL replay to reach the same target. See PITR Tradeoffs.
WAL History
A snapshot contains only its own state. WAL archiving preserves later changes needed to recover beyond it. Standard Patroni templates enable archiving and send each completed WAL segment to pgBackRest:
Two implementation details matter:
archive_timeout: 300: PostgreSQL can force a segment switch after five minutes on a cluster with few writes. A partially filled segment therefore does not wait indefinitely. When WAL is generated, this usually keeps the latest recovery point within minutes. It does not guarantee that every commit is already remote.- Asynchronous archive: pgBackRest batches transfers with
/pg/spoolandarchive-async=y. Pigsty setsarchive-push-queue-max=4GiB. If repository failure causes the queue to exceed this limit, pgBackRest can discard queued WAL to protect local disk space. The resulting archive gap requires a new full backup to establish a recoverable chain.
Expiration is automatic. When the repository policy expires old backups, pgBackRest also expires WAL that no remaining backup needs. Explicit archive-retention settings can override this behavior.
Recovery Window
The backup and its continuous WAL history form a recovery window:
- Left boundary: The start of the oldest usable remaining backup chain. Time-based descriptions usually use the oldest retained full backup’s time.
- Right boundary: The latest WAL successfully archived to a repository that survives the incident.
The window advances as new backups arrive and old chains expire. The local preset keeps two full backups. One successful daily full backup gives roughly one to two days of coverage. The minio preset sets retention_full_type: time and retention_full: 14. With weekly full backups, the oldest retained chain normally gives roughly 14–21 days of steady-state coverage. These are estimates, not SLAs.
Missed backups, archive gaps, archive-retention overrides, and repository loss can change actual coverage. Check pig pb info and perform restore drills to verify the window.
See PITR Tradeoffs and Backup Policy.
Targets: Where Replay Stops
PostgreSQL can identify states within the recovery window in several ways. pg_pitr exposes six target types:
pg_pitr type | Meaning | Typical use |
|---|---|---|
default | Replay through all WAL available from the repository | Restore the newest archived state after total loss |
time | Stop at a timestamp | Recover from accidental DML or DDL |
xid | Stop at a transaction ID | Exclude a precisely identified bad transaction |
lsn | Stop at a WAL location | Low-level exact targeting |
name | Stop at a restore point created with pg_create_restore_point() | Planned change checkpoint |
immediate | Stop as soon as the selected backup becomes consistent | Validate or expose the selected backup state quickly |
set selects the backup set that pgBackRest uses as the starting snapshot. It does not specify where replay stops.
Boundary Semantics
Targets are inclusive by default, retaining the transaction at the target. To stop before a known bad target, set exclusive: true. This maps to recovery_target_inclusive = false.
Transactions remain atomic. Recovery retains transactions committed before the effective target and rolls back transactions not yet committed. The resulting state is consistent, without partial transactions.
Timelines
Restoring an earlier state and accepting new writes creates a history branch. PostgreSQL assigns a timeline to each branch. PITR promotion, replica promotion, and failover can create new timelines. New WAL does not overwrite files from old timelines.
gitGraph
    commit id: "Full backup"
    commit id: "Normal writes"
    commit id: "Bad change"
    commit id: "More writes"
    branch Timeline-2
    checkout Timeline-2
    commit id: "PITR before bad change"
    commit id: "New writes"
Retained history permits another attempt if the first target was wrong. Use timeline to select a timeline. Pigsty defaults to latest.
Continue with PITR Architecture to see how these concepts map to Pigsty components and configuration.
5.2 - PITR Architecture
The PITR principle is simple, but implementation must address several constraints. WAL archiving must not block production writes. Object storage backups need encryption. Backup jobs must follow the primary after failover, and shared repositories must isolate clusters. Large numbers of small objects can also limit throughput.
Pigsty uses pgBackRest with production defaults that address these constraints. This page describes the engine, repository abstraction, archive path, scheduler, and execution on the current primary.
Backup Engine: pgBackRest
Pigsty uses pgBackRest to create base backups with backup, receive WAL with archive-push, and restore data with restore and archive-get.
Relevant capabilities include:
- Parallelism: Backup, archive, and restore operations can use multiple processes.
- Backup chains: Full, differential, incremental, and block incremental backups reduce repeated transfers and storage.
- Compression and encryption: pgBackRest includes zstd compression and AES-256-CBC repository encryption.
- Repository backends: pgBackRest supports POSIX filesystems, S3-compatible services such as Silo and MinIO, Azure, GCS, and SFTP.
- Bundling: Pack small files into larger repository objects to reduce object storage overhead.
pgBackRest separates cluster histories by stanza. Pigsty uses pg_cluster as the stanza name. Multiple clusters can share storage while retaining separate backup identities:
Repository Abstraction
pgbackrest_method selects a repository name. pgbackrest_repo contains a dictionary of candidate definitions. Pigsty v4.5.0 renders only the selected pgbackrest_repo[pgbackrest_method] entry as repo1. Listing local and minio does not activate both repositories.
The local preset provides simple backups and fast local restores. It has no encryption or bundling and retains backups by full-backup count. The minio preset uses remote Silo or compatible S3 storage. It enables encryption, bundling, block incremental backup, and time-based retention.
Pigsty converts underscores in repository keys to hyphens. It adds a repo1- prefix and writes the keys to /etc/pgbackrest/pgbackrest.conf. A custom cloud repository can therefore use pgBackRest options directly:
See Backup Repository for Silo, external S3-compatible storage, versioning, object locking, TLS, and credential details.
Archiving and Scheduling
When pgbackrest_enabled is true, the Patroni templates set the following configuration. This option defaults to true.
Base backups enter the system in two ways:
- Initial backup: After bootstrapping a top-level primary, Pigsty attempts a backup if
pgbackrest_init_backupis true. The task ignores backup failures. It writes/etc/pgbackrest/initial.doneonly after success, so the marker confirms completion. - Scheduled backup:
pg_crontabinstalls jobs in the database superuser’s crontab. The role default is an empty list. Standard examples usually add a daily full backup at 01:00.
pg-backup [full|diff|incr] wraps pgbackrest backup. Without an argument, it requests an incremental backup. If no usable full backup exists, pgBackRest makes a full backup instead.
Backups Follow the Primary
Every PostgreSQL node receives pgBackRest and the same scheduled job. However, pg-backup checks /pg/bin/pg-role and proceeds only on the current primary. Replicas exit immediately without creating competing backups.
The backup schedule therefore operates independently of HA topology:
- All members receive the same repository configuration and crontab.
- After failover, the new primary can run subsequent backups and archive WAL. The schedule needs no change.
- The current primary alone controls authoritative writes to a stanza.
For a non-local repository, Pigsty adds pgBackRest after basebackup in Patroni’s create_replica_methods. Patroni tries basebackup first. If it fails, Patroni can restore the replica with pgbackrest --delta restore. This moves the copy load from the primary to the repository.
Performance Defaults
The pgBackRest template limits overhead during normal operation and prioritizes restore throughput:
| Setting | v4.5.0 behavior | Rationale |
|---|---|---|
| Compression | compress-type=zst | Balance compression ratio and throughput |
| Backup/archive workers | One quarter of CPU, clamped to 2–4 | Limit competition with the database |
| Restore workers | All detected CPU, capped at 8 | Minimize restore time |
| Asynchronous archive | archive-async=y, spool under /pg/spool | Batch transfer without synchronous object-store latency |
| Archive queue limit | archive-push-queue-max=4GiB | Bound local spool growth |
| Fast backup start | start-fast=y | Request an immediate checkpoint |
| Incremental restore | delta=y | Reuse destination files that already match |
The 4 GiB queue limit has a tradeoff. If the repository remains unavailable and the queue exceeds this limit, pgBackRest can discard queued archive files. PostgreSQL continues running, but the WAL archive has a gap. Create a new full backup to establish a new recovery chain. See How PITR Works.
Observability
When backup and exporter settings are enabled, pgbackrest_exporter runs on each PostgreSQL node. It exposes metrics on port 9854. Monitoring uses these metrics to show backup age, type, size, duration, and errors.
Useful diagnostic entry points include:
| Entry | Purpose |
|---|---|
pb info | Shell helper for pgbackrest info using the configured stanza |
/pg/log/pgbackrest/ | pgBackRest backup, archive, and restore logs |
pg-backup | Manually request a backup on the primary: full / diff / incr |
See Backup Administration for operational checks, then PITR Tradeoffs for policy design.
5.3 - PITR Tradeoffs
Backups require storage, network traffic, and operational work. They determine how much data you can recover and how quickly service returns. More history usually requires more capacity. A shorter RTO usually requires newer backups and tested procedures.
A backup policy must define repository location, history retention, and backup frequency.
Where: Choose the Failure Domain
Repository location is the most important choice. It determines which disasters the backup can survive.
A local repository (pgbackrest_method: local) uses the primary’s local filesystem. It is simple and fast, with no remote service dependency. Data and backups usually share one failure domain. Machine, disk, or filesystem loss can destroy both. Local backup protects against logical errors. For protection against total host loss, /pg/backup must use independent storage.
An object storage repository (pgbackrest_method: minio or a custom S3 definition) sends backups to Silo or S3. For an independent disaster recovery copy, deploy it outside the database host or site failure domain. The minio preset enables AES-256-CBC repository encryption, bundling, and block incremental backup. Recovery throughput depends on the network and storage service. Operating that service adds responsibility.
| Scenario | Recommended repository | Reason |
|---|---|---|
| Development, test, demo | local | Minimal dependencies; rebuild is acceptable |
| Production | Dedicated Silo or compatible S3 storage | Independent failure domain and encrypted repository |
| Cloud deployment | Managed S3-compatible or cloud object storage supported by pgBackRest | Independent storage and lower operational burden |
| Ransomware/compliance | Versioned storage plus correctly configured object lock/retention | Prevent privileged database-host access from deleting protected versions |
The repository contains sensitive business data. Change default access keys and cipher_pass. Restrict access and protect credentials separately from database hosts. Verify any object-lock policy. See Backup Repository.
How Long: Capacity and Recovery Window
Longer history generally requires more storage. Actual use depends on compression, deduplication, block incremental backup, database change rate, and the full/differential/incremental backup mix. Measure backup and WAL growth instead of using a fixed multiplier.
For an illustrative 100 GB database changing by 10 GB per day, before compression:
- Daily full, retain two (
localpreset): Full backups use about 200 GB, plus WAL. Successful daily jobs commonly provide roughly one to two days of recovery history. - Weekly full, daily incremental, retain 14 days (
miniopreset): The oldest surviving weekly chain commonly provides roughly 14–21 days of coverage. Allow capacity for multiple full backups, their incrementals, archived WAL, and temporary retention-plus-one behavior during expiration.
The retention setting alone does not define the recovery window. Coverage starts at the oldest usable chain and ends at the latest WAL in the surviving repository. Time retention removes an old full backup only when another qualifying full backup satisfies the period. Related incremental backups and WAL follow the retained full chains. Check pig pb info, monitor archive health, and perform a restore to prove coverage.
Retain enough history to cover the delay between an error and its detection. A dropped table may be noticed within minutes. Slow corruption or month-end reconciliation failure can take weeks to detect.
How Often: Backup Frequency and RTO
Recovery first restores a backup chain, then replays WAL to the target. Backup size and storage throughput control restore time. The distance from backup to target controls replay time.
WAL replay is mostly serial. Restoring a weekly full backup just before the next full can require nearly a week of replay on a write-heavy database. Daily incremental backups shorten replay distance and transfer only changes since the preceding backup. They still require a valid chain. Monitor and test the entire chain, not only the latest file.
Choose a backup frequency that meets the measured RTO within the available backup window and production load budget.
Pigsty Presets
Pigsty provides two candidate repository definitions. pgbackrest_method selects one for the generated repo1 configuration.
Standard policy: local repository and daily full backup. This policy is simple and restores through local I/O. Use it for development or environments with separate protection against host loss:
Production policy: remote Silo/S3 repository, weekly full, daily incremental. Place the repository in a separate failure domain and use the encrypted minio preset:
local and minio entries in pgbackrest_repo are alternatives, not two active repositories. The template renders only pgbackrest_repo[pgbackrest_method] as repo1. Multiple active pgBackRest repositories require explicit advanced configuration. They also require independently tested backup, expiration, and restore procedures. The two presets alone do not provide this setup.
Use Backup Policy for capacity modelling and schedule details.
A Backup Is Proven by Restore
Monitor backup job success, and add clone recovery drills to routine operations. Use them to answer:
- Is the chain usable? Restore it end to end and validate data.
- What is the measured RTO? Database size and WAL volume change over time.
- Can the on-call operator execute the runbook? The first full exercise should not happen during an incident.
Clone recovery leaves the source online and overwrites the selected destination. Verify the exact destination and use disposable infrastructure. See Declarative Recovery for the recovery interface.
5.4 - Declarative Recovery
A backup must support recovery when an incident occurs. Traditional PITR requires connected manual steps: pause HA, stop PostgreSQL, prepare recovery settings, restore the backup, and replay WAL. Then validate the target, rebuild metadata, and start the cluster again.
Pigsty uses declarative configuration for recovery. Declare the recovery target. The tools stop the cluster, restore data, replay WAL, and return control to the operator.
Declare a Recovery Target
Set pg_pitr to describe the target. Run pgsql-pitr.yml to restore it. The most common form selects a specific time:
Fields in this parameter define the six recovery target types and other recovery behavior:
See Restore Operations for the complete field reference and examples.
What the Playbook Does
pgsql-pitr.yml divides recovery into six stages. Ansible tags let you run these stages separately:
| Stage | Action |
|---|---|
| Print the source cluster, target, and restore command; this stage reports the plan and does not prompt for confirmation | |
| pause | Run patronictl pause so Patroni does not intervene during maintenance |
| stop | Stop Patroni and PostgreSQL on replicas, then on the primary |
| pitr | Render recovery settings, run an incremental pgBackRest restore, start PostgreSQL to replay WAL, wait for consistency, and print control data |
| etcd | Remove stale cluster metadata from etcd so old and new timelines are not mixed |
| start | Start Patroni again, resume HA management, and rebuild replicas |
Keep these details in mind:
- Incremental restore: pgBackRest uses
deltato rewrite only files that differ from the backup. This can substantially reduce RTO for large databases. - Verification: The playbook prints checkpoint LSN, timeline, and NextXID from
pg_controldata. An operator must still verify the recovered business state. - Rollback copy:
backup: truemoves the original data directory to/pg/data-backupbefore recovery. A later run with this option removes any existing/pg/data-backup. It does not retain multiple snapshot versions. - Staged execution: Run
-t down,-t pitr, and-t upseparately for an operator checkpoint between phases. Thepitrphase completes when PostgreSQL reaches a consistent recovery state. For time, XID, LSN, or named targets, also confirm that WAL replay reached the target.
action controls behavior at the target. promote opens a new timeline, pause waits for inspection, and shutdown stops PostgreSQL. Targeted recovery defaults to pause if you omit action. Run stages separately to retain a manual checkpoint for pause or shutdown. For a single-run recovery, explicitly select promote. The playbook performs recovery steps but cannot determine whether the business data is correct.
Command-Line Recovery with pig
The pig CLI can perform single-instance PITR directly on a database node. It needs neither an administration node nor Ansible:
pig pitr validates the target, stanza, and available backups. It stops Patroni and PostgreSQL, restores data, optionally starts PostgreSQL, and prints further instructions. For a Patroni-managed directory, Patroni stays stopped afterward. Validate the data, then run pig pt start to resume HA management. This workflow does not clear etcd, rebuild replicas, or automatically rejoin the cluster. Destructive forced shutdown requires explicit --force-stop.
pig pb wraps lower-level pgBackRest commands. pb info lists backups, pb backup creates them, and pb restore runs a raw restore. pig pb restore refuses to run while Patroni manages the instance. Patroni could otherwise restart PostgreSQL during restoration. For Patroni-managed instances, use pig pitr or pgsql-pitr.yml.
In-Place and Clone Recovery
The same mechanism supports two different workflows:
| Dimension | In-place recovery | Clone recovery |
|---|---|---|
| Method | Roll the production cluster back | Restore a source backup into a different cluster |
| Downtime | Required during recovery | The source production cluster remains online |
| Effect | Discards all writes after the target | Does not affect the source; the destination is overwritten and can be retried |
| Best for | Whole-cluster corruption or disaster recovery | Recovering deleted objects, audit work, and recovery drills |
For clone recovery, cluster names the source backup stanza. This example restores historical pg-meta data into pg-test while the source remains online:
To recover a deleted table, exporting it from a clone and importing it into production is generally safer than restoring the whole cluster. See Clone a Database Cluster for the complete workflow and cleanup.
After Recovery
After recovery, complete these incident closeout steps:
- New timeline, new backup: After promotion, run
pg-backup fullto create a recovery window on the new timeline. - Archiving state: If you used
archive: falsefor investigation, restore normal archiving. See Post-Recovery. - Clone cleanup: A clone’s cluster identity differs from its source stanza. Recreate the destination stanza before enabling its backups. See Clone a Database Cluster.
Operators must select the target and choose in-place or clone recovery. They must also verify that the recovered data is correct. The tools execute the selected procedure. See PITR Scenarios for guidance on these decisions.
5.5 - PITR Scenarios
Decisions can consume much of the available incident response time. Pigsty automates recovery steps, but the operator must decide three things. Select the target, choose in-place or clone recovery, and define how to validate the result.
Read and rehearse this framework before an incident.
Decision Framework
| Scenario | Typical problem | Recommended workflow | Target |
|---|---|---|---|
| Accidental DML | DELETE or UPDATE affects the wrong rows | Clone, validate, then copy back data | time / xid |
| Dropped table, schema, or database | DROP or an incorrect migration | Clone, validate, then copy back objects | time / name |
| Defective release or batch corruption | Software writes incorrect data for a period | Clone and compare before choosing repair or cutover | time / xid |
| Audit, investigation, or forensics | Inspect historical state | Clone and hold at the target for inspection | time / lsn |
| Whole-cluster or site loss | Hosts or storage are gone or encrypted | Recover in place on replacement infrastructure | default / time |
Two principles apply throughout:
- Stop the damage first. Before selecting a target, pause the defective application or remove its write access. The recovery window keeps moving. However, restoring the wrong cluster in haste can cause another incident.
- Prefer a clone while production is usable. A clone leaves the source unchanged. You can try multiple targets and validate before export or cutover. Recovery overwrites the selected destination cluster. Use in-place recovery when the whole cluster is unusable or the business explicitly accepts rolling back every database.
flowchart TD
    A["Data error detected"] --> B["Contain the source of bad writes"]
    B --> C{"Can production still serve?"}
    C -->|Yes| D["Clone recovery<br/>validate and copy back or cut over"]
    C -->|No| E["In-place recovery<br/>or rebuild on new infrastructure"]
    D --> F["Validate, take a new backup, review the incident"]
    E --> F
Accidental DML
Common PITR cases include DELETE without WHERE, an incorrect UPDATE, and defective batch jobs.
Find the error in application logs, PostgreSQL logs, metrics, or audit records. A timestamp is usually sufficient. If you know the exact transaction ID, use xid with exclusive: true to stop immediately before it.
Validate the recovered rows. Copy only required data back with pg_dump, COPY, or an application-specific reconciliation procedure. A configured delayed cluster may provide faster access if it remains within its delay window.
Dropped Objects
Use the same approach for DROP TABLE, DROP DATABASE, or a migration in the wrong environment. Prefer a clone more strongly in these cases. Whole-cluster rollback to recover one object also discards every valid write after the target.
Restore a separate destination to before the DDL. Validate the object, export it with pg_dump, and import it into production. Before planned high-risk changes, create a restore point with pg_create_restore_point(). A name target avoids timestamp ambiguity.
Defective Release or Batch Corruption
A faulty release can corrupt data for hours. Identify the last correct state and the full impact. Restore a clone to candidate times and compare it with production. Then decide whether to copy corrected rows back or switch to a recovered cluster.
The application owner must validate this decision. Successful PostgreSQL recovery proves consistency at the target. It does not prove that the business state is correct.
Audit and Investigation
Historical questions, such as a month-end balance, require historical data. Restore a separate destination to a time, LSN, XID, or named point. Inspect it without changing the source.
Targeted recovery defaults to action: pause, which holds recovery at the target for inspection. This option does not configure read-only access or create a separate cluster. The inventory limit and cluster source field determine the destination workflow. For an operator checkpoint before promotion, run -t down, -t pitr, and -t up separately. Explicitly enforce read-only access if required for investigation. immediate stops at the first consistent point; it does not select a historical timestamp.
Site Loss
HA cannot help if every database host is destroyed or encrypted. The repository and other control-plane assets must survive outside that failure domain. Possible repositories include Silo/S3, another protected host or filesystem, and other tested pgBackRest backends. A remote object store is recommended. The essential requirement is survival in an independent failure domain.
Rebuild the hosts and restore the inventory, credentials, and PKI. Select the surviving repository, then restore through the latest archived WAL:
Inventory and backups alone are insufficient. Preserve installation media or package repositories, repository credentials, encryption passwords, CA material, custom files, and DNS dependencies. Keep an independently accessible runbook. Encrypt secrets and store them separately from database hosts and ordinary source control.
Make Recovery a Routine Drill
Do not run these procedures for the first time during a production incident. Rehearse clone recovery regularly on a disposable destination. Repeat after major architecture changes. Measure these outcomes:
- Usability: can the backup and complete WAL chain be restored and validated?
- RTO: how long does the actual restore and replay take now?
- Operator readiness: can the on-call engineer identify source and destination, select a target, and follow the safety gates?
See Restore Operations and Clone a Database Cluster for the task-level runbooks.
6 - Monitoring System
The built-in monitoring system provides metrics, logs, and alerting. Logs and alerts also support audit and traceability. It can monitor Pigsty-managed clusters, existing PostgreSQL clusters, and external RDS services.
Monitoring Targets
Pigsty monitoring covers these core targets:
- PostgreSQL clusters and instances (SQL performance, connections, replication, transactions, checkpoints, WAL)
- Infrastructure components (Grafana, VictoriaMetrics, Alertmanager, Nginx, etc.)
- Host nodes (CPU, memory, disk, network, kernel)
- Key middleware (ETCD, MINIO, REDIS, JUICE, VIBE, etc.)
Technology Stack
| Component | Purpose |
|---|---|
| Grafana | Visualization dashboards, unified entry point, alert views |
| VictoriaMetrics | Time-series metric ingestion, storage, and query |
| VictoriaLogs | Structured log ingestion, indexing, and search |
| VMAlert + Alertmanager | Alert rule evaluation and notification delivery |
| Exporter / Agent | Database/system metric exposure and log forwarding |
Onboarding Modes
Pigsty supports three ways to add monitoring:
| Mode | Use Case | Entry |
|---|---|---|
FULL | Database is deployed and managed directly by Pigsty | PGSQL Monitoring System |
MANAGED | Existing PostgreSQL cluster with SSH-manageable nodes | Monitor Existing Cluster |
RDS | Cloud database accessible only by connection string | Monitor RDS |
Continue Reading
- PGSQL Monitoring System: Database metrics, logs, alerting, and dashboards
- INFRA Monitoring & Alerting: Health of the monitoring stack itself
- NODE Monitoring & Alerting: Host resource and system health
- ETCD Monitoring & Alerting: Consistency and availability monitoring
- MINIO Monitoring & Alerting: Object storage cluster monitoring
- REDIS Monitoring & Alerting: Cache cluster runtime monitoring
7 - Security and Compliance
Databases usually store the most valuable and sensitive data in an information system. Attacks and failures can therefore have severe consequences. Security requires multiple controls: who can connect, what they can do, and whether traffic is protected. It must also record operations and support recovery of damaged, lost, or deleted data.
Pigsty provides a default security baseline through declarative configuration. Declare HBA rules, roles and privileges, certificates, encryption, backups, and audit policies as parameters in the inventory. Idempotent playbooks render and apply these settings.
Security as Code supports policy versioning, review, and traceability. One inventory provides a consistent baseline across instances. To audit database access, start with the YAML declaration. Then verify generated HBA rules and database grants against the running system.
Security as Code
Manual operations can scatter security settings across pg_hba.conf, DBA-issued GRANT statements, and temporary incident firewall rules. Documentation can then diverge from the running configuration. This makes each instance’s effective rules difficult to determine.
Pigsty stores security policy in the cluster definition alongside other properties.
Declare users, privileges, and HBA rules. Playbooks apply them idempotently to each instance, including new instances. Git history records configuration changes. Manual GRANT statements, runtime parameter changes, and node file edits can still cause drift. In production, regularly compare declared and actual state.
Default Security Baseline
The default configuration enables these controls to reduce omissions:
| Capability | Default Behavior | Related Parameter |
|---|---|---|
| Password hashing | New or updated PostgreSQL passwords use SCRAM-SHA-256 | pg_pwd_enc |
| Data checksums | Page checksums are enabled during cluster initialization to detect silent corruption | pg_checksum |
| Server-side TLS | PostgreSQL server certificates are installed and ssl is enabled, so TLS connections are accepted | — |
| Local CA | A self-signed CA is created automatically for managed component certificates | ca_create |
| etcd encryption and authentication | TLS for client and peer traffic, plus RBAC password authentication | etcd_root_password |
| MINIO object storage HTTPS | Silo backup traffic uses HTTPS by default | minio_https |
| Nginx HTTPS | Web ingress listens on both ports 80 and 443 by default | nginx_sslmode |
| HBA rules | Layered access: local ident, intranet password authentication, and SSL required for public administrator access | pg_default_hba_rules |
| Roles and privileges | A four-tier role model and default privilege templates provide a least-privilege baseline | pg_default_roles |
| Backup and recovery | pgBackRest is enabled by default, with two full backups retained in the local repository | pgbackrest_enabled |
| Firewall | Zone mode trusts intranet CIDRs and exposes only required ports to public networks | node_firewall_mode |
| Restricted sudo | Sudo access for the database OS user is limited to the required command set | pg_dbsu_sudo |
Hardening with Trade-offs
Defaults target a trusted intranet. Some controls need explicit enablement because of performance costs, compatibility limits, or required operator decisions:
- Examples contain public default passwords for quick starts and local tests. Before production, run
./configure -gto randomize recognized credentials. Then check the pgBackRest passphrase, Silo users inha/safe, and all custom values. - The Patroni REST API and PgBouncer disable TLS by default. Explicitly enable
patroni_ssl_enabledandpgbouncer_sslmodewith the issued certificates. - Password checks (
passwordcheck) and auditing (pgaudit) are disabled by default. Confirm package availability, then configure preloading and policy. - SELinux defaults to
permissive. Remove the demo firewall exception for port5432in production. - Local backups have no encryption by default. The remote
miniopreset enables AES-256 encryption. Change its default encryption passphrase.
The ha/safe template combines TLS, certificate authentication, password checks, and backup encryption. Use it with the consistency-first CRIT parameter template as a starting point. Review public credentials, audit extensions, and the failure model explicitly. See Security Model for the full hardening path.
This Chapter
| Section | Question Answered |
|---|---|
| Security Model | Where is the root of trust? How many defensive layers exist? How should the baseline be hardened? |
| Authentication | Who can connect? How is identity proven? How are HBA rules declared and applied? |
| Access Control | What can a connected user do? How does least privilege become the default? |
| Encrypted Communication | How is traffic encrypted? Who issues, distributes, and rotates certificates? |
| Data Security | How is data kept intact, recoverable, confidential, and traceable? |
| Compliance | How do security capabilities map to MLPS and SOC 2 controls? |
Related Topics
These pages provide operational security guidance:
- 🔰 Security Recommendations: minimum hardening for a quick single-node deployment
- 🛡️ Security Considerations: production hardening checklist
- 📄
ha/safeTemplate: complete hardening configuration reference - 🔑 HBA Rules: detailed PGSQL HBA configuration
- 👤 Access Control: role and privilege parameter reference
- ♾️ High Availability: business continuity
- ⏰ Backup and Recovery: PITR and disaster recovery
7.1 - Security Model
Identify the root of trust and defensive layers before selecting security features. The root of trust needs the strongest protection. Multiple layers preserve some protection if one fails.
Trust Boundaries
Pigsty uses Ansible for declarative deployment. Its administration node is the control plane and needs the strongest protection.
| Role | Assets and Privileges |
|---|---|
| Admin node | The pigsty.yml inventory, which normally contains system and application credentials; the CA private key; SSH administration access to every node |
| INFRA nodes | Monitoring and alerts, DNS, Nginx ingress, and software repositories |
| Database nodes | Database instances, local dbsu, and restricted sudo |
| Clients | Database credentials or client certificates; access through service ports, HBA, and authentication |
These roles have different capabilities, not a simple hierarchy. Protect these three assets in particular:
- The
pigsty.ymlinventory contains component passwords and credentials. Strictly restrict administration node access and access to any Git configuration repository. - The CA private key,
files/pki/ca/ca.key, anchors deployment trust. Its holder can issue any trusted certificate. The file uses mode0600inside a0700directory. Keep an offline backup. - The administration user’s SSH private key provides passwordless sudo access to all enrolled nodes. It effectively grants root access throughout the managed deployment.
Pigsty’s security policy defines this trust boundary. Attacks requiring administration node access, or both pigsty.yml and the CA private key, are not product vulnerabilities. These control-plane assets have high trust by design. Protect them accordingly.
Seven Defensive Layers
Defense in depth combines controls so that one failure does not remove all protection. Pigsty provides seven security layers:
| # | Layer | Mechanisms | Details |
|---|---|---|---|
| 1 | Network boundary | Firewall zones, constrained listen addresses, centralized ingress | This page |
| 2 | Transport encryption | Local CA and TLS between components | Encrypted Communication |
| 3 | Authentication | HBA rules, SCRAM passwords, client certificates | Authentication |
| 4 | Access control | Role model, default privileges, database isolation | Access Control |
| 5 | Host security | SELinux, restricted sudo, dedicated OS users | This page |
| 6 | Data security | Checksums, backup and encryption, PITR, deletion safeguards | Data Security |
| 7 | Audit trail | DDL and connection logs, audit extensions, centralized logs | Data Security |
Layers 2, 3, 4, 6, and 7 have dedicated chapters. The following sections cover the network and host layers.
Network Boundaries
Node provisioning enables firewalld or ufw, depending on the OS. node_firewall_mode defaults to zone. node_firewall_intranet places 10.0.0.0/8, 172.16.0.0/12, and 192.168.0.0/16 in the trusted zone. Public networks can reach only node_firewall_public_port ports. Defaults are 22 for SSH and 80/443 for web traffic.
The demo
pigsty.ymlalso exposes5432for local evaluation. Remove this exception in production. If direct database access is needed, restrict sources to explicit CIDRs through security groups, host firewalls, and HBA.
PostgreSQL listens on all addresses by default: pg_listen is 0.0.0.0. Listen addresses, firewall rules, and HBA jointly control access. For stricter access, constrain the listener:
The default firewall blocks direct public access to Grafana, VictoriaMetrics, and other web infrastructure. External web traffic normally uses the Nginx portal. Database traffic uses HAProxy service ports. Fewer entry points simplify hardening and auditing.
Host Security
Give each OS user only the privileges its job requires.
- The database superuser
postgres(pg_dbsu) has no password by default. It can enter the database only through localident.pg_dbsu_sudodefaults tolimit. This permits passwordless database servicesystemctloperations and log viewing, without unrestricted root access. - Operators and playbooks use
node_admin_username, defaultdba. It receives passwordless sudo (nopass) by default. For stricter control, setnode_admin_sudotoallto require a password, orlimitto restrict commands. node_selinux_modedefaults topermissive. SELinux records violations without blocking them, providing a baseline beforeenforcing.
Pigsty does not manage SSH server configuration. Put password-login restrictions, remote-root restrictions, and similar OS hardening in your host security baseline.
Hardening Levels
Harden the deployment in stages. Each level adds to the previous level:
Level 1: default baseline. Defaults provide SCRAM passwords, data checksums, a local CA, component certificates, layered HBA, four-tier roles, backups, and firewall zones. This suits development, testing, and evaluation on a trusted intranet. For production, review credentials and network boundaries, and configure client verification.
Level 2: randomized credentials. Change all public default passwords before any network-exposed deployment. Add -g to randomize recognized built-in parameters and example credentials:
This option does not replace pgBackRest cipher_pass, all Silo examples in ha/safe, or custom values. See the Default Credentials Checklist for coverage.
Level 3: policy hardening with ha/safe. conf/ha/safe.yml combines controls for further customization:
- TLS and certificates: Main TCP HBA rules use
ssl. Public administrator access requires a client certificate. PgBouncer usesrequire, and Patroni API uses HTTPS. Localidentand selected localhost password rules remain. - Password policy: The template preloads
passwordcheckand setsexpire_infor built-in users. Review and replace example passwords. - Reduced exposure: Listen addresses are limited to
${ip},${vip},${lo}. Public connection-pool access is explicitly denied for monitoring and administration accounts. - Backup encryption: pgBackRest uses the remote
miniopreset with AES-256-CBC. Replace the predictable examplepgBR.${pg_cluster}. - Security extensions: The template installs
passwordcheck,credcheck,pgaudit,pgsodium,anonymizer, and related extensions. Installation does not preload, create, or configure them.
Level 4: database hardening with crit.yml. The safe template selects CRIT for workloads that prioritize consistency. Compared with oltp, CRIT:
- Requires checksums regardless of
pg_checksum. - Enables strict synchronous replication (
synchronous_mode_strict). Writes needing synchronous acknowledgment block if no synchronous replica is available. - Logs connections and disconnections. PostgreSQL 18 separates connection receipt, authentication, and authorization.
- Sets watchdog to
automatic. It activates only if a usable device exists.
Strict synchronous mode aims to preserve acknowledged transactions. It depends on synchronous_commit, synchronous replica state, and failover eligibility. Verify RPO with failure exercises on the target topology.
You can select individual controls instead of the whole template:
Next
- 🔑 Authentication: HBA rules and password policy
- 👤 Access Control: roles and least privilege
- 🔐 Encrypted Communication: local CA and TLS
- 🔒 Data Security: integrity, backup, and audit
- ✅ Compliance: MLPS and SOC 2 mapping
7.2 - Authentication
pg_hba.conf defines PostgreSQL Host-Based Authentication. It controls who can connect, the source address, the database, and the required identity check.
Manual HBA maintenance across a cluster requires care. Primary and replica rules can differ, and each instance stores its configuration in its data directory. Without a shared declaration and refresh process, instance rules can diverge.
Pigsty declares HBA rules in the inventory through declarative configuration. Playbooks render and distribute them consistently.
HBA as Code
Cluster HBA combines global defaults in pg_default_hba_rules with cluster additions in pg_hba_rules. PgBouncer has separate equivalents: pgb_default_hba_rules and pgb_hba_rules.
Rules support two forms. The recommended alias form expresses one rule per line:
Use the raw form for cases aliases cannot express. It contains a literal pg_hba.conf line.
In addition to user, address, database, and authentication method, each rule has two control fields:
ordersets render order. HBA uses the first matching rule, so order sets priority. By convention,0-99is for high-priority user rules and100-999for defaults. Rules withoutordercome last.rolefilters by instance role.commonanddefaultapply everywhere.primary,replica,offline,standby, anddelayedapply only to matching instances.role: offlinealso applies to instances marked withpg_offline_query. One declaration therefore generates appropriate rules without separate manual primary and replica files.
After editing the declaration, run the wrapper script to render and reload the rules:
pg_hba_rules adds rules but does not automatically restrict broader defaults. For stricter access, also review pg_default_hba_rules. Inspect the resulting pg_hba.conf on every instance.
Address and Authentication Aliases
Aliases name common cases. Each addr value expands into address blocks:
| Alias | Expands To | Meaning |
|---|---|---|
local | Unix socket | Local socket only |
localhost | Unix socket, 127.0.0.1/32, and ::1/128 | Local host |
admin | <admin_ip>/32 | Admin node |
infra | /32 address of each INFRA node | Infrastructure nodes |
cluster | /32 address of every cluster member | Cluster-internal traffic |
intra | 10.0.0.0/8, 172.16.0.0/12, 192.168.0.0/16 | Intranet CIDRs, customizable with node_firewall_intranet |
world | 0.0.0.0/0 and ::/0 | Any address |
| CIDR | Unchanged | Custom network |
Values in auth select the authentication method and whether TLS is mandatory:
| Alias | Authentication Method | Notes |
|---|---|---|
deny | reject | Explicit rejection |
trust | trust | Unconditional access; use with care |
pwd | scram-sha-256 or md5 | Follows pg_pwd_enc; SCRAM by default |
sha | scram-sha-256 | Force SCRAM |
md5 | md5 | Compatibility for legacy clients |
ssl | hostssl with password authentication | Password authentication over mandatory TLS |
ssl-sha | hostssl with scram-sha-256 | Mandatory TLS and SCRAM |
cert | hostssl with cert | Client certificate authentication |
ident, os | ident (peer in PgBouncer) | OS user mapping |
peer | peer | Local OS user |
The user field supports four placeholders: ${dbsu} (superuser), ${repl} (replication user), ${monitor} (monitoring user), and ${admin} (administration user). Rendering replaces them with actual names. +role matches all members of that role.
auth: ssl requires TLS but does not require client verification of the server identity. Security-sensitive clients should use sslmode=verify-full with a trusted CA. See Encrypted Communication.
Default Rules Explained
The default HBA policy requires stronger authentication for more distant sources. These PostgreSQL defaults come from the source configuration:
Layer by layer:
- Local access:
postgrescan connect only through a local Unix socket withident. It needs no password and cannot log in remotely. Thus, dbsu has no default password. - Intranet access: Replication and application accounts use SCRAM password authentication. Remote monitoring and administration connections mainly come from INFRA nodes.
- Public access: Only the administrator can connect from any address by default. Both a password and TLS are required.
PgBouncer explicitly denies public access for monitoring and administration accounts. Application users can connect only from localhost and intranet sources.
The default +dbrole_offline rule has no role filter and applies to every instance. Add role: offline to restrict it to pg_role: offline or pg_offline_query: true instances.
The default policy lets application accounts connect from the intranet with passwords. ha/safe changes the main TCP rules to ssl. Administrators outside the intranet must present a client certificate (cert). Local ident and selected localhost password rules remain.
Password Policy
Pigsty defaults to PostgreSQL’s recommended scram-sha-256 password storage through pg_pwd_enc. Use md5 only for legacy clients.
Before ALTER USER ... PASSWORD, the workflow runs SET log_statement TO 'none' to temporarily disable statement logging. This keeps passwords out of PostgreSQL logs. The inventory still contains plaintext passwords. Rendered user SQL is stored at /pg/tmp/pg-user-<name>.sql with mode 0640. Related Ansible tasks do not consistently use no_log. Restrict access to the administration node, configuration repository, and automation output.
Avoid --diff for tasks that contain credentials.
Password strength checks are disabled by default. If required, preload passwordcheck or the more configurable credcheck:
ha/safe sets this pg_libs value explicitly. Selecting CRIT alone does not load passwordcheck.
Set account lifetime with expire_in (days after creation) or expire_at (absolute date). Combine this with your organization’s rotation process:
Certificate Authentication
Passwords can be phished, reused, or guessed. For privileged accounts, such as administrators, set HBA auth: cert to require client certificates. The local CA must sign the certificate, and its CN must match the database user name. If the rule accepts only cert, a leaked password alone cannot authenticate.
Issue client certificates with the built-in cert.yml playbook:
The files are files/pki/misc/<cn>.crt and files/pki/misc/<cn>.key. Deliver the private key through a controlled channel. The client should use verify-full to verify the database server. See Encrypted Communication.
Connection Pool and Component APIs
The database is not the only authenticated entry point.
PgBouncer has separate HBA rules and a separate user list. pgbouncer_auth_query is disabled by default. Only users with pgbouncer: true enter userlist.txt and can authenticate through the pool. Review permitted logins before enabling dynamic authentication queries.
The Patroni REST API controls operations such as restart, switchover, and configuration reload. Writes require HTTP Basic authentication through patroni_username and patroni_password. Source-address allowlists also restrict writes. Enable patroni_ssl_enabled to use HTTPS throughout.
The inventory also declares credentials for Grafana, HAProxy administration, the MINIO-selected object storage backend, etcd, and other components. See the Default Credentials Checklist for the full list and update instructions.
Next
- 📖 Complete HBA reference: HBA Rules
- 👤 Access Control: authorization after authentication
- 🔐 Encrypted Communication: TLS and client certificate infrastructure
7.3 - Access Control
Authentication verifies identity. Authorization determines what that identity can do.
PostgreSQL GRANT and REVOKE provide precise control. Privilege problems usually arise from missing default conventions. Examples include making an application account the owner, retaining temporary superuser access after troubleshooting, and omitting grants on new tables.
Pigsty provides four role tiers, default privileges, and database isolation. This starting model reduces manual grants per database. Operators must still assign roles to match business boundaries and regularly review effective privileges.
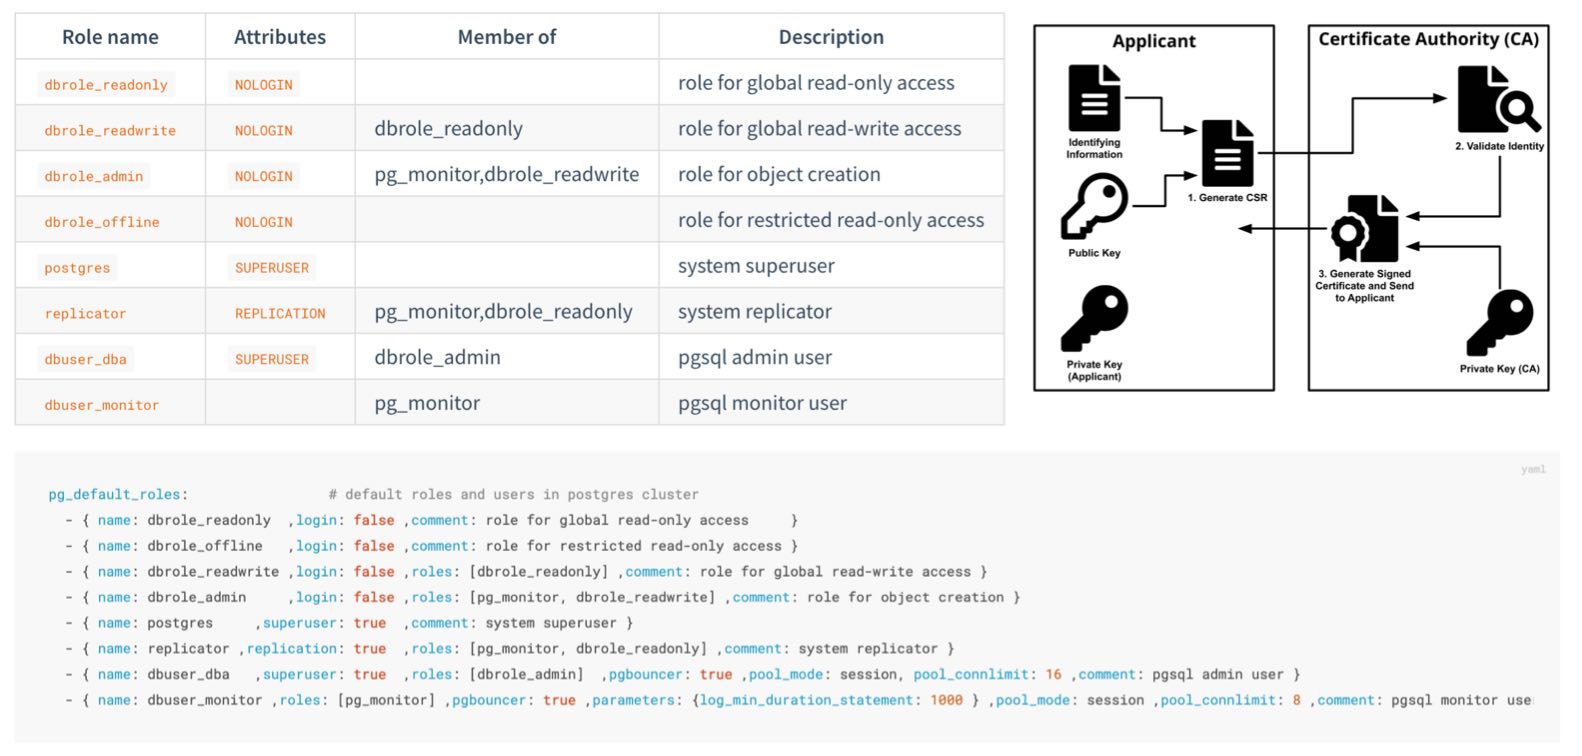
Role System
Pigsty creates four business roles by default. They form privilege groups and cannot log in:
| Role | Attribute | Inherits | Purpose |
|---|---|---|---|
dbrole_readonly | NOLOGIN | — | Global read-only access |
dbrole_readwrite | NOLOGIN | dbrole_readonly | Global DML access; the default choice for application accounts |
dbrole_admin | NOLOGIN | dbrole_readwrite, pg_monitor | Object creation and DDL for administration and release workflows |
dbrole_offline | NOLOGIN | — | Independent read-only role that can be restricted to offline instances through HBA |
Pigsty also creates four system users, each with a specific responsibility:
| User | Attribute | Purpose |
|---|---|---|
postgres | SUPERUSER | Database superuser; no password and local ident login only |
replicator | REPLICATION | Streaming replication and backup, with pg_monitor and read-only privileges |
dbuser_dba | SUPERUSER | Routine administration user that inherits dbrole_admin |
dbuser_monitor | — | Monitoring user with only pg_monitor and read-only privileges |
Application accounts join role groups through the roles field and inherit their privileges:
Customize the declarative role system through pg_default_roles. This parameter replaces the complete list. Retain all required system users and default roles. Also check references in HBA rules, default privileges, and scripts.
Default Privileges
Roles define who receives privileges. Default privileges give newly created objects the required grants automatically.
PostgreSQL provides ALTER DEFAULT PRIVILEGES. Pigsty declares these rules through pg_default_privileges:
The read-only role can query data and execute functions. The read-write role also has DML privileges. The administrator role adds privileges needed for object management.
Ownership Convention
Default privileges apply only to objects created by identities with those defaults configured. Pigsty configures them for:
- the database OS user
pg_dbsu, which defaults topostgres; - the administration user
pg_admin_username, which defaults todbuser_dba; dbrole_admin;- each database owner declared in
pg_databases.
Application DDL should normally run as the declared database owner. Administration and release workflows can use dbuser_dba or first run SET ROLE dbrole_admin. Other users need their own ALTER DEFAULT PRIVILEGES configuration. Otherwise, objects they create do not receive this default privilege model.
PostgreSQL default privileges follow the object creator. They do not propagate automatically from the database or session login name. This is PostgreSQL behavior, not a Pigsty limitation.
Database Isolation
By default, PostgreSQL grants database CONNECT to PUBLIC. If HBA permits it, a login role can enter a database it does not own. Restrict this default when multiple applications share a cluster.
Set revokeconn in a database definition to revoke public connection access:
This revokes CONNECT from PUBLIC. It grants access explicitly to the replication, monitoring, and administration users and the database owner. The owner receives GRANT OPTION and can grant access to others. Without additional grants or inherited roles, app_a cannot connect to app_b.
Cluster initialization also revokes CREATE from PUBLIC on the database and the public schema:
Ordinary users cannot freely create objects in public databases or schemas. This reduces risks from unsafe search_path settings and object shadowing. PostgreSQL 15 restricted the default CREATE privilege on the public schema. Pigsty applies this boundary to all supported major versions.
Offline Role and Instance Isolation
dbrole_offline provides independent read-only privileges for ETL, reporting, and ad hoc queries. It controls object access, not which instance accepts connections.
The default intranet HBA rule for +dbrole_offline has no role filter, so it applies to every instance. To restrict it to pg_role: offline or a replica with pg_offline_query: true, change the complete pg_default_hba_rules list:
pg_default_hba_rules replaces the entire list; do not use the example rule alone. HBA limits expensive queries to offline instances only if it filters by instance role. Users must also lack other inherited roles permitted by broader rules. Add a dedicated service endpoint, connection limits, and query resource controls for resource isolation.
Beyond the Database
Least privilege also applies at the host level:
- The
postgressuperuser has no password and permits only localidentlogin. Its sudo access defaults to required database service and log commands (pg_dbsu_sudo:limit). dbuser_monitorhaspg_monitor, the read-only role, and privileges on themonitorschema. By default, it cannot write business tables.replicatorreceives only directory function privileges needed for backup and recovery, without general superuser access.
Next
- 📖 Complete role and privilege reference: Access Control Configuration
- 🔑 Authentication: the first gate before authorization
- 🔒 Data Security: protection beyond privileges
7.4 - Encrypted Communication
TLS can provide transport encryption, server authentication, and client authentication. Configure each protection separately. Enabling server TLS does not make clients verify the server or make the server require client certificates.
Most TLS operational work involves certificate issuance, distribution, trust, and rotation. Without central management, services often skip verification or keep plaintext connections.
Pigsty manages PKI declaratively. Deployment creates a local self-signed CA, issues component certificates, and distributes trust. TLS is then ready for use.
Local CA
During initial deployment, Pigsty checks for a CA on the administration node. It creates one when required:
| File | Description | Permissions |
|---|---|---|
files/pki/ca/ca.key | CA private key and root of trust for the deployment; protect it carefully | 0600, with directory mode 0700 |
files/pki/ca/ca.crt | CA root certificate; safe to distribute | 0644 |
ca_createcontrols CA behavior. Pigsty reuses an existing key and certificate unchanged. If only the key exists, it issues a replacement certificate with that key.ca_create: falseprevents creation of a missing private key. Ifca.keyis absent, deployment stops instead of creating an unexpected trust root. Always back up and restoreca.keyandca.crttogether.ca_cnsets the certificate CN, defaultpigsty-ca. The key is RSA 4096.- The root CA is valid for 100 years. Component certificates default to 20 years (
cert_validity:7300d). The browser-facing Nginx certificate is an exception, with a current default of 397 days.
Long default lifetimes reduce initial maintenance for private infrastructure. Production still needs certificate rotation. Organizations with a certificate policy should shorten lifetimes and monitor expiration.
Trust Distribution
Every node must trust the CA. When managing a node, Pigsty copies the CA certificate to /etc/pki/ca.crt and links it into the OS trust store:
- EL family (RHEL, Rocky, Alma): link under
/etc/pki/ca-trust/source/anchors/and runupdate-ca-trust - Debian and Ubuntu: link under
/usr/local/share/ca-certificates/and runupdate-ca-certificates
Clients that use the OS trust store, such as curl, can then verify Pigsty CA certificates. The Nginx portal also publishes ca.crt at its site root for browsers and external clients.
By default, PostgreSQL libpq clients look for ~/.postgresql/root.crt and use sslmode=prefer. They do not directly use the OS trust store to verify server identity.
Server Identity Verification
Security-sensitive PostgreSQL clients should use sslmode=verify-full and specify the Pigsty CA:
verify-full checks the certificate chain and connection hostname. The server certificate SAN must contain the client’s DNS name or IP address. External clients must install ca.crt or specify it with sslrootcert.
Certificate Matrix
The local CA issues certificates for these components under one trust chain:
| Component | Certificate Identity (CN) | Deployment Path | Encryption State |
|---|---|---|---|
| PostgreSQL | <cluster>-<sequence> | /pg/cert/server.{crt,key} | Server-side SSL enabled by default; HBA determines whether it is mandatory |
| PgBouncer | Reuses the PostgreSQL certificate | /pg/cert/ | TLS disabled by default (pgbouncer_sslmode) |
| Patroni | Reuses the PostgreSQL certificate | /pg/cert/ | API HTTPS disabled by default (patroni_ssl_enabled) |
| etcd | <instance-name> | /etc/etcd/server.{crt,key} | TLS for client and peer traffic |
| Silo | <node-name> | ~minio/.minio/certs/ | Silo HTTPS is enabled by default (minio_https) |
| Kafka | <cluster>-<sequence> | /etc/kafka/pki/kafka.pem | SASL_SSL/SSL with kafka_security: scram; defaults to plaintext |
| MySQL | <instance-name> | /etc/mysql/pki/server.{crt,key} | Secure transport enforced; clients and group replication verify the certificate chain |
| Nginx | pigsty, with portal domains in SAN | /etc/nginx/conf.d/cert/ | HTTPS enabled by default (nginx_sslmode) |
| INFRA node | <node-name> | /etc/pki/infra.{crt,key} | Available to infrastructure components |
These defaults distinguish available TLS from enabled TLS:
- Enabled at deployment: PostgreSQL accepts SSL connections. etcd uses TLS for clients and peers.
- Encrypted by default: Object storage backup traffic through MINIO and Nginx web traffic use HTTPS.
- Available but disabled: Patroni API and PgBouncer TLS is disabled, with certificates already installed. Enable the corresponding parameters.
ha/safeenables both.
SSL support, mandatory encryption, and client verification of server identity are separate states. HBA enforces encryption with auth: ssl or cert. Client sslmode and trust settings control server verification. Default rules require TLS only for administrator connections from arbitrary sources. The safe template uses ssl or cert for main TCP rules. It retains local ident and selected localhost password rules.
Client Certificates
cert.yml issues client certificates. For HBA cert authentication, the certificate CN represents the database user name:
The files are files/pki/misc/<cn>.key and files/pki/misc/<cn>.crt. Deliver private keys through a controlled channel and allow only the corresponding user to read them. Client certificates let the server verify clients. The client must still use verify-full to verify the database server.
Using an Enterprise CA
Pigsty can issue certificates from an existing enterprise CA or an intermediate signed by its root. Put the certificate and private key at these paths. Playbooks reuse an existing CA:
Also set ca_create: false. Deployment then stops if the private key is missing, rather than creating a new trust root. However, an existing key with a missing certificate still causes certificate reissuance. Verify and restore both files together.
Key Protection and Rotation
- The CA private key exists only on the administration node. It and
pigsty.ymlare among the deployment’s highest-trust assets. Keep an offline backup. See Trust Boundaries. - If the CA key is compromised, establish a new trust root and reissue every component and client certificate. Plan a period of trust in both CAs to avoid interrupting all connections together.
- Component certificate sources reside at
files/pki/<component>/on the administration node. Node files are deployment copies. Deleting only a node copy restores the same certificate. To rotate, update or remove the source, rerun the relevant playbook, and reload or roll the component as required.
Next
- 🔑 Authentication: use HBA to decide who must use SSL or client certificates
- 🔒 Data Security: encryption for stored data and backups
- ✅ Compliance: evidence for certificate management
7.5 - Data Security
Network boundaries, authentication, and access control reduce incident risk. Data controls must limit damage and support recovery after hardware failure, leaked credentials, or operator errors.
Data security must provide integrity, recoverability, confidentiality if copied, and records of what happened.
Integrity
Bad disk sectors, memory bit flips, and firmware defects can cause silent data corruption, with no immediate error. Pigsty enables pg_checksum: true by default. Initialization uses data-checksums. PostgreSQL calculates each page checksum on write and checks it on read.
Page checksums mainly detect corruption in storage, the I/O path, or pages after writing. They cannot detect every memory error, logical error, or incorrect application write. They do not replace backups.
CRIT requires checksums regardless of the parameter. Its strict synchronous replication (synchronous_mode_strict) blocks writes needing synchronous acknowledgment when no synchronous replica is available. This protects acknowledged transactions under specific conditions. Clients must not reduce synchronous_commit; a synchronous replica must participate in commits. Failover must select a node containing the required WAL. Verify RPO with failure exercises on the target topology.
Recoverability
Replicas mainly handle node failures. Backups cover accidental deletion, logical errors, cluster corruption, and wider disasters. HA can shorten interruptions after primary failure. However, replication copies accidental deletions to every replica, so backups remain essential.
Pigsty enables pgBackRest by default through pgbackrest_enabled. Base backups and continuous WAL archives provide Point-in-Time Recovery. Restore to a target within the retained backup and WAL window.
Select the backup repository with pgbackrest_method:
| Repository | Location | Default Retention | Encryption |
|---|---|---|---|
local (default) | Local /pg/backup directory | Latest 2 full backups | None |
minio | Silo or external S3-compatible object storage | 14 days | AES-256-CBC |
Two additional controls reduce damage from accidental deletion:
- Delayed replica: For a critical cluster, declare
pg_delay: 1h. Before the error replays, pause replication and extract the required data. A delayed replica eventually catches up and does not replace backup. - Removal safeguards: Enabling
pg_safeguardoretcd_safeguardblocks the corresponding removal playbook. This reduces accidental cluster removal.
Test that backups can restore data through routine recovery exercises. See Backup and Recovery for mechanisms and procedures.
Confidentiality
Protect data at rest at three layers:
Backup encryption. pgbackrest_method: minio selects S3-compatible storage. Providers include MINIO-managed Silo, independently managed MinIO or RustFS, and external S3 services. The preset enables AES-256-CBC encryption. Change its public pgBackRest passphrase in production. ha/safe derives an example passphrase from the cluster name:
pgBR.${pg_cluster} is predictable, and configure -g does not replace it. In production, use a unique random passphrase. Store it separately from the backup. Without it, recovery is impossible.
Local backups have no encryption by default. Encryption reduces disclosure if someone copies backup files or media separately. Protection is limited when keys and backups share a host.
Transport encryption. Uploads to Silo or external S3 use HTTPS. HBA can require SSL for PostgreSQL clients and replication. Clients should also verify server certificates. See Encrypted Communication.
Encryption at rest. Upstream PostgreSQL currently lacks general built-in transparent data encryption (TDE). Pigsty offers two options. Use pg_tde with Percona Distribution for PostgreSQL for table-level encryption; see pgtde. Use security extensions such as pgsodium, pgcrypto, and anonymizer for column encryption and masking. The safe template installs this category. Full-disk encryption, such as LUKS or dm-crypt, adds OS-level protection against stolen media.
Audit and Traceability
Incident records must identify who did what and when. Pigsty provides these logging layers:
Default baseline: Log all DDL with log_statement: ddl. Log statements longer than 100 ms with log_min_duration_statement: 100. PostgreSQL 18 and later also record connection authorization.
CRIT template: log_connections and log_disconnections record connection events. PostgreSQL 18 can distinguish receipt, authentication, and authorization.
pgaudit: Install pgaudit and preload it through pg_libs for detailed statement auditing. This includes object reads, writes, and role-based audit classes. The safe template installs the extension. Declare loading and audit policy explicitly.
With INFRA logging enabled and Vector configured, PostgreSQL logs go to VictoriaLogs for centralized storage. Retention defaults to 15 days and can meet other compliance periods. Logs and metrics support search, alerts, and incident reconstruction. Classification, response, and evidence preservation still require an operational process.
Next
- ⏰ Backup and Recovery: PITR principles and practice
- ♾️ High Availability: replicas and backups as complementary safeguards
- ✅ Compliance: audit logs as compliance evidence
7.6 - Compliance
Compliance requires continuous evidence of three elements:
- Configuration: Security controls must be enabled. Pigsty directly provides configuration.
- Process: The organization must establish access approval, change management, recovery exercises, and related procedures.
- Evidence: Records must show that configuration and processes remain effective. The inventory, runtime logs, and monitoring system provide part of this evidence.
This page provides a pre-launch checklist and maps Pigsty capabilities to common compliance frameworks. These mappings support architecture and gap analysis. They are not an MLPS assessment, SOC 2 audit opinion, or legal advice.
Default Credentials Checklist
Default credentials are public in documentation and source code. Use them only for demonstrations and local development. Change every applicable default before production or network-exposed deployment:
| Scope | Example Default | configure -g |
|---|---|---|
| Grafana administrator and viewer | pigsty, DBUser.Viewer | Yes |
| HAProxy administration interface | pigsty | Yes |
| PostgreSQL administration, monitoring, and replication users | DBUser.DBA, DBUser.Monitor, DBUser.Replicator | Yes |
| Patroni REST API | Patroni.API | Yes |
| etcd root | Etcd.Root | Yes |
| MINIO module object-storage root | S3User.MinIO | Yes |
| Object-storage backup and example application users | S3User.Backup, S3User.Meta, S3User.Data | Yes |
| Example database users | DBUser.Meta, DBUser.Supa, Vibe.Coding | Yes |
| pgBackRest encryption passphrase | cipher_pass: pgBackRest | No |
Silo users and pgBR.${pg_cluster} in ha/safe | Template example values | No |
| User-defined credentials | Custom values | No |
Use -g to randomize built-in parameters and example strings recognized by the configuration wizard:
The wizard prints generated passwords to the terminal. Protect terminal history and automation logs as sensitive data. Then inspect the configuration. Replace pgBackRest cipher_pass, uncovered MINIO values in ha/safe, and all custom credentials.
Launch Hardening Checklist
Before deployment:
- Define the network boundary. Do not expose database ports publicly. Remove the demo firewall exception for
5432. - Select the built-in CA or enterprise PKI. See Using an Enterprise CA.
- Plan client verification. Set
sslmode=verify-fulland a trusted CA on database clients. - Assign application accounts through the four-tier roles. Declare
expire_in. - Plan the backup repository, retention, encryption passphrase, and off-site copies.
- Decide whether to use
ha/safeand the CRIT parameter template.
After deployment:
- Confirm that all default credentials have changed. Include values covered by
configure -gand uncovered backup, object storage, and custom credentials. - Compare
/pg/data/pg_hba.confwith the declared HBA policy and intended access boundary. - Query effective users, roles, default privileges, and database
CONNECTgrants. Compare them with the inventory. - Run a full backup and recovery exercise to validate the backup path.
- Confirm log collection, monitoring alerts, and notification channels.
Periodically:
- Audit privileges: compare
pg_usersdeclarations with effective grants, and remove expired or departed-user accounts - Rotate credentials and certificates
- Exercise recovery and failover
- Track security updates for Pigsty and upstream components
Compliance Evidence
Use declarative configuration as a starting point for audit evidence. Retain runtime state to prove that the configuration was applied and remains effective.
| Evidence | Source |
|---|---|
| Security baseline and change history | The pigsty.yml inventory and Git history |
| Access-control matrix | pg_default_roles, pg_users, and pg_hba_rules declarations |
| Effective authentication policy | Rendered pg_hba.conf on each instance, compared with declarations to detect drift |
| Effective users and privileges | PostgreSQL catalogs, database ACLs, \du+, and \ddp+ |
| Operation and connection logs | PostgreSQL DDL, slow-query, and connection logs retained in VictoriaLogs |
| Backup records | pgBackRest information and monitoring dashboards |
| Security incidents and alerts | Monitoring alert history |
| Certificate inventory | files/pki/ and deployed component certificates |
MLPS Level 3 Mapping
This table maps database-related capabilities to the secure computing environment controls in GB/T 22239-2019 Level 3:
| Control | Pigsty Capability | Additional Requirement |
|---|---|---|
| Unique identity | Independent accounts and SCRAM-SHA-256 password storage | Real-name account management process |
| Password complexity and rotation | passwordcheck, credcheck, and expire_in | Enable extensions and establish a rotation process |
| Login failure handling | Can be implemented with credcheck and related extensions | Enable and configure as required |
| Access control and least privilege | Four-tier roles, default privileges, and database isolation | Privilege approval workflow |
| Security audit | DDL, connection, and slow-query logs; pgaudit; centralized retention | CRIT or manual connection logging; required retention period |
| Communication confidentiality | Local CA and TLS; HBA-enforced ssl or cert | Enforce TLS, client verify-full, and certificate rotation |
| Data integrity | Page checksums by default and strict synchronous replication with CRIT | Storage protection, defined failure model, and exercises |
| Data confidentiality | AES-encrypted backup plus TDE and column-encryption options | Enable as required |
| Backup and recovery | pgBackRest, PITR, and a remote S3-compatible repository | Recovery exercise process |
| Residual information protection | — | Media destruction and erasure process |
MLPS also covers physical security, networks, and management systems beyond a database distribution. Pigsty supports database-related technical controls. The overall system must address facilities, network devices, and governance.
SOC 2 Mapping
Database-related controls in the SOC 2 Trust Services Criteria (TSC) include:
| Criterion | Pigsty Capability | Additional Requirement |
|---|---|---|
| CC6.1 Logical access security | HBA, RBAC, default privileges, and database isolation | Privilege design, approval, and periodic review |
| CC6.2 User registration and authorization | Declarative users, roles, and expiration | Joiner, mover, leaver, and identity-verification process |
| CC6.3 Access changes and revocation | pg_users, role changes, REVOKE, and expiration | Tickets, approval evidence, and timely revocation |
| CC6.6 External boundary threats | Firewalls, listen addresses, HBA, and restricted management ingress | Network architecture, boundary devices, and continuous validation |
| CC6.7 Information transmission and movement | TLS, client verification, and backup encryption | Policies for exports, media, and third-party transfer |
| CC7.2 System monitoring | Victoria observability stack with extensive metrics and alerts | Alert-response process |
| CC7.3 Incident traceability | Centralized logs and audit extensions | Log-review process |
| A1.2 Availability and recovery | High Availability and PITR | Exercise records and RTO/RPO objectives |
Supply Chain and Vulnerability Response
Compliance reviews also cover the software supply chain. Pigsty provides these distribution and response controls:
Package integrity: Pigsty repository RPM and DEB packages (repo.pigsty.io, repo.pigsty.cc) are GPG-signed. Verify fingerprint 9592 A7BC 7A68 2E73 3337 6E09 E793 5D8D B9BD 8B20 (B9BD8B20) before trusting the key. Deployment-generated repository definitions and the INFRA node local repository do not enforce verification for every package by default. In production, review package-manager trust and signature settings.
Vulnerability response: Report issues privately through GitHub vulnerability reporting or email as specified in SECURITY.md. The project targets acknowledgment within three business days and initial assessment within seven days.
Version support: Security fixes ship in the latest stable release. Update to receive them. Subscription services provide extended support for users who must retain a version longer.
Next
- 🛡️ Security Model: from the default baseline to hardening levels
- 🔰 Security Recommendations: minimum hardening for quick-start deployments
- 📄
ha/safeTemplate: hardening configuration example