This is the multi-page printable view of this section. .
ER Model
- 1: E-R Model of Infra Cluster
- 2: E-R Model of PostgreSQL Cluster
- 3: E-R Model of Etcd Cluster
- 4: MINIO Cluster Model
- 5: E-R Model of Redis Cluster
A deployment is the largest entity in Pigsty. This entity-relationship diagram shows its main entities and their relationships:
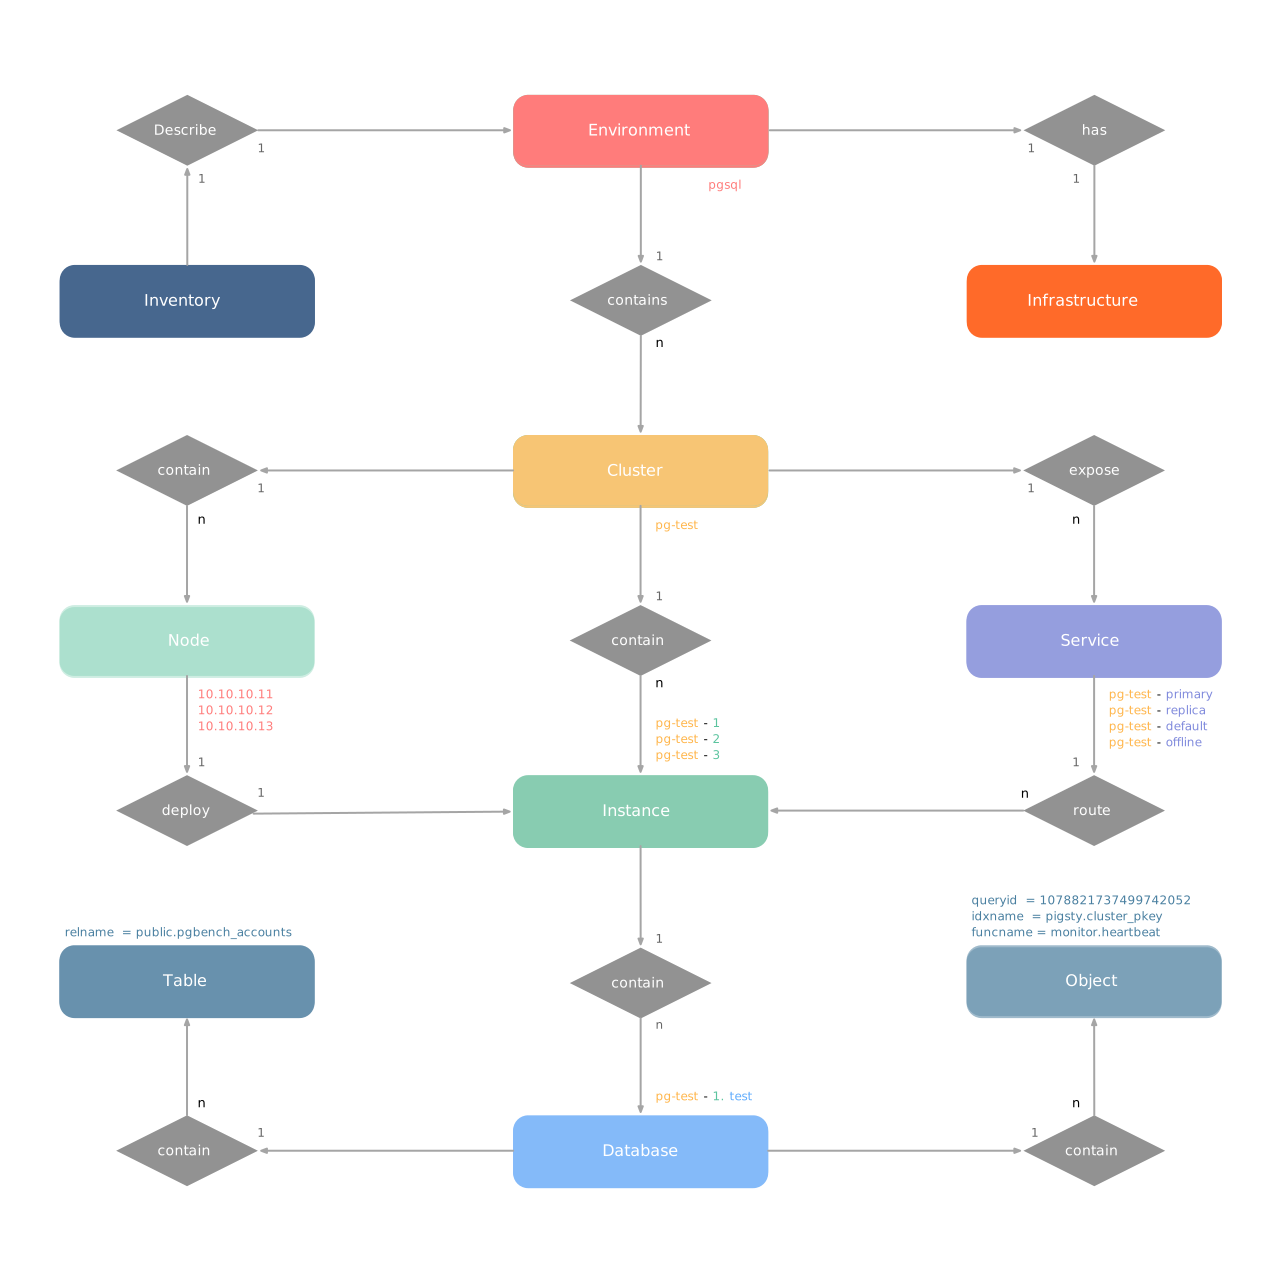
A deployment is also an environment. Examples include Production (Prod), User Acceptance Testing (UAT), Staging, Testing, and Development (Devbox). Each environment has a Pigsty inventory that describes all its entities and attributes.
An environment usually has shared infrastructure (INFRA). This includes ETCD for the HA DCS and MINIO for centralized backup storage. Infrastructure serves multiple PostgreSQL clusters and other database modules. Deployments without infrastructure are also possible.
Pigsty organizes almost all database modules into clusters. Each cluster is an Ansible group with node resources. PostgreSQL HA, Redis, Etcd, and Silo use this model. An environment can contain multiple clusters.
1 - E-R Model of Infra Cluster
The INFRA module is a management hub made of infrastructure nodes, rather than a traditional cluster. It provides core services for the deployment. Each node is an autonomous service unit that runs components such as Nginx, Grafana, and VictoriaMetrics. Together, these nodes provide observability and management for database clusters.
There are two core entities in Pigsty’s INFRA module:
- Node: A server that runs infrastructure components. It can be a physical server, VM, container, or Pod.
- Component: An infrastructure service on a node, such as Nginx, Grafana, or VictoriaMetrics.
INFRA nodes usually also serve as administration nodes, which form the Pigsty control plane.
Component Composition
Each INFRA node runs the following core components:
| Component | Port | Description |
|---|---|---|
| Nginx | 80/443 | Web portal, local repo, unified reverse proxy |
| Grafana | 3000 | Visualization platform, dashboards, data apps |
| VictoriaMetrics | 8428 | Time-series database, Prometheus API compatible |
| VictoriaLogs | 9428 | Log database, receives structured logs from Vector |
| VictoriaTraces | 10428 | Trace storage for slow SQL / request tracing |
| VMAlert | 8880 | Alert rule evaluator based on VictoriaMetrics |
| Alertmanager | 9059 | Alert aggregation and dispatch |
| Blackbox Exporter | 9115 | ICMP/TCP/HTTP black-box probing |
| DNSMASQ | 53 | DNS server for internal domain resolution |
| Chronyd | 123 | NTP time server |
These components together form Pigsty’s observability infrastructure.
Examples
This example defines a two-node INFRA deployment:
The configuration defines these entities:
| Group | Description |
|---|---|
infra | INFRA infrastructure node group |
| Node | Description |
infra-1 | 10.10.10.10 INFRA node #1 |
infra-2 | 10.10.10.11 INFRA node #2 |
For production, use at least two INFRA nodes for component redundancy.
Identity Parameters
The INFRA_ID parameter group assigns deterministic identities to INFRA entities. One parameter is required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
infra_seq | int | Node | INFRA node sequence, required | Natural number, starting from 1, unique within group |
Set the node sequence number at node level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Node | infra-{{ infra_seq }} | infra-1, infra-2 |
INFRA assigns infra-N identifiers to distinguish infrastructure nodes in monitoring. This does not change their hostname or system identity. Nodes retain their existing hostname or IP address for identification.
Service Portal
INFRA nodes provide web access through Nginx. infra_portal defines the services that Nginx exposes.
The default configuration only defines the home server:
Pigsty configures reverse proxy endpoints for enabled components, including Grafana, VictoriaMetrics, and AlertManager. To access them through separate domains, add explicit configuration:
| Domain | Service | Description |
|---|---|---|
i.pigsty | Home | Pigsty homepage |
g.pigsty | Grafana | Monitoring dashboard |
p.pigsty | VictoriaMetrics | TSDB Web UI |
a.pigsty | Alertmanager | Alert management UI |
Use domain names to access Pigsty services where possible, instead of an IP address and port.
Deployment Scale
The number of INFRA nodes depends on deployment scale and HA requirements:
| Scale | INFRA Nodes | Description |
|---|---|---|
| Dev/Test | 1 | Single-node deployment, all on one node |
| Small Prod | 1-2 | Single or dual node, can share with other services |
| Medium Prod | 2-3 | Dedicated INFRA nodes, redundant components |
| Large Prod | 3+ | Multiple INFRA nodes, component separation |
In a single-node deployment, INFRA shares a node with PGSQL, ETCD, and other modules. Small deployments usually use INFRA nodes as the administration node, backup administration node, and local software repository (/www/pigsty). Larger deployments can assign these responsibilities to dedicated nodes.
Monitoring Label System
Pigsty collects metrics from INFRA components themselves. Unlike database modules, INFRA treats each component as a separate monitoring object. The cls (class) label distinguishes component types.
| Label | Description | Example |
|---|---|---|
cls | Component type, each forming a “class” | nginx |
ins | Instance name, format {component}-{infra_seq} | nginx-1 |
ip | INFRA node IP running the component | 10.10.10.10 |
job | VictoriaMetrics scrape job, fixed as infra | infra |
A two-node INFRA deployment with infra_seq: 1 and infra_seq: 2 uses these component labels:
| Component | cls | ins Example | Port |
|---|---|---|---|
| Nginx | nginx | nginx-1, nginx-2 | 9113 |
| Grafana | grafana | grafana-1, grafana-2 | 3000 |
| VictoriaMetrics | vmetrics | vmetrics-1, vmetrics-2 | 8428 |
| VictoriaLogs | vlogs | vlogs-1, vlogs-2 | 9428 |
| VictoriaTraces | vtraces | vtraces-1, vtraces-2 | 10428 |
| VMAlert | vmalert | vmalert-1, vmalert-2 | 8880 |
| Alertmanager | alertmanager | alertmanager-1, alertmanager-2 | 9059 |
| Blackbox | blackbox | blackbox-1, blackbox-2 | 9115 |
All INFRA component metrics have job="infra". The cls label distinguishes components:
2 - E-R Model of PostgreSQL Cluster
PGSQL organizes PostgreSQL as clusters. Each cluster is a logical group of database instances connected through primary-replica relationships.
Each cluster is an autonomous business unit with at least one primary instance. It exposes database capabilities through services.
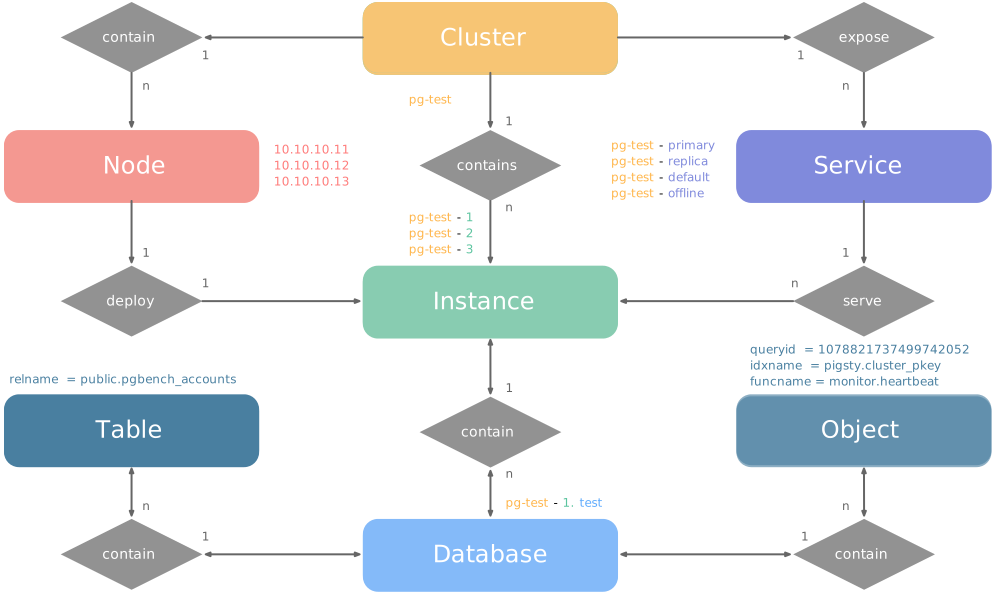
There are four core entities in Pigsty’s PGSQL module:
- Cluster: An autonomous PostgreSQL business unit and the top-level namespace for other entities.
- Service: A named abstraction that exposes capabilities and routes traffic through node ports.
- Instance: One PostgreSQL server, including its running processes and database files, on one node.
- Node: A hardware resource that runs Linux and Systemd. It can be a physical server, VM, container, or Pod.
Two business entities, Database and Role, complete this logical model:
Examples
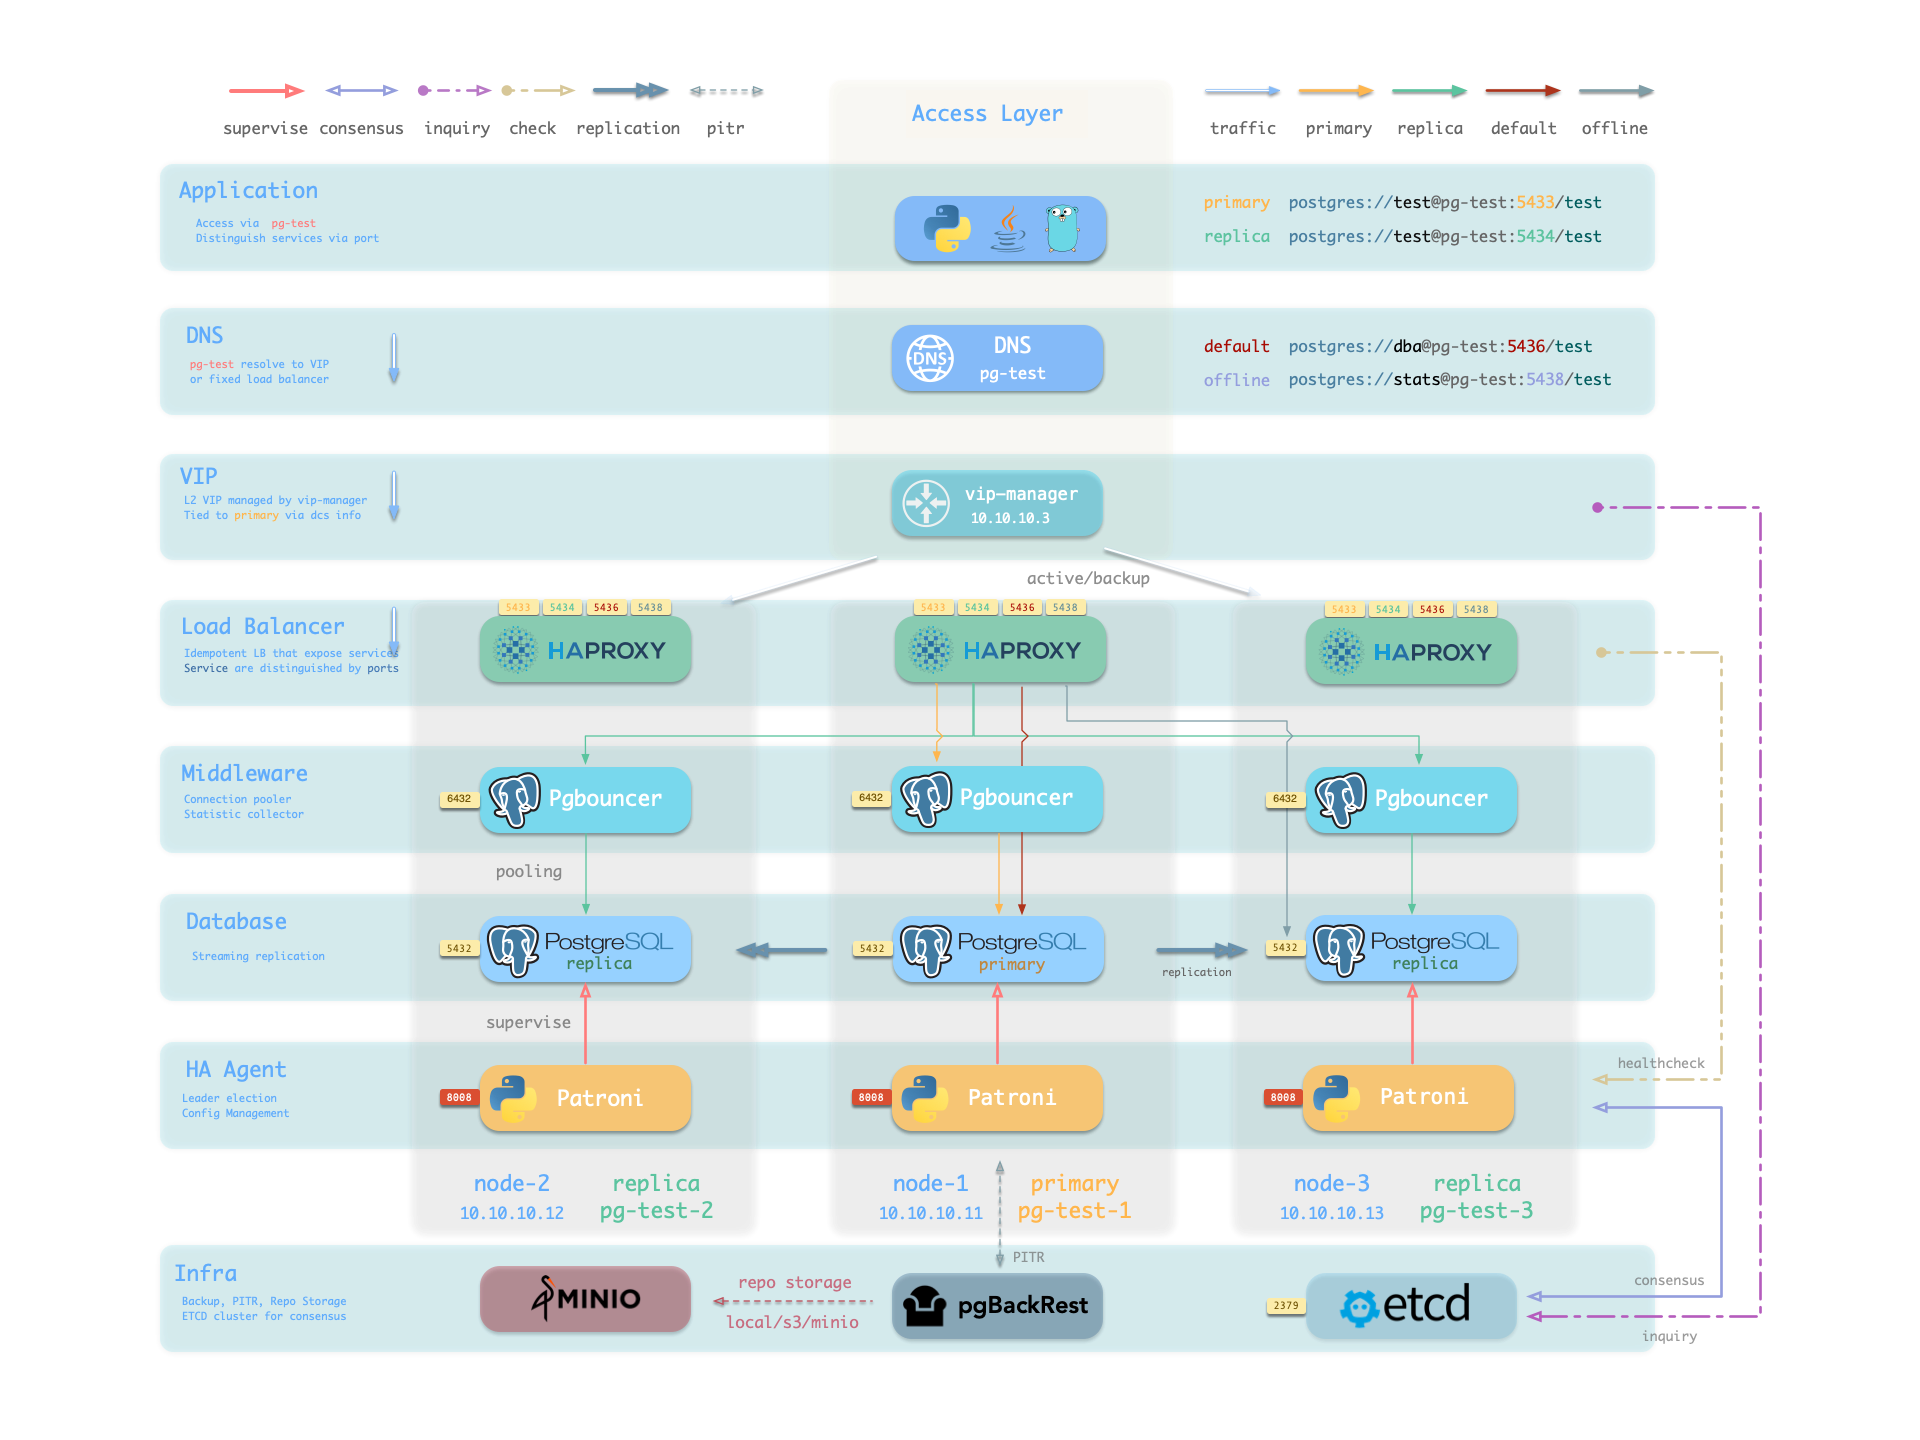
The following two examples show the model. The four-node Pigsty sandbox contains a three-node pg-test cluster:
This configuration defines a high-availability PostgreSQL cluster with these entities:
| Cluster | Description |
|---|---|
pg-test | PostgreSQL 3-node HA cluster |
| Instance | Description |
pg-test-1 | PostgreSQL instance #1, default primary |
pg-test-2 | PostgreSQL instance #2, initial replica |
pg-test-3 | PostgreSQL instance #3, initial replica |
| Service | Description |
pg-test-primary | Read-write service (routes to primary pgbouncer) |
pg-test-replica | Read-only service (routes to replica pgbouncer) |
pg-test-default | Direct read-write service (routes to primary postgres) |
pg-test-offline | Offline read service (routes to dedicated postgres) |
| Node | Description |
node-1 | 10.10.10.11 Node #1, hosts pg-test-1 PG instance |
node-2 | 10.10.10.12 Node #2, hosts pg-test-2 PG instance |
node-3 | 10.10.10.13 Node #3, hosts pg-test-3 PG instance |
Identity Parameters
The PG_ID parameter group assigns deterministic identities to PGSQL entities. Three parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
pg_cluster | string | Cluster | PG cluster name, required | Valid DNS name, regex [a-zA-Z0-9-]+ |
pg_seq | int | Instance | PG instance number, required | Natural number, starting from 0 or 1, unique within cluster |
pg_role | enum | Instance | PG instance role, required | Enum: primary, replica, offline |
Set the cluster name at cluster level. Set each instance number and role at instance level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ pg_cluster }}-{{ pg_seq }} | pg-test-1, pg-test-2, pg-test-3 |
| Service | {{ pg_cluster }}-{{ pg_role }} | pg-test-primary, pg-test-replica, pg-test-offline |
| Node | Explicitly specified or borrowed from PG | pg-test-1, pg-test-2, pg-test-3 |
Pigsty uses an exclusive 1:1 mapping between nodes and PostgreSQL instances. By default, the node inherits its PostgreSQL instance identifier through node_id_from_pg. Set nodename to override this name. Alternatively, disable nodename_overwrite to retain the current default.
Sharding Identity Parameters
To serve one business with multiple PostgreSQL clusters (sharding), use two additional identity parameters: pg_shard and pg_group.
These clusters share one pg_shard name. Each has its own pg_group number, as in this Citus cluster:
A pg_cluster name usually combines {{ pg_shard }}{{ pg_group }}, for example pg-citus0 or pg-citus1.
Pigsty has dedicated dashboards for horizontally sharded clusters. Use this naming convention to compare shard performance and load in those dashboards.
Other identity parameters support specific uses:
pg_upstream: Set the upstream for a backup cluster or cascading replication.gp_role: Identify a Greenplum cluster role.pg_exporters: Define external monitoring instances.pg_offline_query: Define offline query instances.
See the PG_ID parameter documentation.
Monitoring Label System
The built-in monitoring system uses these identity parameters to identify PostgreSQL entities.
The labels cls, ins, and ip identify the cluster name, instance name, and node IP. They accompany job in all native VictoriaMetrics metrics and VictoriaLogs log streams.
These job values are fixed:
pgsql: PostgreSQL metrics.pgrds: Remote PostgreSQL instance metrics.postgres: PostgreSQL CSV logs.pgbackrest: pgBackRest logs.
Other PostgreSQL components collect logs through job: syslog.
Specific entity metrics also have these identity labels:
datname: Database name, if a metric belongs to a specific database.relname: Table name, if a metric belongs to a specific table.idxname: Index name, if a metric belongs to a specific index.funcname: Function name, if a metric belongs to a specific function.seqname: Sequence name, if a metric belongs to a specific sequence.query: Query fingerprint, if a metric belongs to a specific query.
3 - E-R Model of Etcd Cluster
The ETCD module organizes production ETCD into clusters. A cluster is a logical entity whose ETCD instances coordinate through the Raft consensus protocol.
Each cluster is an autonomous distributed key-value store with at least one ETCD instance. It provides services through client ports.
There are three core entities in Pigsty’s ETCD module:
- Cluster: An autonomous ETCD service unit and the top-level namespace for other entities.
- Instance: One ETCD server process on a node, participating in Raft consensus.
- Node: An implicitly declared hardware resource that runs Linux and Systemd.
The ETCD model has no Service entities or complex Role distinctions, unlike PostgreSQL. All ETCD instances are functionally equivalent. Raft elects one Leader; the others become Followers. Non-voting Learner members are also permitted during intermediate scale-out states.
Examples
This example defines a three-node ETCD cluster:
The configuration defines these entities:
| Cluster | Description |
|---|---|
etcd | ETCD 3-node HA cluster |
| Instance | Description |
etcd-1 | ETCD instance #1 |
etcd-2 | ETCD instance #2 |
etcd-3 | ETCD instance #3 |
| Node | Description |
10.10.10.10 | Node #1, hosts etcd-1 instance |
10.10.10.11 | Node #2, hosts etcd-2 instance |
10.10.10.12 | Node #3, hosts etcd-3 instance |
Identity Parameters
The ETCD parameter group assigns deterministic identities to ETCD entities. Two parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
etcd_cluster | string | Cluster | ETCD cluster name, required | Valid DNS name, defaults to fixed etcd |
etcd_seq | int | Instance | ETCD instance number, required | Natural number, starting from 1, unique within cluster |
Set the cluster name at cluster level and the instance number at instance level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ etcd_cluster }}-{{ etcd_seq }} | etcd-1, etcd-2, etcd-3 |
ETCD does not assign a separate identity to host nodes. It uses their existing hostname or IP address.
Ports & Protocols
Each ETCD instance listens on the following two ports:
| Port | Parameter | Purpose |
|---|---|---|
| 2379 | etcd_port | Client port, accessed by Patroni, vip-manager, etc. |
| 2380 | etcd_peer_port | Peer communication port, used for Raft consensus |
ETCD clusters enable TLS encryption and RBAC authentication by default. Clients need the correct certificates and passwords to access ETCD.
Cluster Size
ETCD cluster size determines availability. More than half the nodes, called a quorum, must be alive to maintain this distributed coordination service.
| Cluster Size | Quorum | Fault Tolerance | Use Case |
|---|---|---|---|
| 1 node | 1 | 0 | Dev, test, demo |
| 3 nodes | 2 | 1 | Small-medium production |
| 5 nodes | 3 | 2 | Large-scale production |
ETCD supports even member counts. However, they tolerate no more failures than the next smaller odd count. They also increase deployment and quorum costs. Production clusters therefore usually have one, three, or five members. Clusters with more than five members are uncommon.
Monitoring Label System
The built-in monitoring system uses these identity parameters to identify ETCD entities.
The labels cls, ins, and ip identify the cluster name, instance name, and node IP. They accompany job in all ETCD metrics collected by VictoriaMetrics. The ETCD metrics job is always etcd.
4 - MINIO Cluster Model
MINIO is the compatibility module name for object storage. Pigsty v4.5.0 deploys Silo with minio_type: silo. It groups object storage instances into a cluster.
Each cluster is an autonomous S3-compatible object store with at least one instance. It exposes services through the S3 API port.
There are three core entities in Pigsty’s MINIO module:
- Cluster: An autonomous object storage service unit and the top-level namespace for other entities.
- Instance: One Silo server process on a node, managing local disks.
- Node: An implicitly declared hardware resource that runs Linux and Systemd.
Silo also retains the Storage Pool concept for expansion.
Deployment Modes
Silo supports Pigsty’s three inventory deployment modes:
| Mode | Code | Description | Use Case |
|---|---|---|---|
| Single-Node Single-Drive | SNSD | Single node, single data directory or disk | Dev, test, demo |
| Single-Node Multi-Drive | SNMD | Single node, multiple disks, typically 4+ | Resource-constrained small deployments |
| Multi-Node Multi-Drive | MNMD | Multiple nodes, multiple disks per node | Production recommended |
For a quick SNSD experiment, you can use a regular directory. For multiple drives, use real disk mount points. Otherwise, Silo refuses to start.
Examples
This example explicitly selects Silo, the current default backend, and defines a four-node cluster with multiple drives:
The configuration defines four Silo nodes with four disks each. Instance identifiers retain MINIO compatibility names:
| Cluster | Description |
|---|---|
minio | Silo 4-node HA cluster |
| Instance | Description |
minio-1 | Object-storage instance #1, managing 4 disks |
minio-2 | Object-storage instance #2, managing 4 disks |
minio-3 | Object-storage instance #3, managing 4 disks |
minio-4 | Object-storage instance #4, managing 4 disks |
| Node | Description |
10.10.10.10 | Node #1, hosts minio-1 instance |
10.10.10.11 | Node #2, hosts minio-2 instance |
10.10.10.12 | Node #3, hosts minio-3 instance |
10.10.10.13 | Node #4, hosts minio-4 instance |
Identity Parameters
The MINIO parameter group assigns deterministic identities to MINIO entities. Two parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
minio_cluster | string | Cluster | Object-storage cluster name, required | Valid non-empty name, no default |
minio_seq | int | Instance | Object-storage instance number, required | Natural number, starting from 1, unique within cluster |
Set the cluster name at cluster level and the instance number at instance level. Pigsty generates unique identifiers with these rules:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ minio_cluster }}-{{ minio_seq }} | minio-1, minio-2, minio-3, minio-4 |
MINIO uses the existing hostname or IP address as the host node identity. It does not assign another identity. minio_node generates internal Silo node names for cluster discovery in /etc/hosts. These names do not identify the host node.
Roles find members throughout the inventory by minio_cluster. The Ansible group name can differ from the cluster name. The retained backend selector minio_type currently must be silo.
Core Configuration Parameters
These parameters are also critical for Silo cluster configuration:
| Parameter | Type | Description |
|---|---|---|
minio_type | enum | Retained selector; currently only silo |
minio_data | path | Data directory, use {x...y} for multi-drive |
minio_node | string | Node name pattern for multi-node deployment |
minio_domain | string | Service domain, defaults to sss.pigsty |
These parameters determine minio_volumes, which the role writes to Silo’s MINIO_VOLUMES:
- SNSD: Direct
minio_datavalue, e.g.,/data/minio - SNMD: Expanded
minio_datadirectories, e.g.,/data{1...4} - MNMD: Combined
minio_nodeandminio_data, e.g.,https://minio-{1...4}.pigsty:9000/data{1...4}
Ports & Services
Each object-storage instance listens on the following ports:
| Port | Parameter | Purpose |
|---|---|---|
| 9000 | minio_port | S3 API service port |
| 9001 | minio_admin_port | Web admin console port |
MINIO enables HTTPS by default through minio_https. For the default pgBackRest S3 repository configuration, keep HTTPS enabled and install the Pigsty CA correctly.
Clients can reach a multi-node Silo cluster through any member. For a stable entry point, use a load balancer such as HAProxy with a VIP.
Resource Provisioning
After deployment, Pigsty creates these Silo resources. minio_provision controls this step:
Default Buckets (defined by minio_buckets):
| Bucket | Purpose |
|---|---|
pgsql | PostgreSQL pgBackREST backup storage |
meta | Metadata storage, versioning enabled |
data | General data storage |
Default Users (defined by minio_users):
| User | Default Password | Policy | Purpose |
|---|---|---|---|
pgbackrest | S3User.Backup | pgsql | PostgreSQL backup dedicated user |
s3user_meta | S3User.Meta | meta | Access meta bucket |
s3user_data | S3User.Data | data | Access data bucket |
These public default credentials are only for demonstrations and local development. Replace them before production deployment.
pgbackrest serves PostgreSQL cluster backups. The reserved users s3user_meta and s3user_data are not actively used.
Monitoring Label System
Pigsty uses these identity parameters to identify object storage entities. This example shows a Silo availability series:
cls, ins, and ip identify the cluster name, instance name, and node IP. For monitoring compatibility, job="minio" remains unchanged. The current backend label is flavor=silo. See the metric list for details.
5 - E-R Model of Redis Cluster
The Redis module organizes production Redis into clusters. A cluster is a logical entity with Redis instances on one or more nodes.
Each cluster is an autonomous, high-performance cache or storage unit with at least one Redis instance. It exposes services through ports.
There are three core entities in Pigsty’s Redis module:
- Cluster: An autonomous Redis service unit and the top-level namespace for other entities.
- Instance: One Redis server process using a specific port on a node.
- Node: An implicitly declared hardware resource that runs Linux and Systemd. It can host multiple Redis instances.
Redis usually runs multiple instances per node, unlike PostgreSQL. This uses multiple CPU cores on a physical server or VM. Nodes and instances therefore have a 1:N relationship. For production, Redis instances with more than 12 GB of memory are generally discouraged.
Operating Modes
redis_mode selects one of three Redis modes:
| Mode | Code | Description | HA Mechanism |
|---|---|---|---|
| Standalone | standalone | Classic master-replica, default mode | Requires Sentinel |
| Sentinel | sentinel | HA monitoring and auto-failover for standalone | Multi-node quorum |
| Native Cluster | cluster | Redis native distributed cluster, no sentinel needed | Built-in auto-failover |
- Standalone: The default mode. Set replication with
replica_of. HA requires a separate Sentinel cluster. - Sentinel: Monitor standalone clusters and provide automatic failover. Sentinel stores no business data. Multiple nodes provide HA for Sentinel itself.
- Native Cluster: Automatically shard data across multiple primaries. Each primary can have multiple replicas. Built-in HA removes the need for Sentinel.
Examples
The following examples show each mode.
Standalone Cluster
Classic master-replica on a single node:
| Cluster | Description |
|---|---|
redis-ms | Redis standalone cluster |
| Node | Description |
redis-ms-1 | 10.10.10.10 Node #1, hosts 2 instances |
| Instance | Description |
redis-ms-1-6379 | Primary instance, listening on port 6379 |
redis-ms-1-6380 | Replica instance, port 6380, replicates from 6379 |
Sentinel Cluster
This example puts three Sentinel instances on one node. redis_sentinel_monitor specifies the standalone clusters they monitor:
Native Cluster
This native distributed cluster has two nodes and six instances: the minimum specification of three primaries and three replicas.
This creates a 3 primary 3 replica native Redis cluster.
| Cluster | Description |
|---|---|
redis-test | Redis native cluster (3P3R) |
| Instance | Description |
redis-test-1-6379 | Instance on node 1, port 6379 |
redis-test-1-6380 | Instance on node 1, port 6380 |
redis-test-1-6381 | Instance on node 1, port 6381 |
redis-test-2-6379 | Instance on node 2, port 6379 |
redis-test-2-6380 | Instance on node 2, port 6380 |
redis-test-2-6381 | Instance on node 2, port 6381 |
| Node | Description |
redis-test-1 | 10.10.10.12 Node #1, hosts 3 instances |
redis-test-2 | 10.10.10.13 Node #2, hosts 3 instances |
Identity Parameters
The REDIS parameter group assigns deterministic identities to Redis entities. Three parameters are required:
| Parameter | Type | Level | Description | Format |
|---|---|---|---|---|
redis_cluster | string | Cluster | Redis cluster name, required | Valid DNS name, regex [a-z][a-z0-9-]* |
redis_node | int | Node | Redis node number, required | Natural number, starting from 1, unique within cluster |
redis_instances | dict | Node | Redis instance definition, required | JSON object, key is port, value is instance config |
Set the cluster name at cluster level. Set the node number and instance definitions at node level. Pigsty generates these unique identifiers:
| Entity | Generation Rule | Example |
|---|---|---|
| Instance | {{ redis_cluster }}-{{ redis_node }}-{{ port }} | redis-ms-1-6379, redis-ms-1-6380 |
Redis uses the existing hostname or IP address as the host node identity. It does not assign another identity. redis_node names instances, not host nodes.
Instance Definition
redis_instances is a JSON object. Each key is a port number; its value is the instance configuration:
Each Redis instance must use a unique port on its node. Avoid reserved ports below 1024 and conflicts with Pigsty ports. In standalone mode, replica_of defines replication. Use format '<ip> <port>' to specify the upstream primary address and port.
Each Redis node also runs Redis Exporter to collect metrics from all local instances:
| Port | Parameter | Purpose |
|---|---|---|
| 9121 | redis_exporter_port | Redis Exporter port |
The Redis deployment model has these limits:
- Node Exclusive: A node can belong to only one Redis cluster at a time.
- Port Unique: Instances on the same node must use different ports.
- Password Shared: Instances on the same node must share a password because of a redis_exporter limitation.
- Manual HA: Standalone clusters require additional Sentinel configuration for automatic failover.
Monitoring Label System
The built-in monitoring system uses these identity parameters to identify Redis entities.
The labels cls, ins, and ip identify the cluster name, instance name, and node IP. They accompany job in all Redis metrics collected by VictoriaMetrics. The Redis metrics job is always redis.