Service/Access
Split read and write operations, route traffic correctly, and reliably deliver PostgreSQL cluster capabilities.
A service exposes database cluster capabilities to clients. It hides the details of the underlying cluster.
Services provide stable access in production, including after automatic failover in high-availability clusters. Single-node users usually do not need services.
Personal User
Services are intended for production environments. Personal users and single-node clusters can connect directly through an instance name or IP address.
For example, Pigsty’s default single-node pg-meta.meta database can be directly connected using three different users:
Service Overview
Production environments use primary-replica clusters with replication. Exactly one instance, the primary, leads the cluster and accepts writes. Replicas continuously fetch change logs from the primary to keep their data consistent. Replicas also handle read-only requests, which substantially reduces primary load in workloads with many reads. Thus, separating write requests from read-only requests is common.
For frequent short connections, Pgbouncer pools requests to reduce the cost of connection and backend process creation. Operations such as ETL and database changes need direct connections that bypass the pool. Failures in high-availability clusters can trigger failover and change the primary. Write traffic must follow the new primary automatically. Services represent these access requirements: separate reads and writes, pooled or direct connections, and automatic routing after failover.
Typically, database clusters must provide this most basic service:
- Read-write service (primary): Can read and write to the database
For production database clusters, at least these two services should be provided:
- Read-write service (primary): Write data: Only carried by the primary.
- Read-only service (replica): Read data: Can be carried by replicas, but can also be carried by the primary if no replicas are available
Additionally, depending on specific business scenarios, there might be other services, such as:
- Default direct access service (default): Service that allows (admin) users to bypass the connection pool and directly access the database
- Offline replica service (offline): Dedicated replica that doesn’t handle online read-only traffic, used for ETL and analytical queries
- Synchronous replica service (standby): Read-only service with no replication delay, handled by synchronous standby/primary for read-only queries
- Delayed replica service (delayed): Access older data from the same cluster from a certain time ago, handled by delayed replicas
Default Service
By default, Pigsty provides four services for each PostgreSQL cluster:
| Service | Port | Description |
|---|---|---|
| primary | 5433 | Production read-write, connect to primary pool (6432) |
| replica | 5434 | Production read-only, connect to replica pool (6432) |
| default | 5436 | Admin, ETL writes, direct access to primary (5432) |
| offline | 5438 | OLAP, ETL, personal users, interactive queries |
Taking the default pg-meta cluster as an example, it provides four default services:
From the sample cluster architecture diagram, you can see how these four services work:
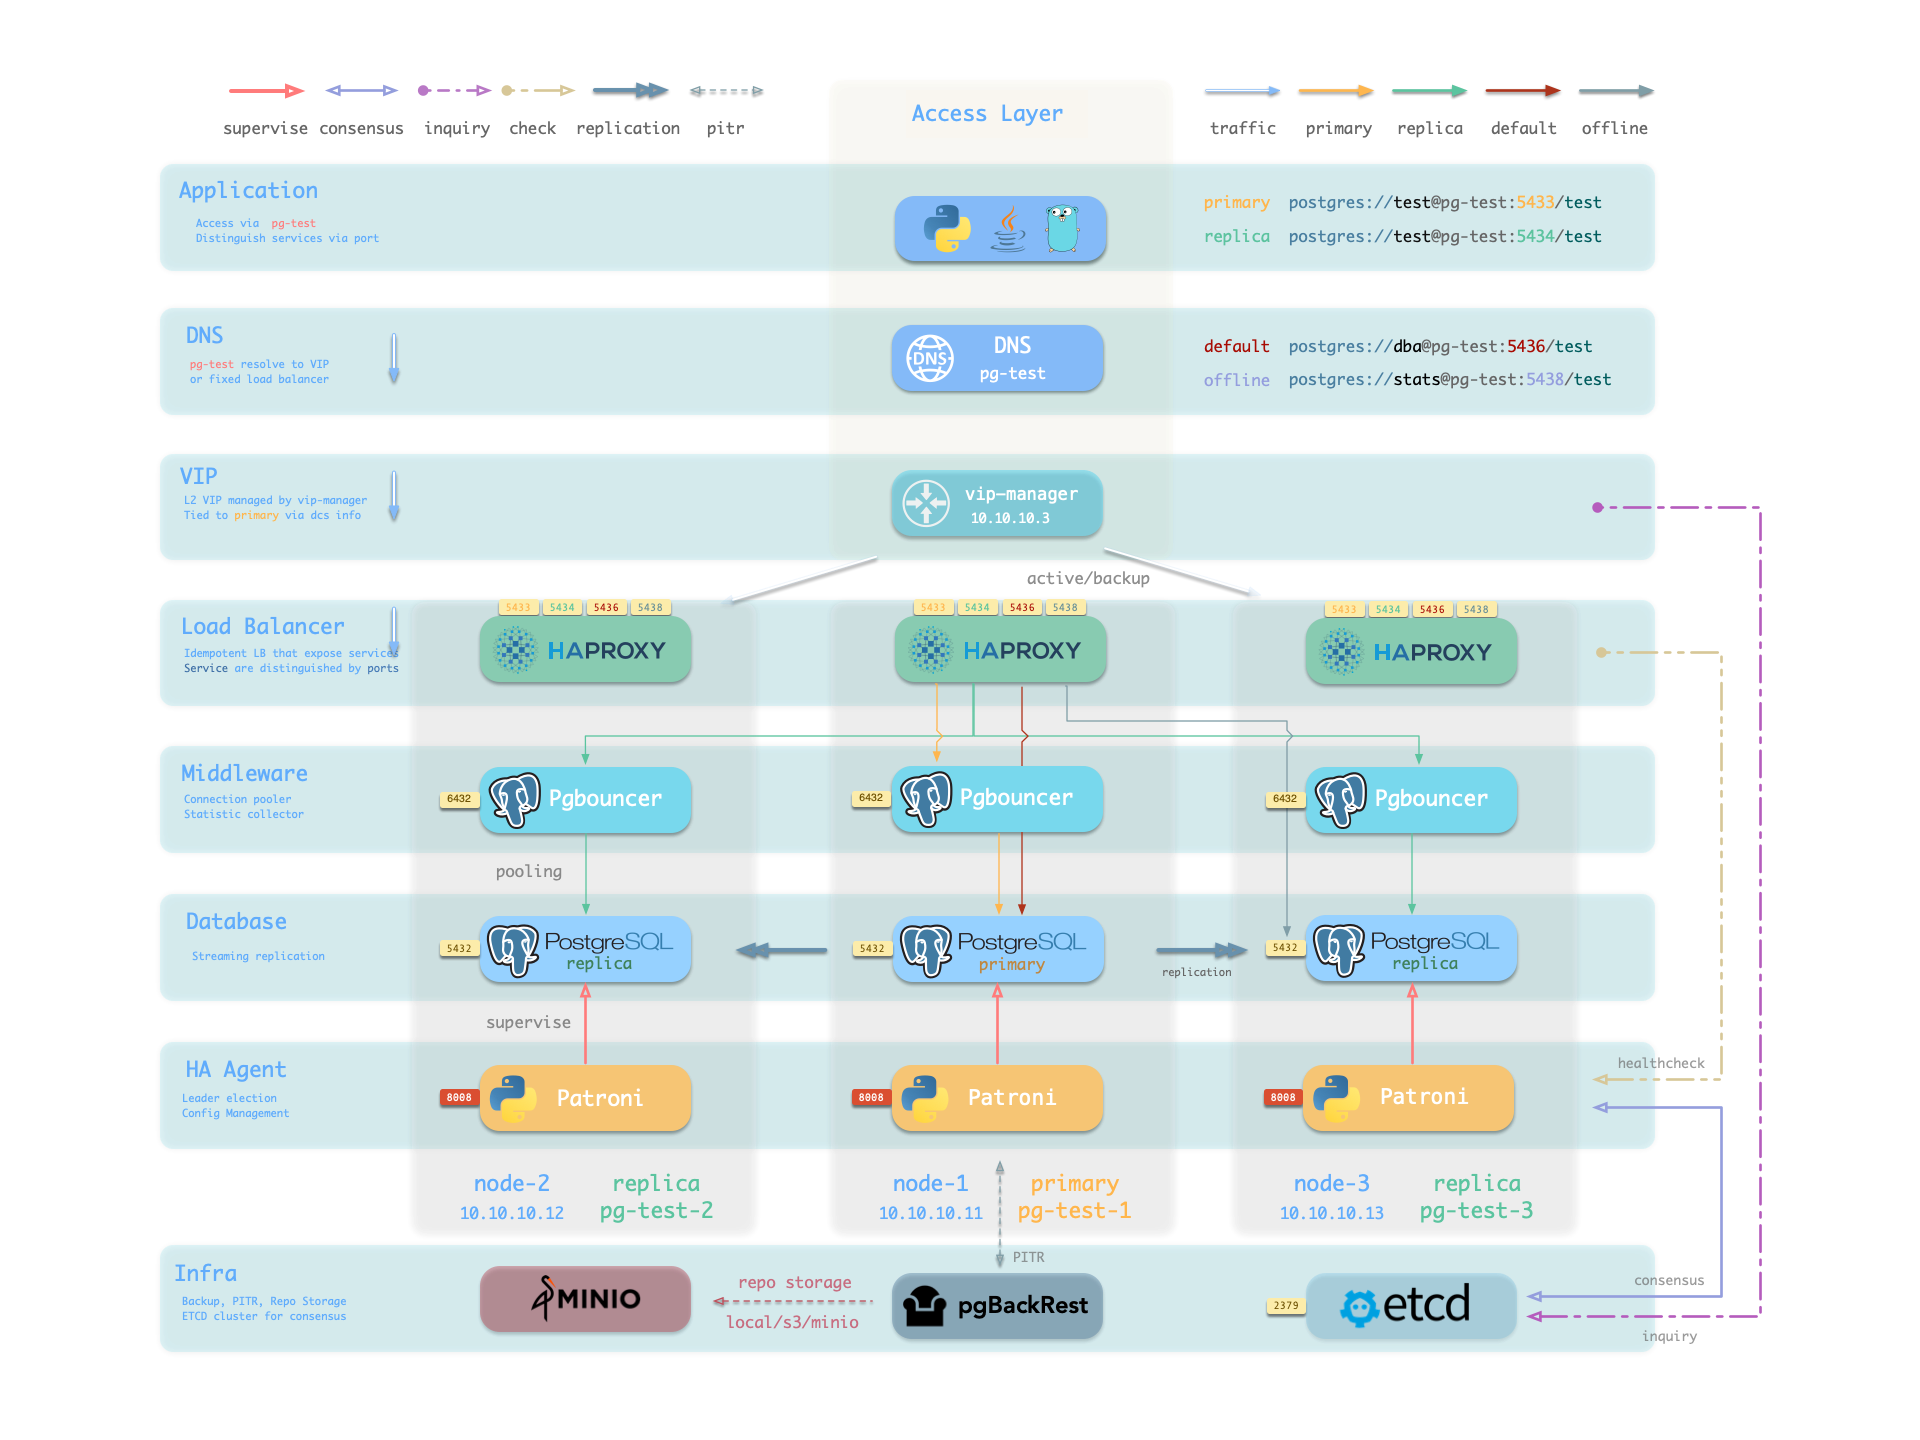
pg_dns_target controls the DNS target of pg-meta.
The default, auto, selects the L2 VIP when enabled.
Otherwise, it selects the IP address of the inventory primary.
VIP is disabled by default.
See Accessing Services.
Service Implementation
Pigsty implements services with HAProxy on nodes. Different ports identify different services.
Pigsty enables HAProxy on each managed node, including database nodes. Database nodes have primary or replica roles, but each node exposes the same services. With the correct service port, you can access the primary read-write service through a replica node. Thus, access to any cluster instance gives access to all cluster services.
This design is similar to Kubernetes NodePort services. Each Pigsty service has two core elements:
- Access endpoints exposed via NodePort (port number, from where to access?)
- Target instances chosen through Selectors (list of instances, who will handle it?)
Pigsty provides services up to the cluster HAProxy endpoint. Clients can reach these load balancers in several ways. See Accessing Services.
Declare all services in configuration files.
For example, pg_default_services defines the default PostgreSQL services:
Define additional services in pg_services.
Both pg_default_services and pg_services are arrays of service definition objects.
Define Service
Pigsty allows you to define your own services:
pg_default_services: Services uniformly exposed by all PostgreSQL clusters, with four by default.pg_services: Additional PostgreSQL services, can be defined at global or cluster level as needed.haproxy_services: Directly customize HAProxy service content, can be used for other component access
For PostgreSQL clusters, you usually need only the first two parameters.
Each service generates a configuration file on every related HAProxy instance: /etc/haproxy/conf.d/<pg_cluster>-<service>.cfg.
The following custom standby service provides read-only access without replication lag.
Add its definition to pg_services:
For the three-node pg-test example cluster, Pigsty generates /etc/haproxy/conf.d/pg-test-standby.cfg from this definition:
The selector: "[]" expression includes all three pg-test instances in the pg-test-standby backend list.
However, the Patroni /sync health check returns HTTP 200 only for the primary and synchronous standby.
Only those instances can handle requests.
The primary also matches pg_role == primary, so the backup selector marks it as a backup server.
It handles requests only when no synchronous standby can do so.
Primary Service
The Primary service provides cluster read-write access on port 5433. It is a critical production service. Its definition is:
selector: "[]"includes all cluster members in the Primary service.- Only the primary passes
check: /primaryand receives traffic. dest: defaultmakespg_default_service_destcontrol the destination.- Pigsty replaces the
destvaluedefaultwithpg_default_service_dest, whose default ispgbouncer. - Thus, the default destination is the primary connection pool on
pgbouncer_port, normally 6432.
Set pg_default_service_dest to postgres to bypass the connection pool.
The Primary service then connects directly to pg_port, normally 5432.
Use this setting when you do not need pooling.
Example: pg-test-primary haproxy configuration
Patroni high availability ensures that no more than one instance passes the /primary health check at a time.
Thus, the Primary service always routes traffic to the primary.
The Primary service also protects traffic routing during a split-brain condition. For example, kill -9 can stop primary Patroni without a watchdog. HAProxy sends traffic only when Patroni is alive and reports primary status. This protection is unavailable with a direct database connection.
Replica Service
The Replica service provides read-only access on port 5434. It is the next most important production service after Primary. Its definition is:
selector: "[]"includes all cluster members in the Replica service.- All instances can pass
check: /read-onlyand receive traffic. - The backup selector
[? pg_role == 'primary' || pg_role == 'offline' ]marks the primary and offline replicas as backups. - The primary or offline replicas receive traffic only when all normal replicas are down.
dest: defaultmakespg_default_service_destcontrol the destination.- Pigsty replaces the
destvaluedefaultwithpg_default_service_dest, whose default ispgbouncer, as for the Primary service. - Thus, the default destination is the replica connection pool on
pgbouncer_port, normally 6432.
Example: pg-test-replica haproxy configuration
The Replica service first sends read-only requests to available dedicated replicas. It sends them to the primary only when all replicas are down. For a two-node primary-replica cluster, this means it uses the replica while available and the primary when the replica fails.
The Replica service uses dedicated Offline instances only when all dedicated read-only instances are down. This separates fast online queries from slow offline queries to reduce interference.
Default Service
The Default service provides service on port 5436, and it’s a variant of the Primary service.
The Default service always bypasses the connection pool and connects directly to primary PostgreSQL. Use it for administration connections, ETL writes, and change data capture (CDC).
If pg_default_service_dest is postgres, Default and Primary have the same behavior.
Only their names and ports differ.
In this case, you can remove Default from the default services.
Example: pg-test-default haproxy configuration
Offline Service
The Offline service listens on port 5438 and connects directly to PostgreSQL without the pool. Use it for slow queries, analytical queries, ETL reads, and personal interactive queries:
Offline routes traffic directly to dedicated offline replicas.
It can also use normal read-only instances with the pg_offline_query flag.
- The selector includes replicas with
pg_role=offlineand normal read-only instances withpg_offline_query=true. - Dedicated offline replicas do not handle Replica service requests by default. This separates fast and slow requests. Flagged normal replicas do handle those requests.
- The backup selector includes normal replicas without the offline flag. They handle Offline traffic when dedicated or flagged offline instances fail.
/replicareturns HTTP 200 only for replicas. It rejects the primary, even when the primary is the only remaining cluster instance.- Neither selector includes the primary. Thus, Offline traffic never reaches or affects the primary.
Example: pg-test-offline haproxy configuration
Offline provides restricted read-only access for personal interactive queries, slow analytical or ETL queries, and long transactions.
The Offline service needs special handling after a switchover.
The HAProxy /replica health check automatically rejects the new primary.
However, selector uses static pg_role and pg_offline_query inventory labels.
In a two-node primary-replica cluster, only the replica may serve Offline queries.
A switchover can then leave no eligible backend temporarily.
Reloading an unchanged inventory does not add the old primary to the backend list.
First update the inventory labels or pg_offline_query for the new plan, then reload services.
Alternatively, switch the primary back.
For a simple business model, you can remove Default and Offline. Use Primary and Replica to connect directly to the database.
Reload Service
Reload services after changes to cluster membership, service definitions, static selector labels, or relative weights. Patroni health checks handle normal Primary and Replica switchovers automatically. These switchovers need no separate reload.
Access Service
Pigsty provides services up to the cluster HAProxy endpoint. Clients can reach these load balancers in several ways.
The typical approach is to use DNS or VIP access, binding to all or any number of load balancers in the cluster.
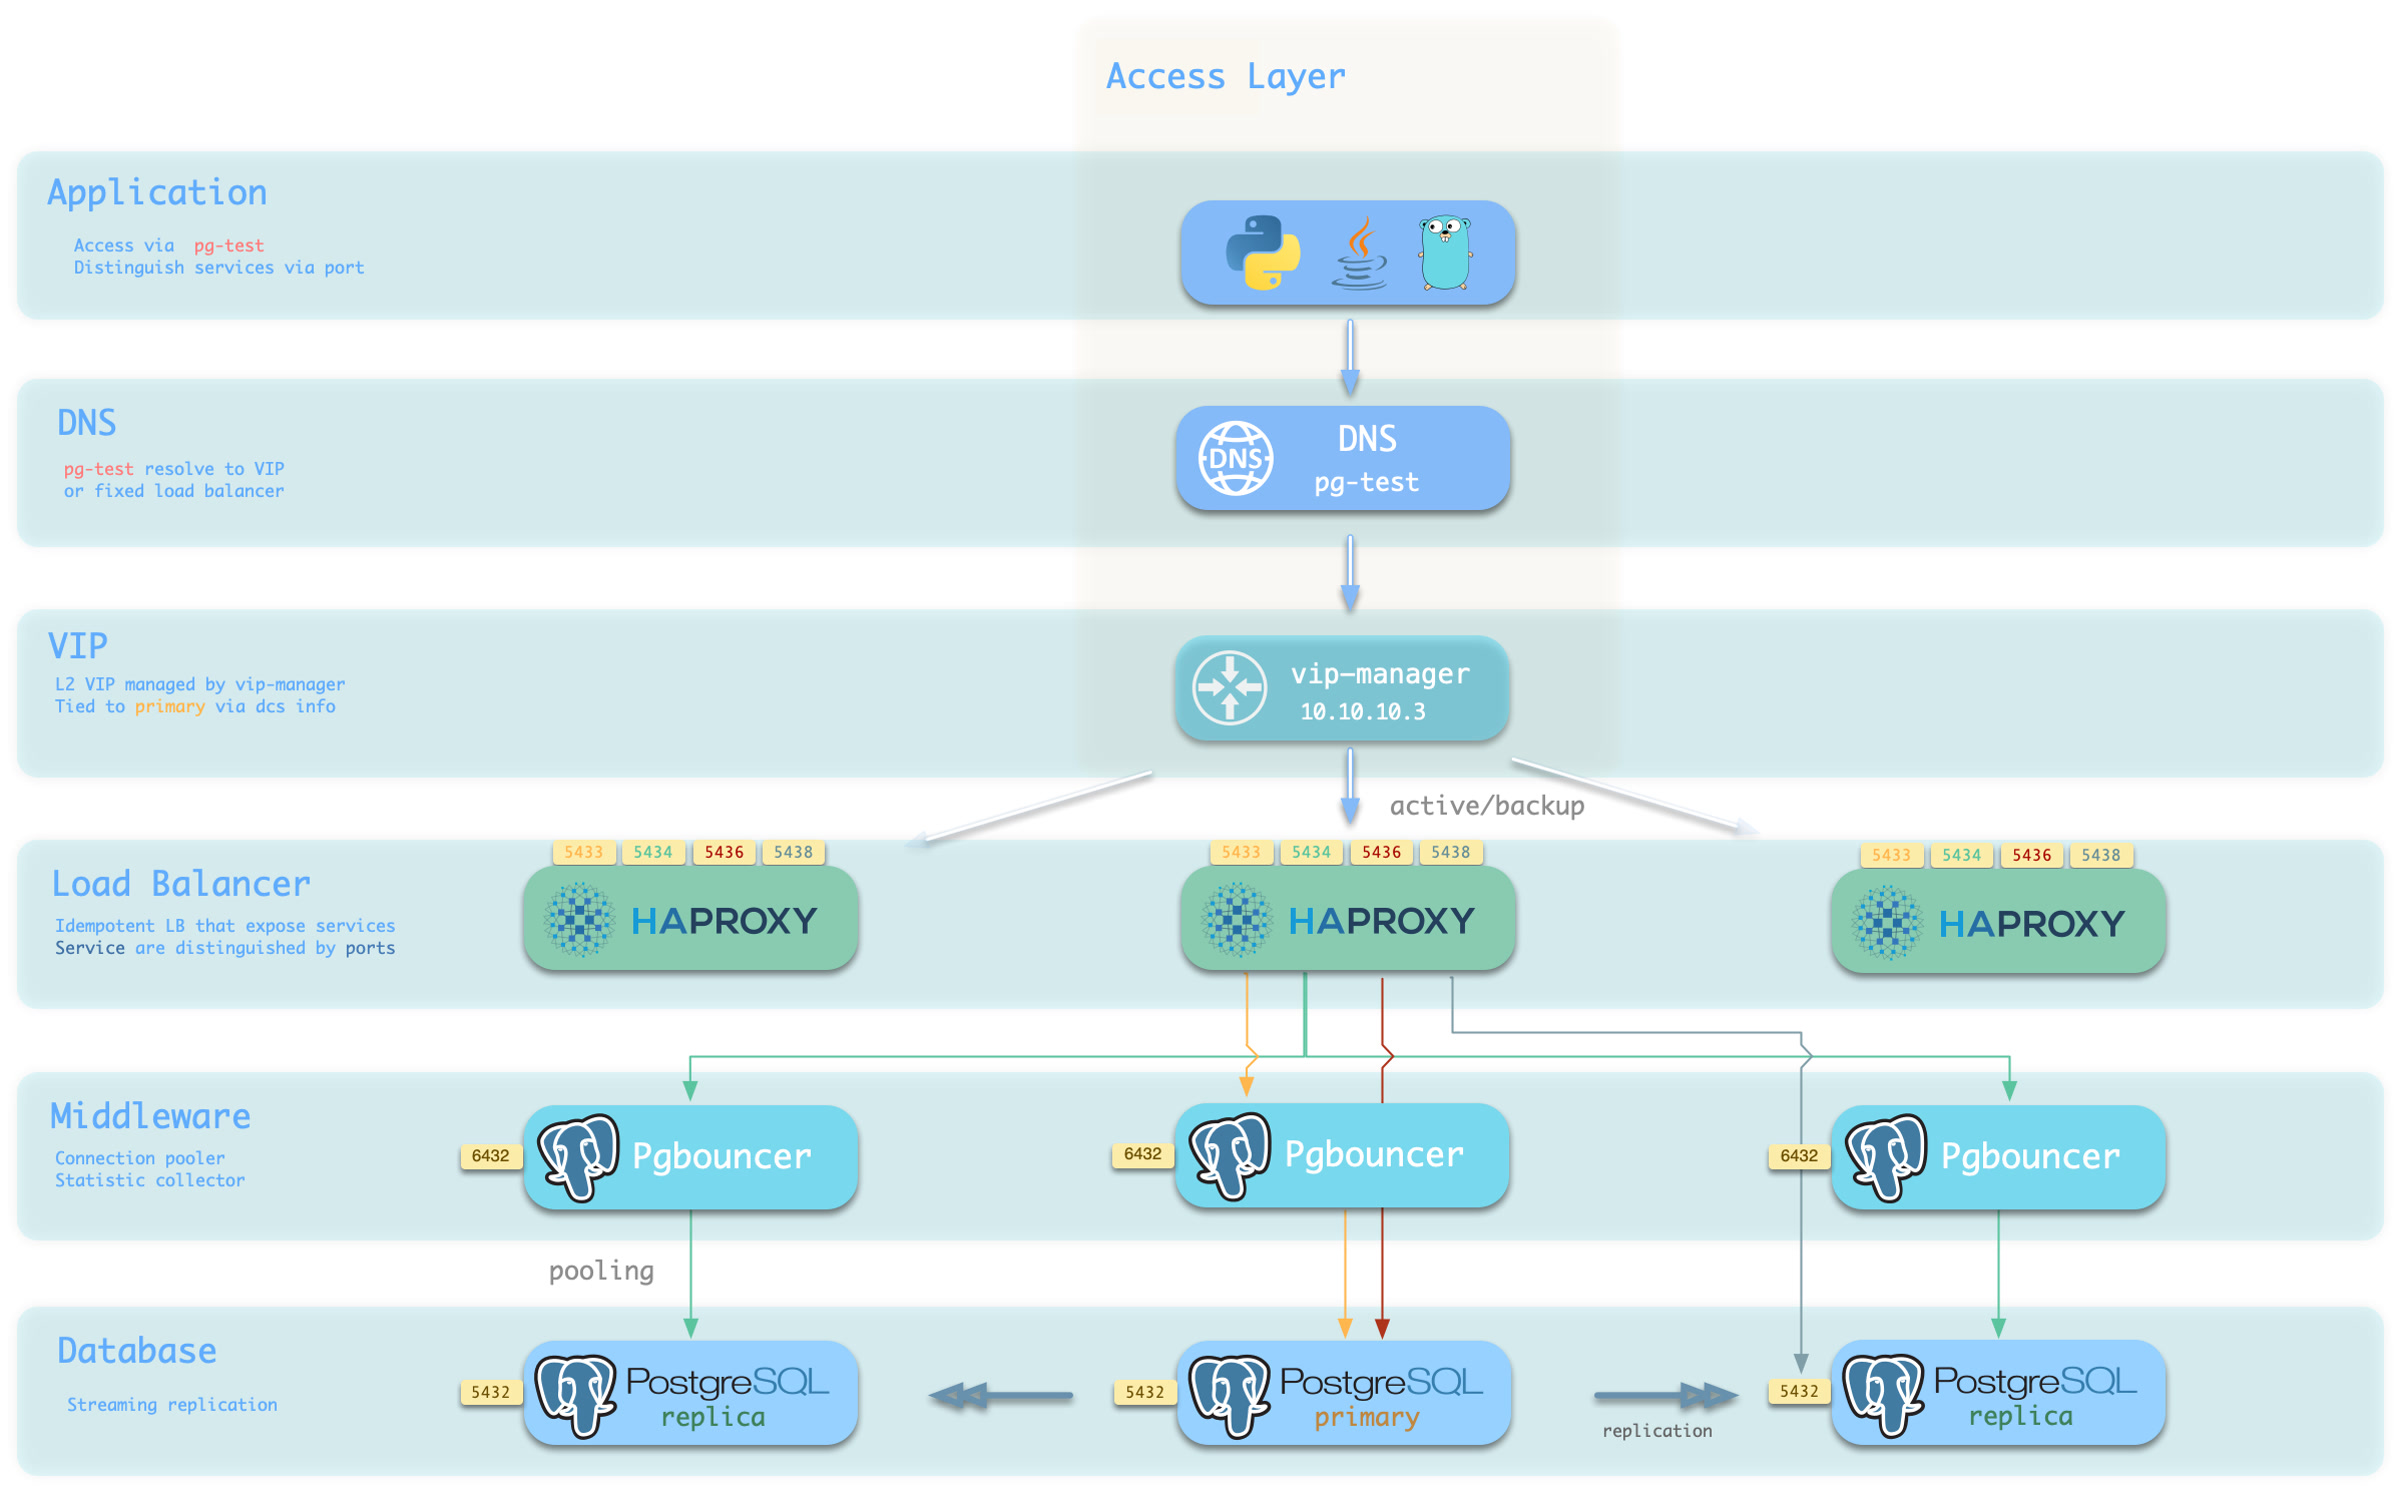
You can use different host & port combinations, which provide PostgreSQL services in different ways.
Host
| Type | Example | Description |
|---|---|---|
| Cluster Domain Name | pg-test | Access via cluster domain name (resolved by dnsmasq @ infra nodes) |
| Cluster VIP Address | 10.10.10.3 | Access via L2 VIP address managed by vip-manager, bound to primary |
| Instance Hostname | pg-test-1 | Access via any instance hostname (resolved by dnsmasq @ infra nodes) |
| Instance IP Address | 10.10.10.11 | Access any instance IP address |
Port
Pigsty uses different ports to distinguish pg services
| Port | Service | Type | Description |
|---|---|---|---|
| 5432 | postgres | database | Direct access to postgres server |
| 6432 | pgbouncer | middleware | Go through connection pool middleware before postgres |
| 5433 | primary | service | Access primary pgbouncer (or postgres) |
| 5434 | replica | service | Access replica pgbouncer (or postgres) |
| 5436 | default | service | Access primary postgres |
| 5438 | offline | service | Access offline postgres |
Combinations
Override Service
You can override service defaults in several ways. A common requirement is for Primary and Replica to bypass Pgbouncer and connect directly to PostgreSQL.
Set pg_default_service_dest to postgres.
Services with svc.dest='default' then use postgres instead of the default pgbouncer destination.
If Primary already connects to PostgreSQL, Default is redundant. You can remove it.
If you do not need to distinguish personal interactive queries from slow analytical or ETL queries, you can remove Offline.
Remove it from pg_default_services.
If replicas do not need to handle online read-only traffic, you can remove Replica from the default list.
Delegate Service
Pigsty exposes PostgreSQL services through HAProxy on nodes. All HAProxy instances in a cluster use the same service definitions.
You can instead delegate PostgreSQL services to a specific node group, such as a dedicated HAProxy load balancer cluster.
Override pg_default_services and set pg_service_provider to the proxy group name.
This example exposes the PostgreSQL Primary service on port 10013 through the proxy HAProxy node group.
Use a unique port for each delegated service in the proxy cluster.
A dedicated load balancer cluster example is provided in the 20-node production environment simulation sandbox: conf/ha/simu.yml
Was this page helpful?
Thanks—your feedback helps us improve this page.
What got in the way? (optional)